1 Contracts and cost models
When I use a word, it means just what I choose it to mean — neither more nor less.
Humpty Dumpty, in Lewis Carroll’s Through the Looking-Glass (1871)
1.1 Nine balls and a balance scale
Before choosing an algorithm or a data structure, two questions come first. What does it promise? What does it cost?
Neither question means much until it is made precise. Start with cost, on a problem small enough to count everything by hand.
You have nine balls. One is slightly heavier. The other eight are identical. You have a balance scale. Each weighing tells you that the left side is heavier, the right side is heavier, or the two sides balance.
Find the heavy ball.
What is the smallest number of weighings that always works? And how do you know nobody can do better?
Five minutes and a pen. You’re done when you have a number and a reason nobody can beat it.
Finding the ball in two weighings is fairly easy. Split the balls into three groups of three and weigh two groups against each other.
The harder question is why one weighing can never be enough. That why is the reusable idea.
1.1.1 Every strategy is a tree
Each weighing has three possible outcomes:
- left heavier,
- right heavier, or
- balanced.
So a complete strategy can be drawn as a ternary decision tree, one in which each question splits three ways. A tree with \(w\) levels of questions, its depth, has at most \(3^w\) leaves, the end points where the answer is known. To tell \(n\) balls apart you need at least \(n\) distinct leaves, so \(3^w \ge n\), which means at least \(\lceil \log_3 n \rceil\) weighings, where \(\lceil \cdot \rceil\) means round up to the next integer. No cleverness escapes it.1
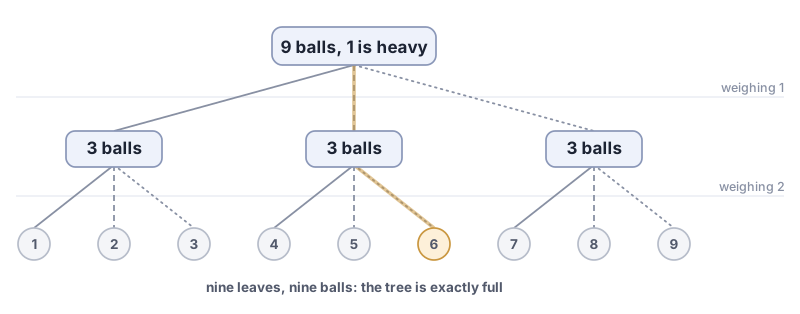
Primitive: the adversary / decision-tree lower bound. When every step yields one of \(b\) answers, \(w\) steps produce at most \(b^w\) distinct outcomes. If the task needs \(N\) distinct outcomes, then \(w \ge \log_b N\), no matter the algorithm. The adversary in the name is an imagined opponent who, at every step, gives the answer that keeps the most outcomes still open.
Ternary division meets that bound exactly. Split into three near-equal groups and weigh two of the same size. If one group is heavier, it contains the heavy ball. If the pans balance, the heavy ball is in the group left off. A solver that does this never needs more than \(\lceil \log_3 n \rceil\) weighings, wherever the heavy ball is.2 This is the same primitive as binary search, where each yes-or-no answer gives \(b = 2\) and you need \(\log_2 n\) questions.
1.1.2 Why no sort can be faster
The same count settles something far larger than a puzzle. A comparison sort learns about its input only by comparing two items at a time (“is this one smaller than that one?”), so it too is a decision tree, this time with \(b = 2\). It has to tell apart all \(n!\) possible orderings of \(n\) distinct items, because each one needs a different rearrangement to put it in order. So in its worst case it needs at least \(\log_2(n!)\) comparisons. For large \(n\) that number grows very nearly like \(n \log_2 n\). That is a floor under every comparison sort that will ever be written, including the ones nobody has imagined yet.
Hold onto that sentence. The shorthand for saying it arrives under “How fast does the cost grow?”, and reading that shorthand correctly is the part that most people get wrong.
1.1.3 The same trick, everywhere
A primitive is a small idea that keeps turning up inside different algorithms, and the decision-tree count is the first one. It is a factory for certificates, proofs you can check for yourself. A certificate turns “I cannot see how to do better” into “no one can, here is the proof.” The count recurs whenever each answer comes from a short, fixed list of possibilities, and here it is three times:
- Ball weighing composes it with divide and conquer. Divide into three, and the lower bound says three-way division is optimal.
- Comparison sorting composes it with counting orderings (\(n!\)) to bound every such sort at once.
- Searching a sorted array of \(n\) items needs at least \(\log_2 n\) comparisons, for the same reason. Each comparison answers yes or no, and \(n+1\) possible answers have to be told apart, one for each position and one more for “not here at all”.
The move to take with you is to count the outcomes that the task demands, count the outcomes that one step supplies, and divide their logarithms. For the nine balls, nine outcomes are needed and a weighing supplies three, so \(\log 9 / \log 3 = 2\). That single ratio is a lower bound you can state before writing any code.
The idea of a certificate works on answers too. A lower bound is a certificate that nobody can do better. A sorted list beside the input it rearranges is a certificate that this particular answer is right. Either way, what you are handed is something you can check yourself, instead of a claim you have to take on trust.
Key idea: certificate
A certificate is evidence handed over beside an answer. Anyone can check it quickly, much faster than solving the problem again, and the check needs no trust in whoever produced the answer.
1.1.4 Three tools to reuse
Three more primitives set the language the book reuses everywhere:
- Keep an invariant. Choose a property and keep it true after every step. In a loop it is a loop invariant, true before the loop starts and after every pass through it. When the loop ends, the invariant proves the answer correct. Binary search keeps the sentence “the target, if present, lies in
[lo, hi]” true throughout, where[lo, hi]is the stretch of the sorted list between positionsloandhi. - Monovariant. An integer that strictly moves one way and cannot pass a limit. Finding one proves termination. In the puzzle, each weighing shrinks the candidate set, whose size cannot go below one, so the process must end.
- Splitting the problem: the master theorem. A method that divides and conquers solves a big case by solving smaller copies of itself. Its cost is settled by weighing the work done dividing and recombining at the top against the work piling up in all the small pieces at the bottom. Whichever side is heavier sets the cost. When the two are even, every level costs about the same, and the cost is one level’s work times the number of levels. Binary search is the even case. Each level does one comparison and keeps only one half, so every level costs the same. The cost then grows only with the number of levels, \(\log_2 n\). Merge sort is even too, but with more work per level. Each level of dividing does about \(n\) work in all, and there are \(\log_2 n\) levels, so the total is about \(n \log_2 n\).
1.2 What an algorithm actually spends
1.2.1 Resources
You just counted weighings, and it never occurred to you to count anything else. On that puzzle the scale is the only thing that is scarce, so weighings are the only thing to count. A resource is whatever a computation consumes that can run out, and the one to count is whichever runs out first.
Which one that is depends on the machine and the job as well as the algorithm. The same code can be limited by a different resource on a laptop, on a phone, and on a rack of machines in a data center. These are the ones that come up in this book, in about the order you will meet them:
- Time: steps taken, however a step is defined. It is the default, and the one people mean when they say “faster.” Every chapter counts it.
- Space: how much has to be held at once. Sometimes space alone is the limit. A summary that fits in memory beats an exact answer that does not fit, which is the argument for the small summary structures (sketches) later in the book.
- Block transfers: trips to somewhere slow. Disks and networks hand over a whole block at a time, so what counts is how many trips you made. A structure can do more arithmetic and still win by making fewer trips. Winning that way is the purpose of the search chapter’s B-tree.
- Comparisons, probes, queries: steps of a specific kind, counted when that kind is the expensive one. The puzzle above counted weighings, the sorting bound counted comparisons, and binary search counted probes into an array. Counting one specific operation is what lets you prove a lower bound at all, because it fixes what an algorithm is allowed to learn per step.
- Random bits: coin flips. Some structures buy their guarantee with randomness, and then randomness is a thing being spent.
- Messages and bandwidth: how many messages are sent, and how much data can cross per second. When the computation is spread across machines, what crosses between them usually dominates everything happening inside them.
- Work and span: when many processors run at once, one number stops being enough. You need two, the total work done and the longest chain of steps that must happen in order. The frontier map at the end of this chapter says more.
1.2.2 Trade-offs and cost models
Two things follow from that list, and they are the reason to count resources at all.
The resources trade against each other. Spending space to save time is the oldest move in the book, and an index is exactly that. Spending time to save space is the next oldest. Spending accuracy to save both is also a trade of this kind. Call each quantity on which a design is measured an axis. Time is one, space is another, and accuracy is a third. There is rarely a design that wins on every axis, and a design that seems to win on every axis is usually being measured on too few axes.
Every cost is a cost in a model, and the model is an assumption. Take the claim that an operation is fixed-price, meaning it costs the same no matter how much data you are holding. That claim is never free of assumptions, because it counts some operations and ignores others. The model that most cost claims use is the RAM model, in which every memory read is one step. In a real machine a memory read is something else entirely. When a cost claim surprises you, the model is the first place to look. The model that surprises people most is the one about memory, which comes next.
1.2.3 The memory hierarchy
The RAM model says reading a value from memory costs one step, the same one step, wherever the value happens to be. No real machine has ever worked that way. None works that way now, and none ever will work that way. Two forces make it so, physics and economics. Neither can be bargained with. Both push in the same direction, and what they push into existence is a memory hierarchy, a few levels of places where data can sit. Each level is slower than the one above it, and bigger and cheaper per byte. The gap between neighbors is usually something like an order of magnitude (about ten times), but the drop from memory to flash is much larger. Where that drop falls matters more than any of the individual numbers.
Take one clock cycle of a processor core as the unit. A cycle is the processor’s basic beat, the time that one simple step takes. On a machine running at a few gigahertz (a few billion cycles a second) it is a small fraction of a nanosecond. Everything else is a multiple of that.
For the last column of the table below, stretch a cycle out until it takes one second, and scale everything else by the same factor. That keeps the ratios as they are and puts the numbers in units that a person has lived through. The table’s first three rows are memories on the processor chip itself. Registers hold the values being worked on right now. The caches L1 to L3 are small fast memories that keep copies of recently used data.
| where the data is | how long it takes | vs. one cycle | if a cycle were one second |
|---|---|---|---|
| register, L1 cache | a cycle to a few cycles | \(\times 1\) to \(\times 5\) | a second to a few seconds |
| L2 cache | a few nanoseconds | \(\times 10\) | ten seconds or so |
| L3 cache | tens of nanoseconds | \(\times 10^2\) | about a minute |
| main memory (DRAM) | around a hundred nanoseconds | \(\times 10^{2\text{–}3}\) | a few minutes |
| flash (SSD) | tens of microseconds | \(\times 10^5\) | a day or two |
| another machine in the same building | tens to hundreds of microseconds | \(\times 10^{4\text{–}6}\) | hours to weeks |
| a seek on a spinning disk | milliseconds | \(\times 10^7\) | months |
| a machine on the other side of the planet | around a hundred milliseconds | \(\times 10^{8\text{–}9}\) | a decade |
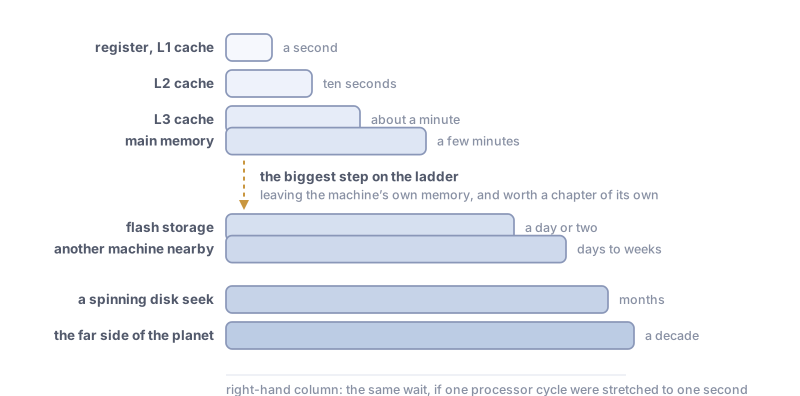
In the last column’s units, a program that goes to main memory for every value is a person who stops work for a few minutes on every single line. A program that goes to disk for every value has stopped for months. Differences this large are too big to wave away as “only a constant factor”. The chapter makes that phrase precise in “How fast does the cost grow?”
The digits in that table will go stale, and the shape will not go stale. Absolute latencies (how long one access takes) move. Levels get inserted. Flash was not always there, and in the 2020s a new level began to appear, memory attached over a fast link that keeps all the caches’ copies in agreement. Levels also fall out of use. Spinning disks have left many systems entirely. What does not move is the ordering, the order-of-magnitude gaps between neighbors, and the fact that any level invented tomorrow will slot into the same hierarchy and obey the same rule. That is why this book prints ratios and units named in words (“a few minutes”, “months”).
1.2.4 ★ Why the hierarchy is unavoidable advanced
Three physical constraints all push the same way.
Distance is time. In one cycle of a few-gigahertz clock, light travels something like ten centimeters in vacuum, and a signal in metal travels less. Anything physically farther away than that cannot possibly answer within a cycle, no matter who builds it or what it is made of. That is the hard floor under the whole table, and it is the reason that the bottom rows are what they are. A machine on the other side of the planet is slow because the planet is that size.
On a chip, the wires are the problem. Shrinking a transistor makes it faster. Shrinking a wire does not make it faster. A thinner wire has more electrical resistance [1], so a signal crawls along it. Transistors have become faster decade after decade, while the delay of a long wire across a chip has stubbornly refused to improve the same way. So the cost of reaching across a chip keeps mattering more.
Fast, dense, cool: pick fewer than three. (Dense means many bits packed into a small area.) A fast memory cell is a big one. Static RAM spends about six transistors per bit and holds its value actively. A dense cell is a slow one. Dynamic RAM spends about one transistor and a capacitor per bit and has to be refreshed. Flash is denser again and slower again. Fast circuits also switch more often, and every switch costs energy that leaves as heat. Heat leaves through a surface, so the fast region has to stay physically small or it cooks.
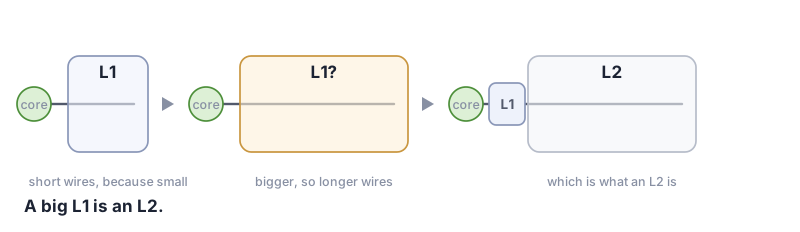
Now put those together. Suppose you want a large, fast memory. Making the fast tier bigger makes it physically larger, which makes its wires longer, which makes it slower, at which point it is no longer the fast tier. You cannot have a big L1 cache. A big L1 cache is an L2. Levels exist because a single large fast memory cannot be built.
Suppose the physics relented. The money would not relent.
Level by level, cost per byte falls as latency rises. Both follow from the same three constraints, seen from the accounting side. Cheap-per-byte is what dense, slow and cool buys you. So a machine built entirely from the top level would cost an absurd amount for a tiny capacity, and a machine built entirely from a bottom level would be affordable, enormous and unusable.
Any builder trying to get the most useful machine for a fixed budget therefore lands on the same answer: a little of the fast stuff, more of the middling stuff, a great deal of the cheap stuff, and some scheme for keeping the data you are about to want near the top. Nobody chose this shape. It is what you get when you minimize cost under those constraints.
1.2.5 ★ Accelerators advanced
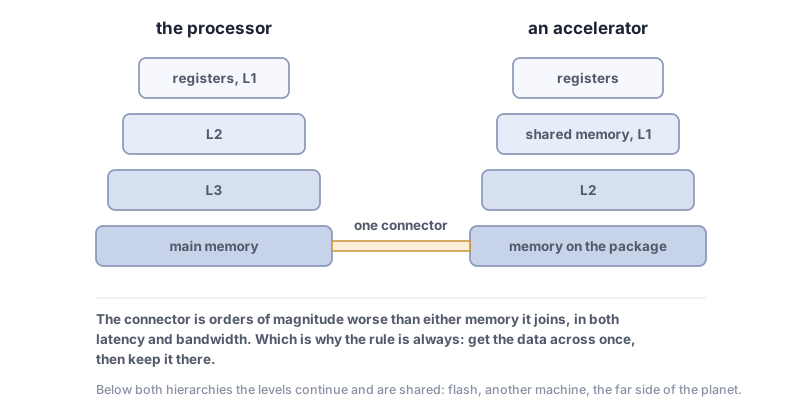
A GPU (a graphics processor, now used for much more than graphics) obeys all of this, and the way it obeys is instructive. It has its own levels, in the same order and with the gaps just as wide: a very large register file; then shared memory for each group of threads, and L1; then L2; then the high-bandwidth memory sitting on the package. Past that, a bridge leads across to the host computer’s memory, and from there down the host’s entire hierarchy as before.
The bridge decides the program. The hop between the accelerator’s own memory and the host’s crosses a physical connector whose bandwidth is more than an order of magnitude lower than that of the accelerator’s own memory. That is why almost every rule of thumb in accelerator programming is some version of get the data across once and keep it there. An algorithm with a worse operation count that crosses the bridge fewer times routinely wins by a margin that no amount of better arithmetic can recover. Some designs, though, put the processor and the accelerator on one package with one shared memory. There the bridge shrinks or disappears, and the levels above it are what decide the program.
A GPU answers the same physics differently, not better. Instead of making one memory access fast, it runs enormous numbers of threads and switches between them, so that while some are waiting for memory others are working. The latency is still there, in full, and is being hidden behind bandwidth. That trade is why GPUs want work shaped as many independent pieces touching memory in regular, adjacent patterns, and why an algorithm full of unpredictable jumps runs badly on one even when its operation count is excellent.
Everything above generalizes to every other kind of processor. A machine can hold a CPU, one or more accelerators, a neural processing unit and memory attached over an interconnect. Such a machine is several hierarchies, joined at their slow ends. Adding devices adds levels far more often than it removes them. When a design does remove one, the rest of the hierarchy is still there. The two forces above say it always will be there. The safe prediction about hardware that does not exist yet is that it will have a hierarchy of the same shape, for the same reasons.
1.2.6 Consequences for algorithms
Two programs with identical operation counts can differ by orders of magnitude. Usually the difference is that one of them walks through memory in order while the other jumps around. The count was never the whole cost. Where the data was, and how often it had to move, was the rest of it.
That is why a single cost model is not enough, and why this book uses more than one. Counting steps is the default. The second model counts block transfers, the trips to a slower level, each bringing back a whole block whether you wanted all of it or not. This model explains why a structure doing more arithmetic can be faster. It is the model the search chapter switches to when it builds the B-tree. Counting transfers without knowing the block size is a third model, to which the frontier map at the end of this chapter points. A structure that turns scattered writes into sequential ones, like the LSM-tree in the search chapter, is answering the same pressure from another side.
Before asking how many operations something does, make a habit of asking where the data lives, and how many times it has to move. On modern hardware that question is usually the one that decides the answer.
1.3 How fast does the cost grow?
Back to counting, now that you know what to count. Once you have picked the resource (steps, bytes held, trips to a slower level), one question is left, and every cost claim in this book is an answer to it. How does that count grow as the input gets bigger? Nobody cares about the count at \(n = 10\). Everybody cares what happens at \(n = 10\) million.
1.3.1 At most, at least, exactly
Three symbols carry this, each saying something different about a count \(f(n)\):
- \(O(g(n))\): no worse than \(g\), for large \(n\), ignoring constant factors. An upper bound on the count’s growth.
- \(\Omega(g(n))\): no better than \(g\). A lower bound on the count’s growth, and usually bad news.
- \(\Theta(g(n))\): both at once. The growth is fixed, no worse and no better. When you know this much, say \(\Theta\), not \(O\).
Formally, \(f(n) = O(g(n))\) means there are constants \(c > 0\) and \(n_0\) with \(f(n) \le c\,g(n)\) for every \(n \ge n_0\), while \(\Omega\) turns the inequality around, and \(\Theta\) asks for both.
“Ignoring constant factors” hides a lot in all three. \(\Theta(n)\) says nothing about whether a step takes a nanosecond or a minute. It says that once \(n\) is large, the total stays within fixed multiples of \(n\). Constants decide which of two programs you ship. Growth decides which of them still works next year. Ignoring constant factors is also why \(O\), \(\Omega\) and \(\Theta\) write a logarithm without its base, since changing the base only multiplies the logarithm by a constant.
1.3.2 What each growth rate feels like
The table below is about a count, and it applies to whatever is being counted: weighings, comparisons, bytes held, trips to disk.
The column “\(n\) affordable in a second” assumes a machine doing a billion steps a second and one second of patience. It is a rough number and it is meant to be rough. Read it for the shape.
| growth | when \(n\) doubles, the cost | \(n\) affordable in a second | the feeling |
|---|---|---|---|
| \(1\) | does not move | anything at all | free; size never enters it |
| \(\log n\) | goes up by one step | anything you can store | practically free, forever |
| \(\sqrt{n}\) | grows by about 40% | \(10^{18}\) | comfortable, quietly growing |
| \(n\) | doubles | \(10^9\) | fair: you looked at everything once |
| \(n \log n\) | slightly more than doubles | \(4 \times 10^7\) | the working limit of “still fine” |
| \(n^2\) | quadruples | \(30{,}000\) | fine in testing, dead in production |
| \(n^3\) | goes up eight times | \(1{,}000\) | only ever for small \(n\), and you know it |
| \(2^n\) | squares | \(30\) | one more item doubles everything |
| \(n!\) | worse than squares | \(12\) | a wall, not a slope |
Those are shapes. Here is each one as something you have felt:
- \(\mathbf{1}\): reaching for a light switch you have used a thousand times. The size of the room never came into it.
- \(\log n\): guessing a number between one and a million by halving the range. A million possibilities, twenty guesses. Widen it to two million and you ask one more question.
- \(\sqrt{n}\): a filing cabinet with \(\sqrt{n}\) drawers holding \(\sqrt{n}\) files each. Scan the drawer labels, then scan one drawer. Twice the files makes each of those jobs 40% longer, not twice as long.
- \(n\): reading every name on the guest list to find one person. Twice the guests, twice the reading. Nothing clever, nothing pathological.
- \(n \log n\): sorting a deck by merging piles. Every card is handled once each time its pile doubles. Barely worse than reading them all, which is why this is the workhorse of the whole field.
- \(n^2\): every guest shakes hands with every other guest. The tenth guest adds nine handshakes. The hundredth adds ninety-nine. Each new arrival costs more than the last one did, so a quadratic program is fine at the size you tested and hopeless at the size you shipped.
- \(n^3\): the same handshakes, but every handshake has to be witnessed by every guest.
- \(2^n\): deciding separately for each guest whether to invite them, and examining every possible guest list. One more name on the list doubles the work, every single time.
- \(n!\): seating every guest in every possible order. Twelve guests take about half a second. The thirteenth guest makes it six seconds, and the fourteenth guest makes it a minute and a half. Twenty guests take a human lifetime, and twenty-six guests take the age of the universe.
The gap between the last two rows and everything above them is a difference of kind. Every row down to \(n^3\) is a program that gets slower as the data grows. \(2^n\) and \(n!\) are programs that stop working. A machine ten times faster moves the wall by three items for \(2^n\), and by one item for \(n!\).
1.3.3 Which run do you mean?
The symbol says how a count grows. It does not say which run you are counting. That is a separate question, and five phrases answer it throughout this book. Any of them can be attached to any of the growth rates above:
- Worst case. The most expensive input of that size. It is the default in this book, and the only one that holds for every input on every run.
- Average case. Averaged over inputs, under some stated distribution of them, an assumption about how likely each input is. Such a bound is only as good as that stated distribution, which is usually the assumption that breaks.
- Amortized. Averaged over a run of operations on one structure, whatever the input. It says a long sequence is cheap in total but says nothing about the one operation on which you are waiting. A growable array is the classic case. Exercise 6 in the self-check problems has you prove it.
- Expected. Averaged over the algorithm’s own coin flips, for a fixed input. Unlike average case, it holds for every input, even one chosen to make the algorithm slow, because the randomness is yours.
- With high probability (w.h.p.). Not an average at all. The bound holds except on a vanishingly small fraction of coin flips, usually at most \(1/n^c\) for a constant \(c\). It bounds how often a run is bad, and leaves open how bad the rare bad run is. That makes it a different kind of bound from an expected bound.
| kind of bound | what varies | what is guaranteed |
|---|---|---|
| worst case | the input; the worst one of that size is taken | the bound, on every input and every run |
| average case | the input, drawn from a stated distribution | the bound on average, if the inputs really follow that distribution |
| amortized | where you are in a run of operations on one structure | the total for the run, not any single operation |
| expected | the algorithm’s own coin flips, for a fixed input | the bound on average over the coin flips, for every input |
| w.h.p. | the algorithm’s own coin flips | the bound on all but a vanishingly small fraction of coin flips, not how bad those are |
“\(O(1)\) amortized” and “\(O(1)\) worst case” are different bounds on the same growth rate, and a system that needs every single operation to be fast cannot be built on the first, however good its total looks.
1.3.4 Slow code or a hard problem?
A bound can be about one algorithm or about a whole problem, and confusing the two is a common mistake.
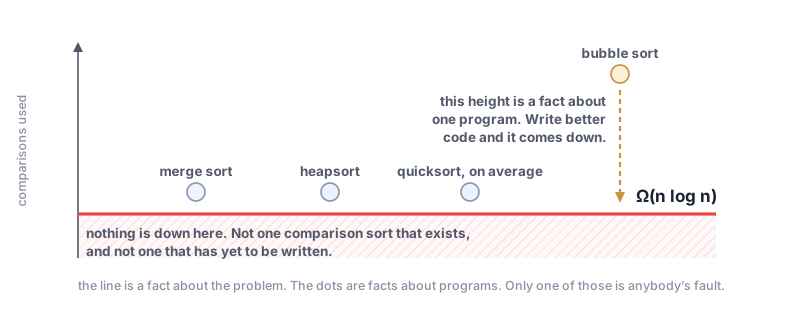
“This algorithm takes \(\Omega(n^2)\) steps” says this code is slow. Write better code.
“Sorting by comparisons takes \(\Omega(n \log n)\) comparisons” says no code can do better, ever, including code nobody has written. That is a statement about the problem, and it is what the decision-tree count in “Why no sort can be faster” proved.
Someone tells you they have a sorting algorithm that runs in \(O(n \log n)\), and someone else tells you bubble sort runs in \(O(n \log n)\). One of those is ordinary, and the other is wrong. Before reading on, say which, and say exactly which bound is being confused with which.
Bubble sort is not \(O(n \log n)\). The \(\Omega(n \log n)\) result is a lower bound on the whole class of comparison sorts, not an upper bound on any one algorithm in it. A floor under everybody says nothing about how high above the floor one particular algorithm sits. Bubble sort makes about \(n^2/2\) comparisons in the worst case. It is quadratic, and the lower bound is perfectly happy about that.
1.4 When there is no single best
Everything so far has been about measuring: which resource, how the count grows, whether a bound is about a program or a problem. Measuring is the easy half. The hard half starts the moment two measurements disagree.
Here is the disagreement, in its smallest form. One design answers every query exactly and needs a gigabyte of memory to do it. Another answers approximately and fits in a few megabytes. It can be wrong in only one direction, by saying “yes” when the true answer is “no”. Which is better?
The question has no answer, and waiting will not supply one. Ask it about a bank’s ledger and the exact one wins without discussion. Ask it about a router deciding in nanoseconds whether a packet is worth a closer look, and the small one wins just as easily. Nothing about either design changed in between.
School trains you to expect a single best answer. Every optimization problem you were given had one number to minimize. Real numbers are totally ordered. Given any two different ones, one is bigger, so among any finite set of candidates “the best” exists. Design has no such number. It has several that move against each other, and there is no natural exchange rate between a megabyte and a microsecond.
1.4.1 Domination and the Pareto frontier
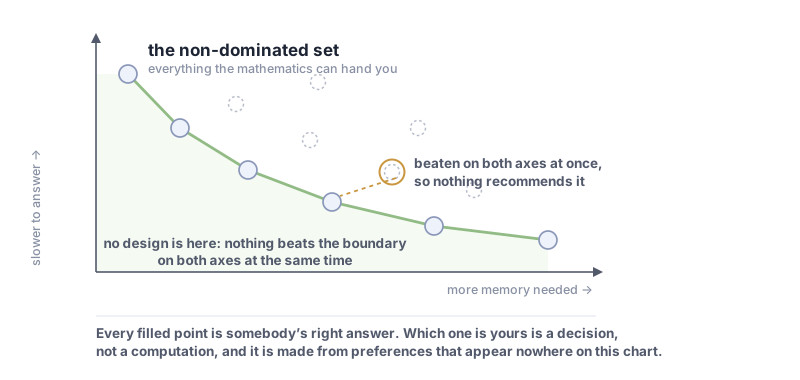
Only one way of comparing designs survives. Design A dominates design B when A is no worse than B on every axis and strictly better on at least one. That is all the mathematics grants, and it is already useful. If A dominates B, then B is out on the axes you measured, for everybody, with no discussion of preferences at all. Nobody has a reason to pick a design that something else beats outright.
Apply that everywhere and you are left with the designs nothing dominates. That set is called the non-dominated set, or the Pareto frontier. It is the real output of comparing designs. (The frontier maps that close each chapter use the word frontier in a different sense.)
1.4.2 Who chooses, and what got left out
A machine can compute that set. The set alone cannot pick a point on it. Computing the frontier is mechanical work, the sort of work to hand to something faster than you. Every point on it is unbeaten, so no calculation alone can choose among them. That needs preferences, and preferences are not in the data. A person, an organization or an AI system can help state them, and a machine can make the pick once they are stated. Whoever states them, the preferences enter from outside the data, and stating them is part of the specification. Doing so means answering questions like these. What does memory cost here? What does a late answer cost, and what does a wrong one cost? Who pays when this is slow, and how often does the bad case actually arrive?
Those are answerable questions. They are just not questions about algorithms. No structure is simply best. So the useful skill is being able to say which axis you are winning on and what you are giving up for it, in terms precise enough that somebody can disagree with you.
The axes were a choice too. Draw the picture with memory and time and you will find the frontier for memory and time. Some axes never get drawn. What does the system cost to run? How much else breaks when it fails? How long does a new engineer need before they dare touch it? Leave those out and your optimum is perfectly real on the axes you kept, and wrong on the ones you dropped. Being unbeatable on a chart that is missing an axis is a common way for good analysis to produce a bad system.
Writing the axes down is the purpose of a contract. Its cost says which axis you chose, and its failure mode says what the promise does not cover. An axis can still be left out, but only openly and in writing, where somebody can object. Contracts are the next thing this chapter builds.
1.5 What a data structure promises
1.5.1 What a data structure is
The chapter has been coming close to one idea without stating it. Both parts of it are already here.
Counting outcomes told you what a single step can tell you. One weighing splits the possibilities three ways, one comparison splits them two ways. No cleverness gets more out of a step than the step contains. That is a ceiling, and it holds no matter how the data is lying around.
But whether a step actually tells you that much depends entirely on how the data is arranged. One comparison against an unsorted pile of a million keys rules out exactly one key. The same comparison, made against the middle of the same million keys in sorted order, rules out half a million. Identical operation, identical cost, and one of them learns five hundred thousand times as much, because the arrangement made a conclusion available that was not available before. You did not look at the other half a million keys. You did not have to look at them. Their order was already known, so the comparison settled them too.
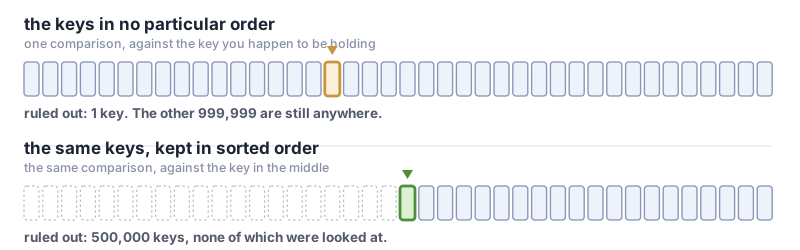
That is what a data structure is. It is an arrangement of data that makes particular conclusions available cheaply, so that algorithms built on top of it can reach further per step than they otherwise could. Not storage or a container, but a standing set of facts that are true about the data, from which every operation is then allowed to reason.
The sharp edge is that a structure makes particular conclusions cheap, and refuses the rest. A sorted array hands you “which half is it in” for free and charges you dearly for “make room for one more.” A hash table files each key under a number computed from the key. It hands you “is this exact key present” for free. But it can answer “what is the next key after this one” only by looking at every key it holds. Answering that question cheaply is exactly what sorted order provides, and a hash table keeps no order. You do not choose a structure by what it holds. You choose it by which inferences you need to be cheap, and which you can afford to give up.
1.5.2 Invariants
Those cheap conclusions are available only because certain things stay true about the data permanently, after every operation anyone ever performs. Sorted order gives you half a million keys per comparison exactly as long as the data stays sorted.
You have met this kind of fact once already. The loop invariant from “Three tools to reuse” is a property that one loop keeps on every pass. Here the property belongs to the data itself, and it has to survive every operation, for as long as the data exists. This book is organized around taking that idea from a single loop to a whole structure.
A data structure is not its code. It is the set of properties it keeps, its invariants, and the conclusions it makes cheap are the ones that those properties license.
The argument is easiest to see on a structure that at first looks like nothing but arbitrary rules. A red-black tree keeps keys in a branching arrangement. Each place in it holds one key and is called a node. The tree paints each link between two nodes either red or black, following invariants that stop any branch growing much longer than the others. A node carries the color of the link coming down into it. The topmost node has no such link. You will build one in the search chapter. For now, read only what it keeps true. The version that this book builds, the left-leaning red-black tree, is exactly five things held true at once:
the keys are in order, the topmost node counts as black, red links always lean left, no two red links ever touch, and every path down crosses the same number of black links.
You do not need to know why those five keep a tree short. You only need to see that they are the structure. Everything else (the color bit, the rotations, the flips) is an encoding, chosen because it makes those five properties cheap to keep. A different encoding keeping the same five properties would be the same structure wearing different clothes.
The payoff shows up immediately. The other famous variant, the one that most textbooks teach, is the same list with two items loosened. Drop “red links always lean left”, and weaken “no two red links ever touch” to “no red link hangs directly below another red link”. Do both and you have the standard red-black tree (the search chapter’s appendix sets the two side by side). Two structures that look entirely different on the page, with different code and different case analyses, differ by exactly two invariants. You cannot see that by comparing implementations. You can only see it by comparing invariants.
Those invariants describe a design that already exists. How would you choose the invariants for a new one? Usually you start from a goal and loosen it until it can be kept. Binary search wants “the target is at mid,” but it cannot know that until the end. So it keeps a weaker invariant instead, “the target, if present, lies in [lo, hi],” which it can restore after every probe. That invariant is true before the first probe, survives every probe, and at the end, when the range has shrunk to one slot or to nothing, it is the answer.
Structures are designed the same way. In a binary tree, “every path down has the same length” cannot survive a single insertion. “Every path down crosses the same number of black links” can survive it, given a repair near the change. So the invariants mark out a region, the set of arrangements in which the structure is allowed to be. Choosing the region is most of the design. It must be tight enough that every arrangement inside it has the cost you want, and loose enough that an update which steps outside can step back in with a small local repair. The search chapter lays four such regions side by side, in its section on what “balanced” is allowed to mean.
Why design this way. Because it moves the moment of failure earlier. Writing code and then testing it tells you about the cases you anticipated. Writing the invariant first shows you where your design is confused, because those are the places where you cannot state cleanly what you want. A property you can’t write down is a design you haven’t finished. That signal arrives before any code exists, which is the cheapest possible time to get it.
1.5.3 The promise
Once a structure is defined this way, every operation on it stops being code and becomes an obligation. insert(k) must both preserve the invariants and add k without changing which other keys are stored.3 Any implementation that does both is a correct insert, whatever language it is in and whoever or whatever wrote it. The implementation comes after the obligation, and can be replaced.
You need both. Drop the second and an insert that quietly does nothing passes. The structure was valid, and it is still valid.
The second, “without changing which other keys are stored”, has to be stated about something, and the five invariants cannot supply it. Before any invariant there is what the tree is for, which is to hold a set of keys. That set is the structure’s meaning, and each operation is a plain sentence about it. insert(k) leaves the set with k added and nothing else changed, and delete(k) leaves it with k gone and nothing else changed. Each such sentence is its operation’s promise. The invariants say which trees are allowed, and the promise says which answer comes out.
The smallest case of a promise left out fits on one line. Specify sorting as “the output is in order.” Before reading on, find a useless program that meets it.
Here is one. A sort that ignores its input and returns an empty list passes, because an empty list is in order. One that returns a hundred zeros passes too. Add the clause about meaning, “and the output is a rearrangement of the input,” and both are ruled out, because neither holds the items it was given. Nothing was wrong with the first clause. It was true, and it was easy to check. It just said nothing about which answer comes out, so it allowed any answer that merely looks right. Keeping the invariants is not enough. The result must mean what you intended.
1.5.4 Contracts
Every design in this book is written down in six parts: its goal, its promise, its idea, its invariants, its cost, and what it assumes. Together, these are a design’s contract, and they make clear what you want done. Without them you have a procedure you remember. With them you have something you can build on, because you know what it needs and what it refuses to promise.
To develop a design and fill in its contract, ask these questions in order.
- Goal. What is the workload (the mix of operations that the design will face), and what does it ask for most often?
- Floor. Which resource is scarce? What can no design beat? The decision tree gives that floor, and the cost in step 5 is measured against it.
- Promise and invariants. What will you keep, stated about the meaning and not only about the shape, and what must remain true?
- Idea. Which idea keeps that promise cheap?
- Cost. What does it cost, and what does it refuse to cover?
- Assumes. What must hold for the promise and the cost, and what happens when it does not hold?
The questions are reminders, and one sentence can answer several. Write down anything that matters and that a reader could get wrong by guessing, and mark the questions you have not decided yet. If two sensible readings of a part would lead to different results, as “find the key” can mean the first copy or any copy, say which one you mean.
Binary search assumes the list is sorted. Hand it an unsorted list and nothing crashes. It answers “not here” about a key that is there, as confidently as it answers anything. That is a failure mode. It is not the assumption itself but what happens when the assumption breaks, or when you ask for more than the promise covers. The worst failure modes are silent. You have met three already: the small summary that may say “yes” when the true answer is “no”, the growable array whose total is cheap while one append makes you wait, and the w.h.p. bound that says nothing about how bad its rare bad run is. A binary search that first checks the order and rejects an unsorted list has moved the unsorted case into its promise, at the price of a full pass.
A contract records a design once it is made. Here is binary search’s, with every part filled in:
- Goal: find a key among \(n\) sorted keys without looking at most of them.
- Promise: find the key, or report that it is absent.
- Idea: probe the middle, and drop the half that cannot hold the key.
- Invariants: the key, if present, lies between
loandhi. - Cost: about \(\log_2 n\) comparisons, worst case.
- Assumes: the list is sorted. Otherwise it may silently miss a key that is present.
The search chapter works out these parts for the B-tree in the numbered order above, then for a workload nobody has named yet.
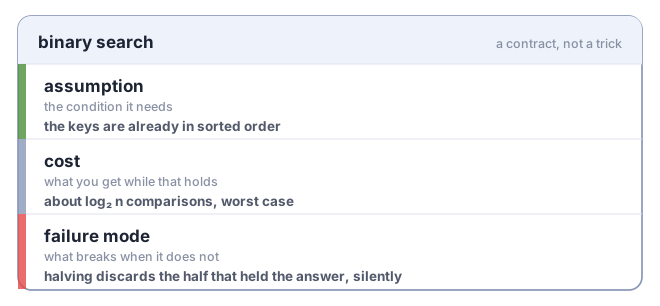
From the next chapter on, each design’s contract is shown in a box titled The design, numbered by chapter (The design 2.1). An implementation must establish and preserve the stated invariants. When the task is to find a design, those invariants come from its designer too.
1.6 Checking an answer you did not produce
1.6.1 Checking vs finding
A specification is worth only as much as the checks that can be run against it. Checking is a different job from finding, and usually a much cheaper one.
Take sorting again. Producing a sorted list costs about \(n \log_2 n\) comparisons at the very least, as the decision-tree count proved. Checking the order of a list someone hands you takes one pass to test whether every item is no larger than the next. You can check that it holds the same items as the input in one more pass, using a hash table to keep a tally for each item. Add one for each copy in the input, take one away for each copy in the output, and check that every tally ends at zero. That cost grows like \(n\). It is an expected cost, because of the hash table. With comparisons alone the tally would cost as much as a sort. Against \(n \log n\) for the sort, that linear cost is cheap enough to run the check every time. The check works even when the sorter is somebody else’s, or a model’s, and you cannot read its code.
1.6.2 Reference algorithms and certificates
There are two kinds of check, and neither depends on how the answer was produced.
- The obvious algorithm as the definition. Some problems have a method so plain that its correctness is not in question, such as looking at every item. It may be far too slow to use. That does not matter, because its job is to define the right answer on inputs small enough to afford it. The clever method has to agree with it. The book’s companion library tests its red-black trees exactly this way. After every single insert and delete, it compares them with a plain Python set. It keeps that reference deliberately plain, because a reference that shared the clever idea could share its bug too.
- An answer that carries its own evidence. Some answers can arrive with something cheap to check: the sorted list beside the input; a shortest route beside a distance for every place, which proves no shorter route exists; and, later in the book, a flow beside a cut, which proves no larger flow exists. Algorithms built to return such evidence are called certifying [2]. You trust the answer because you checked it, not because you trust the program that produced it.
Why must the check come from somewhere else? Because two programs written from the same misunderstanding agree with each other. Let the author of a sort also write the test, and a test written from the same misreading of the task passes the same wrong outputs. The check needs a different origin: an obvious algorithm, a version somebody else wrote and checked, or a certificate.
1.7 ◆ Components and primitives big picture
There are two sizes of thing to carry out of a book like this. It helps to know which one you are being handed.
A finished data structure is a component. You reach for a B-tree, a queue or a cache when you are building a system, the same way you reach for a library. Much of this book teaches exactly that, and it is a real skill.
But you cannot design a new structure out of components. Each one is already the answer to one particular question, with the trade already made and baked in. The moment your question is slightly different, a finished component has nothing to offer you but “close enough.”
The material you can actually build with sits one level down, in the small ideas from which each structure is assembled. Those are small enough to pull apart and recombine. They turn up in places with no visible connection to where you first met them. The counting argument that settled the nine balls also put a floor under every comparison sort and under binary search. The invariant that keeps binary search correct is the same kind of fact that defines a red-black tree.
These are the primitives this chapter has been naming since the nine balls. They are collected in the catalog, and each chapter ends by taking its structures back apart into primitives. A list of structures is something to remember. The ideas they are made of are tools for thinking.
Each primitive answers some of a contract’s questions on its own: its idea, what must remain true, what it costs, what it assumes, and what happens when those assumptions do not hold. A design composes them. Its idea names the primitives it rests on, and their invariants, costs and assumptions turn up in its own contract. That is also why a contract that says “sorted”, “balanced” or “amortized” is only as precise as those words are.
1.8 ✎ Hands-on projects practice
In each project you build or measure something, and you judge what you get back. After them come the self-check problems, each with an answer you can check. Do some of each.
Project 1 · specifications · ~30 min
Hand it to an AI. Give an AI assistant this specification for remove_min, word for word: “The returned item is no larger than anything left.” Ask for an implementation. Then check the implementation against (c): was the returned item in the collection, and does the collection afterwards hold exactly what it held before, minus one copy of the returned item? The implementation probably passes both. Say what filled the gap that (b) left open, and why you could not count on that for an operation nobody has named before.
Project 2 · checking · ~45 min
Check a sort, and time the check. Write the checker for a sort’s output, which must be in order and a rearrangement of the input. Time the checker against Python’s sorted on a million random integers, and say how its running time grows with \(n\).
1.9 ✎ Self-check problems practice
Each exercise has an answer you can check. The answers are on a page of their own.
Exercise 1 · transfer · middling · ~30 min
Which build broke it? A team builds its app once a day. Build 0 worked. Build 100 crashes on start. Once a build crashes, every later one crashes too, because nobody has found the bug yet. Testing one build takes an hour and says works or crashes.
- What is the smallest number of tests that always finds the first build that crashes, and how do you know nobody can do better? Suppose the first crashing build is 73. Run binary search, testing the middle build and rounding down when the middle falls between two builds. Which builds do you test, and which sentence stays true after every test?
- A second machine arrives, so each hour you can test two builds at once. Two tests give four possible answers, so four hours should be enough, since \(4^4 = 256 \ge 100\). Why is that wrong, and how many hours do you really need? Which puzzle from the start of this chapter is this?
- The search names build 73. What can a colleague run to check that answer without repeating your search, and how many tests does it take? Now suppose builds 40 to 49 crashed, build 50 fixed the bug, and build 73 broke the app again. What does the same search report, and is the colleague’s check still true?
Exercise 2 · the balance scale · ~20 min
Heavier or lighter. Now the odd ball may be heavier or lighter, and you do not know which. Why does distinguishing \(2n\) possibilities change the bound, and how many weighings do twelve balls need?
Exercise 3 · the sorting bound · hard · ~30 min
Close the gap. Prove the \(\Omega(n \log n)\) sorting bound cleanly from \(\log_2(n!)\), using Stirling’s approximation.
Exercise 4 · cost models · ~15 min
What makes it true? For each claim, name the cost model or the kind of bound that makes it true or false: “hashing is \(O(1)\)”, “appending to a growable array is \(O(1)\)”, “a binary search on disk is fast”.
Exercise 5 · contracts · ~15 min
How does it fail? For binary search, a hash table and the small yes-or-no summary, name the assumption and the failure mode. Which of the three fail silently, and how would you notice?
Exercise 6 · amortization · ~20 min
Pay for the doubling. A growable array starts empty and doubles when full. Show that \(n\) appends cost \(O(n)\) in total, giving an amortized cost of \(O(1)\) per append, even though one append occasionally costs \(O(n)\).
Exercise 7 · specifications · ~25 min
Find the wrong one that passes. Three specifications for “remove the smallest item from a collection”: (a) the collection afterwards is one item shorter; (b) the returned item is no larger than anything left; (c) the returned item was in the collection and is no larger than anything left, and the collection afterwards holds exactly the items it held before, minus one copy of the returned item. For each of (a) and (b), write a wrong remove_min that satisfies it. Then say why (c) admits no wrong one. Finally, what should (c) say when the collection is empty?
Check yourself: a remove_min that deletes the largest item passes (a), and one that returns the smallest item and removes nothing passes (b).
Exercise 8 · specifications · ~10 min
Drop the other half. Take the sorting example from “The promise” and drop “is in order” instead of “is a rearrangement of the input”. Name, in one line, a wrong sort that the weakened specification now admits.
A colleague reports a new algorithm that sorts arbitrary numbers using only pairwise comparisons in \(O(n)\) time. Without running it, argue whether this is possible. If it is not, state exactly which lower bound it violates and why. If it is possible, state which assumption of that lower bound it must be breaking.
Put this somewhere you’ll see it in about a week. When you do, answer from memory first with no scrolling back and no AI.
- Why can no strategy find the heavy ball among nine balls in one weighing? Say it with leaves.
- Name the parts of a contract, and say what goes missing if you drop each one.
- The invariants say which arrangements a structure allows. What must the promise add, and what program passes without it?
- Of “\(O(1)\) amortized” and “\(O(1)\) worst case”, which one can still make you wait?
- Why is checking a sorted list cheaper than producing one, and why should the check come from somewhere other than the sorter?
Whichever you couldn’t reconstruct is the one to reread, and only that one.
1.10 ★ Frontier map advanced
- Cache-oblivious algorithms. The RAM model charges \(O(1)\) per memory access, but real memory is a hierarchy. Cache-oblivious algorithms are designed to make few block transfers without knowing the block size. Work since 2020 compares them with algorithms that adapt as the memory available changes [3]. Signature: performance that does not match the operation count. Reach for it when constants and locality dominate. Locality is whether the data touched next sits near the data touched last.
- Parallel and work-span models. When many processors run at once, one number is not enough. The work-span model reports total work and the longest dependent chain (the span) [4]. Signature: code whose speed depends on how much can happen at the same time. Reach for it when scaling across cores or GPUs.
- Certifying algorithms. Algorithms that return, beside each answer, evidence that the answer is right, which a small and separately trusted checker verifies [2]. Signature: you trust the answer, not the program. Reach for it when the program comes from somewhere you cannot inspect.
- Checks under optimization. When something searches against your check, it finds the check’s gaps, as the preface’s coding agents did. Signature: a score that rises while the thing it measures does not rise. Reach for it whenever a loop optimizes against a test. The classic way to test the tests is to run them on deliberately broken copies of the program [5]. This entry belongs to the part of the subject that moves with the technology, and it will date faster than the rest of the chapter.
- Specification synthesis. AI systems that draft specifications, invariants and tests from examples or from requirements written in plain language. The danger is that a generated checker writes down the same misunderstanding as the generated program, and the two then agree. Signature: a program and its tests that came from one prompt and have never disagreed. Reach for it when a specification is drafted for you, and reach for independent evidence whenever the generator also writes the judge.
Lean is a language whose proofs a machine checks. The counting step is proved for the Lean definitions in the companion library (
decisionTree_depth_ge). The theorem says that a tree whose questions have at most \(b\) answers needs depth \(\lceil \log_b N \rceil\) to have \(N\) leaves. That every weighing strategy is such a tree is the argument above, and is not machine-checked.↩︎The book’s solver is
algodesign.contracts.ball_weighing. Its test checks every placement of the heavy ball, for every \(n\) up to 81.↩︎The companion library’s Lean states exactly these two halves for the left-leaning tree, and proves for its Lean definitions that
insertanddeletemeet them (LLRB.insertSpec,LLRB.deleteTopSpec).↩︎