2 Search
I leave to the various futures (not to all) my garden of forking paths.
Jorge Luis Borges, “The Garden of Forking Paths” (1941), trans. Donald A. Yates
Dude, where’s my car?
Dude, Where’s My Car? (film, 2000)
2.1 Where did I put my keys?
Your keys could be anywhere in the apartment. You check the couch. Nothing. You check the counter. Nothing. You’re checking at random, and each failed check tells you nothing about where to look next. With the couch crossed off, the counter is still no better a guess than the drawer. You’re just crossing places off a list, hoping the next one is it. It’s an exhaustive search.
Now imagine a different life, where every time you come home you drop your keys on the same hook by the door. Finding them stops being a search at all. You reach for the hook and they’re there. You spent a little effort once, putting up the hook and using it every time, and that effort paid for every search since. The win moved out of the moment of searching and into the organizing you did ahead of time.
Now say you don’t just have one key. You carry a whole keyring: house, mailbox, garage, office, and half a dozen more you’ve picked up over the years, each one stamped with a number so you can tell them apart at a glance. But they went onto the ring in whatever order you picked them up. Just as on the couch and the counter a moment ago, finding key 12 then means checking each key in turn, with no way to skip ahead.
So imagine you put them in order, low number to high, all the way around the ring. Now something changes. Hunting for key 12, you can glance at where you’d expect it and land close, instead of starting from one end and working through every key before it. Order turns “check everything” into “check nearby.”
But that order has to be paid for somehow, and it’s paid for the moment you try to change it. Say a new key, 47, needs to go in, and it belongs squeezed between 46 and 48. There’s no gap sitting there waiting for it, so every key from 48 on has to slide over one spot to make room. Fast to find, once it’s sorted. Painful to change, every time.
This chapter works through that tension as a sequence of structures, each one fixing what broke in the one before it. It runs from checking a drawer at a time up through the structures that hold the indexes of most databases and filesystems you’ve ever used, and then one step further, to what those give up when the writes start arriving faster than the reads.
2.2 Checking one place at a time
Sequential search
That apartment search from before (couch, then counter, then wherever else) is called sequential search, or a sequential scan. You look at one place. Nothing there? Move to the next one, no wiser than when you started. In the worst case you check every spot before you find the keys or run out of places to look.
That worst case is the price. A hundred places to look means up to a hundred checks. A keyring of a thousand keys in no particular order means up to a thousand checks to turn up key 12. Double the number of places and you double the work, one for one. And the worst case is common. It comes up whenever the thing you want isn’t there at all, because being sure it’s missing means looking everywhere.
Sequential search always works, but it never gets smarter as it goes. That’s the baseline all the designs after it get measured against.
Watch it on a few actual keys. Say the ring holds four so far, threaded on in whatever order they arrived: 20, 5, 30, 12. You’re checking whether 30 is already there before adding it. Start at the first key: 20, no match. Next: 5, no match. Next: 30, found, after three checks. Now check for 8, a key that was never added at all: 20, then 5, then 30, then 12, and you are back where you started, having been all the way around. Four checks, one for every key on the ring, before you can be sure 8 isn’t there. That’s the worst case in miniature.
Nothing shortcuts a miss. Being sure a key isn’t on the ring means every key that is there has to be compared against it and rejected. Skip even one and it might have been the match. So a miss costs exactly N checks on a ring of N keys. No search ever needs more [1]. Building the ring this way pays that cost on every insert too, since checking for a duplicate before adding a new key is itself a full search. Adding N keys one at a time, each check costing one more than the last (0, 1, 2, …, N−1 keys already there to compare against), totals \(0+1+2+\cdots+(N-1) = \frac{N(N-1)}{2}\), about \(N^2/2\) compares.
Building a ring of \(N\) keys this way takes about \(N^2/2\) compares, because each new key is first checked against every key already there. The count grows with the square of \(N\), and it gets large exactly at the sizes that no keyring could hold. Nobody carries half a million keys. Plenty of real collections are that size and far past it. They are all around you: the account numbers that a bank keeps, the parcels that a delivery network is holding somewhere right now, the photos on your phone.
So take half a million of anything, arriving one at a time, each arrival checked against everything already stored to be sure it isn’t a duplicate. That is over \(10^{11}\) comparisons to build the collection once. With ten times as many items, still an ordinary size for a real system, it’s over \(10^{13}\) comparisons. With a hundred times as many, it passes \(10^{15}\) comparisons.
Better code would not shrink that count. It is the cost of checking one at a time, which is why nothing at that scale is built this way.
2.3 An orderly key ring
Sorted array and binary search
A ring has no middle. So open it and lay the keys in a row, first to last. Kept in order, that row is what a programmer calls a sorted array.
Say you’re hunting for key 12 on a keyring of a thousand keys, sorted low to high. Checking one at a time from the start still means up to a thousand checks in the worst case. Being sorted has to buy you something faster than that. Before reading on, find a way to use the order to cut the work down, and see how far you can cut it.
Two or three minutes, on fifteen keys you write down. You’re done when you can say how many checks your method needs in the worst case, even if the answer is a guess.
2.3.1 Binary search
Say you’re hunting for key 12. Don’t start at one end and count through. Glance at the key sitting in the middle of the row. If it’s key 15, key 12 must be in the lower half, so throw out the whole upper half in one move. If it’s key 8, throw out the lower half instead. Either way, one glance drops half the row from consideration. That’s binary search. Check the middle, then go left or right depending on what you see, and repeat on whatever’s left. What makes that safe to do is an invariant⬢. It is a property that is true again every time a step finishes, however things look part-way through one. Here the invariant is that the key, if it’s here at all, is always somewhere inside the stretch still under consideration. Every glance preserves that, which is why throwing away the other half can never lose anything.
Say the row holds fifteen keys, sorted: 2, 5, 8, 11, 14, 17, 20, 23, 26, 29, 32, 35, 38, 41, 44, and you’re hunting for 38. Glance at the middle key, 23. 38 is larger, so the whole left half (seven keys) is gone in one glance. The middle of what’s left is 35. Still larger, so 26, 29, 32 and 35 are gone too. The middle of what’s left now is 41. This time 38 is smaller, so 41 and everything past it goes. One key is left, 38. Found, in four glances on a row of fifteen.
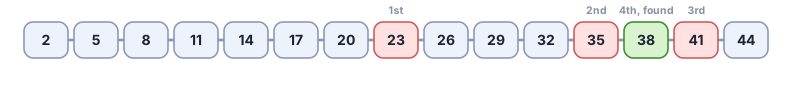
Doubling the length of the row doesn’t double the checks you need. It adds about one more. A row of 4 keys takes about three checks, and a row of a thousand takes about ten. That slow, one-more-check growth as the row doubles is what the term \(\log_2 n\) labels, roughly the number of times you can halve \(n\) before one key is left. For search using only key comparisons, the decision-tree argument in the contracts chapter gives a logarithmic worst-case lower bound. Binary search matches that growth.
Each glance is one compare of the key you want with a key in the row. Let \(C(N)\) be the worst-case number of compares on a row of \(N\) keys. One compare either lands on the key or throws away half the row, leaving a search of at most \(\lfloor N/2\rfloor\) keys (\(N/2\) rounded down), so \(C(N) \le C(\lfloor N/2\rfloor)+1\), with \(C(0)=0\) [1]. Unrolling that recurrence (a bound on \(C\) that uses \(C\) itself) for \(N=2^n-1\) gives \(C(N) \le n = \log_2(N+1)\). For any other \(N\), rounding up gives \(C(N) \le \lceil\log_2(N+1)\rceil\), that is, \(\log_2(N+1)\) rounded up to an integer. That proves the claim above that doubling the row adds about one more check.
2.3.2 Why it is logarithmic
Binary search is \(O(\log n)\): its cost grows no faster than a constant times \(\log n\), for large \(n\). Inside \(O\) the base is left off, because changing it only multiplies by a constant. The real reason binary search is logarithmic is that it cuts by a fixed fraction rather than a fixed amount. Halving is one such fraction.
Guess before reading on: throw away a third of what’s left at every compare instead of half, and is the search still logarithmic? Throw away ten keys per compare instead, and is it?
Throw away a third of what’s left every step and you are still logarithmic, with a different base and the same shape. Throw away a fixed number of keys per step, ten at a time no matter how long the row has grown, and you are \(O(n)\) however large you make that ten [2]. Sequential search is the extreme case. It discards exactly one key per compare. One key is a constant amount, not a fraction, which is why sequential search is linear and binary search isn’t.
Put half a million account numbers in one sorted row. Binary search needs at most \(\lceil\log_2(500{,}001)\rceil = 19\) compares to find any account, worst case (\(\log_2 500{,}001\) is about 18.93, rounded up). Sequential search needs up to half a million on the same row. Nineteen against half a million is what never needing to look at most of the row buys.
2.3.3 Galloping search
Binary search does assume something sequential search never needed. It has to know where the far end of the row is, so it can jump straight to the middle of what’s left. If keys keep arriving and nobody’s counted them, the search has no middle to which it can jump. Galloping search handles that case. It probes outward at doubling distances, 1, then 2, then 4, then 8 keys past the start, until a probe overshoots the target. Then it binary-searches inside just that last doubled bracket. Finding a key at position \(p\) this way costs about \(2\log_2 p\) compares total [3, Sec. 5.1.2]. That is about twice what binary search would need if it knew the row ended at \(p\), but galloping search never has to know where the row ends. It also wins when the key sits near the start of a long row. The cost, about \(2\log_2 p\) compares, depends on where the key is, not on how long the row is.
2.3.4 Insertion means shoving
Insertion into a sorted array
Take the same fifteen-key row: 2, 5, 8, 11, 14, 17, 20, 23, 26, 29, 32, 35, 38, 41, 44. Add key 12. Finding where it goes is the trick you just learned, and it is cheap. Four compares put it between 11 and 14. Now actually put it there. There is no gap between 11 and 14, because sorted keys packed into consecutive slots leave none. So 14 shifts one slot along, and to make room for it, 17 shifts, and 20 shifts, and 23 shifts, and every remaining key to the end of the row shifts. Eleven keys move so that one key can arrive.
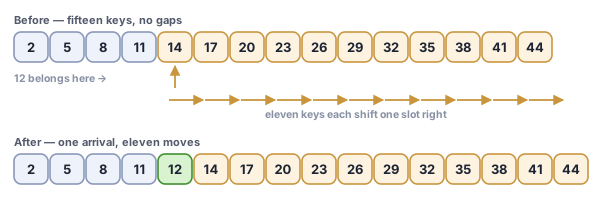
The difference between finding the spot and making room grows fast with the collection. Half a million keys kept as one sorted row means 19 compares to decide where a new one goes, then a quarter of a million keys moved, on average, to make room for it. Thirteen thousand times more work putting the key in than working out where it belonged.
Design a way to store keys that keeps binary search’s fast lookup but doesn’t force every insert to shove half the row aside. Before reading on, sketch how you’d do it, even loosely.
Five minutes and one drawing. A sketch that doesn’t quite work is the right outcome here. What matters is that you’ve felt why “keep it sorted” and “don’t move anything” pull against each other.
Why does putting a key in cost so much? Because the keys’ order is their position. Key 12’s slot is its rank, the count of keys smaller than it. That count is also its address. So a key that changes its rank must change its address, and a key that takes an address must displace whatever was living there.
What if a key’s place in line didn’t have to be its place in memory?
The failure is called one-dimensional crowding. Lay things out along a line and a newcomer can only make room by shoving everybody else aside. The cure, every time it turns up, is to find a second direction in which to grow.
2.4 Escaping the line
Binary search tree
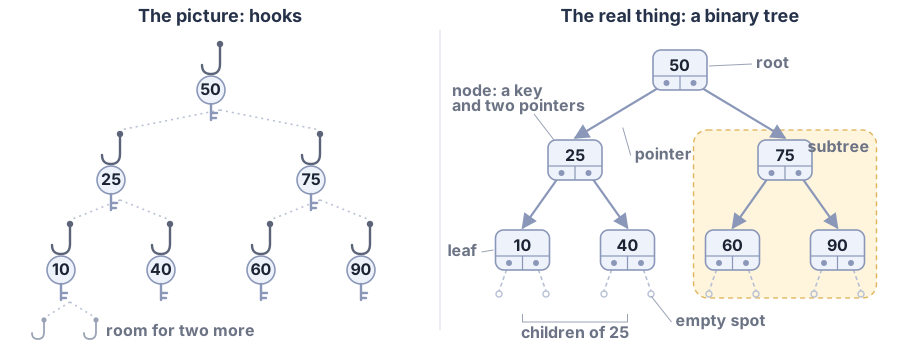
Picture the keyring stored a different way, as a branching arrangement of hooks. Each hook holds a key, and under each hook there is room for two more, one down and to the left, one down and to the right. Those can grow two more the same way, and so on down.
That hook is called a node. It is the word that every library uses, and the word that any search or AI model will use with you. Keep the hook as the picture in your head, and call it a node. The first one, the one everything else hangs beneath, is the root.
That’s a binary tree. A key sits on a node, and the node holds two pointers, one on each side. A pointer, or link, is the memory address of the smaller branching arrangement hanging under the node on that side. A key’s place is no longer a slot to which you count. It’s the node from which the key hangs.
The rest of the family comes off the same picture.
Key idea: trees
The two nodes hanging directly under a node are its children, and it is their parent. Two children of the same parent are siblings. A node with nothing hanging under it is a leaf. Any node, taken together with everything hanging beneath it, is a subtree.
Moving off the line is what buys back the cost of the shoving. On a line, the only free space is at the end, so putting a key in the middle means making room by pushing everybody along.
A branching arrangement grows in a second direction, downward, and that direction never runs out⬢. A row holding \(n\) keys has one empty spot, its end. A branching arrangement holding \(n\) nodes has \(n + 1\). There is one dangling under every side that nothing hangs from yet. The \(n\) nodes offer \(2n\) sides. Every node but the root uses up one of them, which leaves \(2n - (n - 1) = n + 1\). Inserting a key fills one of those empty spots and leaves two new ones behind it. The room is already there, at the bottom, waiting, which is the reason nothing has to move to make it. That room is slack in the levels below.
2.4.1 Order and duplicates
One invariant is enough to make search work. Everything on the left side of a node is smaller than that node’s key, and everything on the right side is larger.
\[\text{left} < \text{node} < \text{right} \tag{2.1}\]
A binary tree that keeps this invariant is a binary search tree.
Mind the word everything. The invariant is about whole sides, not only a node’s two children. Draw this by hand, with 50 at the top, 25 hanging on its left, and 60 hanging on the right of 25. Every parent and child pair looks fine together, yet 60 sits on the left side of 50. A search for 60 turns right at 50 and never finds it.
Read equation (2.1) twice, because both signs are strict. That leaves a gap. The invariant says where a smaller key goes and where a larger key goes. It says nothing about a key equal to the one on the node.
This chapter allows no duplicates. Inserting 50 into an arrangement that already holds a 50 changes nothing. The code below returns at the first comparison that finds 50 and reports that nothing was added. That is a choice, and I make it by default because it is the reversible one. Every other way can be built on top of it later, and none of them can be taken back once the structure is already holding two of something.
Duplicates have to go somewhere.
The first loosens exactly one side of equation (2.1), so equal keys have a settled home:
\[\text{left} \le \text{node} < \text{right} \tag{2.2}\]
Equal keys always go left. Which side you pick doesn’t matter. Picking a side does matter. Loosen both and a key equal to the node could sit on either side. Finding all the copies then means trying both sides. So a comparison with an equal key no longer throws away either side, which was the entire reason for building the tree this way.
Even the one-sided invariant costs more than it looks. Once a key can appear twice, “is 50 here?” and “give me the 50s” are different questions. The second cannot stop at the first copy, because another may be further down that same side. Deletion gets the same problem. Removing a 50 is no longer the same instruction as removing the 50.
That is why the other two answers are usually better, and both keep the invariant strict. Put a count on the node, if the copies are indistinguishable. Hang a list of items off it, if they are distinguishable. Either way the keys stay unique, so every comparison still throws away a whole side.
The choice can lose data silently. Suppose you are logging events by timestamp and two of them land on the same millisecond. A structure that refuses duplicates loses the second one. The insert raises no error, and the structure is one event short. The only warning you get is the False that the code below hands back. Ignoring that returned value loses you data, which is why it is returned at all. If both events must stay, change the key instead. A unique tie-breaker, such as the pair (timestamp, sequence number), makes the two events two different keys, and the strict invariant holds.
2.4.2 Search and insertion
Finding a key means starting at the root and asking one question at each stop: is what you want smaller or larger than the key on this node? Smaller sends you left, larger sends you right. You keep stepping down one side or the other until you land on the key or run out of nodes. Each question throws away a whole side of the arrangement, everything hanging off it, without ever having to look at a single key on it.
Insert eight keys this way, one at a time, each one walking down from the first node until it finds empty air: 50 first, then 25 and 75 under it, then 10 and 40 under 25, then 60 and 90 under 75, then 35 tucked under 40. That’s the whole insertion rule. Walk down comparing, smaller left, larger right, and stop at the first empty spot, which is where the new node goes. No other key has to move. Here it is in code. The whole BST class is in bst.py.
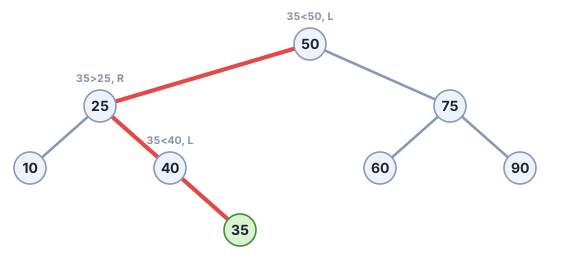
Now search that same arrangement for 35, a key that’s actually hanging there.
- At the root, 50: is 35 smaller or larger than 50? Smaller. Go left, to 25.
- At 25: is 35 smaller or larger than 25? Larger. Go right, to 40.
- At 40: is 35 smaller or larger than 40? Smaller. Go left, to 35.
- At 35: that’s the key, found on the fourth comparison without looking at 75, 60, 90, or 10.
The red path below traces those three steps down.
A sorted array encodes order by where a key sits. A tree encodes order by a key’s neighbors. A key’s place is a pattern of left turns and right turns from the root. Hang new neighbors around a key and the key itself stays put.
2.4.3 Degenerate trees
But nothing in that invariant stops the arrangement from growing lopsided. Try it before reading on. Start from an empty arrangement and insert the keys in sorted order: 10, then 20, then 30, then 40. Each one walks down from the root the same way as before. Sketch the shape you get, then check it step by step.
- Insert 10 first. No nodes yet, so 10 becomes the root.
- Insert 20. Start at 10: is 20 smaller or larger than 10? Larger, go right, and there’s no node there, so 20 hangs on the right side of 10.
- Insert 30. Start at 10: larger, go right, to 20. At 20: larger again, go right, empty, so 30 hangs on the right side of 20.
- Insert 40. Start at 10: larger, right, to 20. At 20: larger, right, to 30. At 30: larger, right, empty, so 40 hangs on the right side of 30.
Every key lands on the right side of the one before it, because the new key is always the largest so far. The tree never branches at all. It just grows into one long line down the right side.
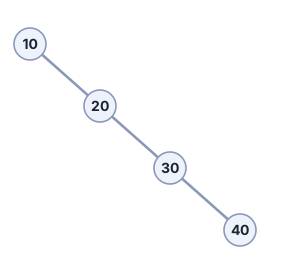
Moving off the row was meant to gain a second direction. This arrangement has thrown that direction away. It is a row again, wearing nodes, and not a sorted row you can halve.
Try it yourself. Step through the same build, or insert and search your own keys.
Searching this arrangement for 40 means walking past 10, then 20, then 30, one at a time. No question ever throws away a whole side, because there never is a side to throw away. This is sequential search, with a tree’s name on it.
2.4.4 Order queries
Insert and search aren’t the only things this shape gives you. The same left/right walk answers a handful of other questions almost for free. min and max just walk all the way left, or all the way right, and stop. The smallest and largest keys are the leftmost and rightmost nodes. Finding them needs no comparisons at all.
floor and ceiling are the next two. floor means the closest key at or below a target, and ceiling means the closest key at or above a target. The target may not be in the tree at all, which is the whole reason you’d ask. They need one extra idea beyond the ordinary walk, which is to keep the best candidate you have seen so far. For floor, a node at or below the target is a candidate, and the walk then goes right to look for a closer one. A node above the target is not a candidate, and the walk goes left. ceiling is the mirror image. When the walk runs out of nodes, whichever candidate survived is the answer. Both are in the companion library, in bst.py. In the recursive version below (the function calls itself on a smaller subtree), no variable holds the best candidate. It is node.key, kept on the way back out whenever the right side turned up nothing better.
To read the keys in increasing order, visit each node’s left subtree, then the node, then its right subtree. For a range, skip any subtree whose keys must fall outside the two ends. The remaining walk lists the keys in the range. The library’s range(lo, hi) returns them, both ends included.
rank (how many keys are smaller than this one) and select (which key sits at a given position) need one more thing that neither min/max nor floor/ceiling need. Every node stores how many keys its subtree holds, its own key included. Inserts and deletes keep that count up to date. In the sorted row, once you found a key, its position gave its rank immediately. The tree gave that up to stop the shoving. With that one extra field, rank walks down the same way search does. On each rightward step it adds the size of the left subtree it passes, plus one for the node past which it steps. On reaching the key, it adds the size of that node’s left subtree. If the walk falls off the tree instead, the key is absent. The sum so far then counts the keys smaller than the missing key. select walks down comparing a target position against the left subtree’s size instead of comparing keys.
On the eight-key tree, the sizes are 50: 8, 25: 4, 75: 3, 40: 2, and 1 for each of 10, 35, 60 and 90. Written out, with \(s\) the size of the left subtree at the node the walk is on:
- \(\text{rank}(k)\) = the sum of \(s + 1\) over every rightward step, plus \(s\) at the node holding \(k\);
- \(\text{select}(i)\), positions counted from 0: go left if \(i < s\); stop here if \(i = s\); otherwise go right, looking for position \(i - s - 1\).
So rank(75) is 6. At 50, step right and add \(4 + 1\). At 75, the key, add 1 for the subtree holding 60. The six smaller keys are 10, 25, 35, 40, 50 and 60.
Each operation above that answers with one key or one count walks a single path down from the root. So none of them costs more than search and insert, a little work per node on a path no longer than the tree is tall. A tree’s height is the number of steps down the longest walk from the root to a place where a node could hang but does not hang. Counting to the empty spot makes a single node a tree of height one. Counting to the last node would make it zero. The difference doesn’t matter here, but your own hand-traces will be off by one if you mix the two counts.
Before opening the answers, try three of these on the eight-key tree you built: floor(45), rank(40), and select(3), where select(0) is the smallest key.
floor(45) is 40. At 50, too big: go left. At 25, a candidate: go right. At 40, a better one: go right, and the walk runs out. The last candidate stands.
rank(40) is 3. At 50, go left and add nothing. At 25, go right and add 1 for the subtree holding 10, plus 1 for 25. At 40, the key: add 1 for the subtree holding 35. The three smaller keys are 10, 25 and 35.
select(3) is 40. At 50, the left subtree holds four keys and position 3 is among them: go left. At 25, the left subtree holds one key, so position 3 is past it and past 25: go right looking for position \(3 - 1 - 1 = 1\). At 40, the left subtree holds one key, which fills position 0, so position 1 is 40 itself, the answer.
The size field is one case of a move far more general than counting. A node can carry any summary of its subtree that is computed from its own key and its two children’s summaries: a count, a sum, a smallest value, a largest one. The one requirement is that combining summaries is associative, meaning it gives the same answer however the pieces are grouped. Associativity is needed because a walk down the tree meets the pieces in whatever grouping the tree’s shape happens to have. Let each account in the bank carry its balance, and let every node store the smallest balance in its subtree instead of its size. Walk down toward each end of a range of account numbers. Every account in the range sits either on one of the two walks or in a subtree hanging between them. Combine the balances of the in-range accounts on the walks with the stored smallest balances of those subtrees. That answers “what is the lowest balance among the accounts numbered between these two,” still at the cost of the height. It is a new question with no new structure.
On the eight-key tree, give the accounts balances: 10 has 4, 25 has 7, 35 has 3, 40 has 9, 50 has 5, 60 has 8, 75 has 2 and 90 has 6. Ask for the lowest balance among accounts 25 to 60. The walk toward 25 goes 50, 25; the walk toward 60 goes 50, 75, 60. Of the nodes on the walks, 25, 50 and 60 are in range (75 is not in range). The subtree holding 40 and 35 hangs between the two walks and stores 3, its smallest balance. The smallest of 7, 5, 8 and 3 is 3, read from the stored summary without visiting the subtree.
Nothing in that argument is about trees. Any quantity whose pieces combine associatively can be kept this way, which is why the same move turns up well outside search trees. Running totals over an array are the flattest case of this move. Summaries of a data stream computed on separate machines can be merged into one for the same reason.
2.4.5 Deletion
Deletion has three cases, and two of them are easy. A node with no children is just unhooked. A node with one child is replaced by the child, which moves up into its place. Order still holds, because everything in that child’s subtree was already on the correct side of the parent above.
The third case, a node with two children, is the real one. Pull it out and a gap opens that something must fill. The two subtrees hanging beneath the node both have to stay on their correct sides. Only two keys in the whole tree can sit in that gap, the smallest key bigger than the one leaving and the largest key smaller than it. Take the bigger one. Every key in the left subtree is smaller than it and every remaining key on the right is bigger, so order survives. (The smaller one, its predecessor, works just as well, by the mirror argument.) The bigger one is the successor of the deleted node. You find it by walking right once and then left as far as you can go.
Whichever way the gap is then filled (the figure shows both), the successor is easy to remove from where it stood. It is the leftmost node in that subtree, so it has no left child. At most one child hangs off it, and that child moves up, the one-child case you already know.
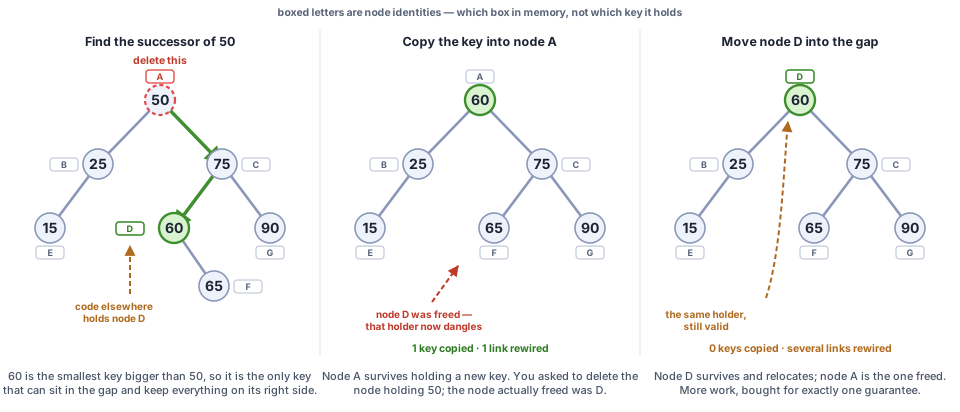
There are two ways to put the successor in the gap, and they differ in which node survives. The keys come out the same.
The figure’s tree has 50 at the top, 25 on its left with 15 below it, and 75 on its right with 60 on 75’s left and 90 on 75’s right. 65 hangs to the right of 60. Delete 50. One step right reaches 75. From there, go left as far as possible to reach 60, the successor, whose only child is 65.
Copy the key. This is Hibbard’s deletion [4]. In the figure’s tree, write 60 into the old node, then remove the successor’s own node by the one-child rule. One key copied, one link rewired. Simple and cheap.
Having copied 60 upward, you do not then go and find 60’s own successor and copy that up too, and so on down to a leaf. The successor’s node has at most one child, so the ordinary one-child case finishes it in a single relink.
Move the node. Unhook the successor and put that node itself in the gap, re-pointing it at the deleted node’s two subtrees. Nothing is copied, but several links get rewired, which is noticeably more work than the first way.
So why pay? Because the first way deletes a different node than the one you asked it to delete. You asked to delete the node holding 50, but what actually left the tree was the node holding 60. If anything else in the program was holding the successor’s node (an iterator, an index, a cache), it is now holding a node that the tree no longer has. Moving the node guarantees that deleting a node deletes that node and nothing else.
The preference has flipped over time. Copying was standard for decades, on the reasonable grounds that it is cheaper, but it is also the one that bites. The most widely used text now teaches moving the node instead [5], trading a little speed for a guarantee. I will not pretend to be neutral about that trade. Most of the expensive hours of my working life have gone on one shape of bug, a structure that was fast almost always and then failed on a day I did not choose, in a way that looked like something else.
Which way you choose makes a difference only when something outside the tree can hold a node. Where it can hold one, identity is part of what you promised.
That leaves the question of whether the two deletions build different trees. The answer depends on what you call the tree. Read it as values, keys in a shape, and they build the same tree. The library proves that in Lean (a language for writing machine-checked proofs). Tests in the library check the claim on every tree that up to five insertions of the keys 0 to 5 can build.1 Read it as nodes, the objects and the pointers that lead to them, and they build different trees, because a different node sits in the gap. A test that looks only at keys and shape cannot tell the two apart. Only a test that holds on to a node can tell the two apart.
Always taking the successor makes paths longer over long runs of deletes and inserts. In experiments, alternating with the predecessor avoided that lengthening [6].
Always taking the successor is lopsided. Paths get longer than they are in a tree built by random insertions alone. The degradation is \(\Theta(\sqrt{N})\) (growth like \(\sqrt{N}\), bounded on both sides up to constant factors) under a restricted model where every deletion is immediately followed by reinserting the key just deleted [7]. For ordinary mixed workloads that figure is widely observed, with no proof yet [8].
Draw an eight-key tree. Delete a key with two children, by hand. Say out loud, before you move anything, which two keys are allowed to fill the gap, why no other key would do, and which one this chapter picks. Then check the result reads in the same sorted order as before, minus the key you removed.
In short, a binary search tree is a row that grew a second direction, so nothing has to move. It degenerates back into a row whenever the keys arrive already sorted. If the binary search tree is what you came for, you have it. The sections ahead fix the degeneration.
2.4.6 Average height
Deletion does not change the headline bound around which this tree was built, that search and insert take time proportional to height. When the keys arrive in random order, the average cost is a proved result. A tree built from N such keys costs about \(2\ln N \approx 1.39\log_2 N\) compares on average for a search or insert, where \(\ln\) is the natural logarithm [1].
The average costs are known exactly, not merely to within a constant.
Writing \(H_N\) for \(1 + \frac{1}{2} + \cdots + \frac{1}{N}\), building the tree from \(N\) random keys costs \(2(N+1)(H_{N+1} - 1) - 2N\) comparisons on average [9]. A successful search costs \(2(1 + \frac{1}{N})H_N - 3\), which is the build cost divided by \(N\), plus one.
Both come from the same move. Average over all insertion orders and the question turns into a recurrence. With \(N+1\) keys, you pay \(N\) comparisons at the root, then the average cost of the two piles into which the root splits the keys. Getting to that recurrence is where the “random order” assumption is used.
The height of such a tree is a proved result too. It converges to about \(c\ln N \approx 2.99\log_2 N\) [1]. It took until 1986 to settle exactly, long after the average-cost result was understood [9]. In that bound, \(c \approx 4.31107\) solves \(c\ln(2e/c) = 1\).
There is one more question that this tree doesn’t answer at all. What if some keys get looked up far more often than others? There is a best possible tree for a known set of access frequencies. The best tree need not be the shortest one. Finding it is a solved problem, waiting in the frontier map at the end of this chapter.
2.5 What is this all about?
The ordered dictionary (dynamic set)
Every structure that this chapter has built is one abstraction wearing different clothes. It is an ordered dictionary, sometimes just called a dynamic set. Underneath the couches and counters and keyrings, each one answers the same short list of questions about a changing collection of ordered items:
- Is this one in here? (
search) - Put a new one in. (
insert) - Take one out. (
delete) - Which one is smallest, or largest? (
min/max) - Which item sits just below, or just above, a value, even one that isn’t in the collection at all? (
floor/ceiling) - Treating the collection as a sorted list without ever sorting it: which position does this item hold, and which item sits at this position? (
rank/select)
Numbered keys made those questions easy to picture, but they aren’t about keys. Swap in the account numbers that a bank holds, and every question on that list is one that its systems answer continuously. search is “does this account exist.” insert and delete are opening and closing one. min and max find the lowest and highest account numbers still open. floor and ceiling answer “the nearest open account number at or below, or at or above, this one,” which is where a scan through a range of account numbers starts. And rank and select answer “how many open accounts have a smaller number than this one” and “which one is the ten-thousandth in number order.”
Each structure in this chapter answers that short list differently.
| Structure | Rough cost shape | What it buys | What it costs |
|---|---|---|---|
| Sequential search | \(O(n)\), every operation | Nothing to build or maintain | No question is ever cheap |
| Sorted array, binary search | \(O(\log n)\) search, \(O(n)\) insert | Fast lookup | Painful to change |
| Binary search tree | \(O(h)\), height unbounded | Cheap insert, nothing shifts | Can degrade toward \(O(n)\) |
Whatever a structure wins in one of the last two columns, it pays for that in the other. The structures still ahead each add a row to that table and obey that rule too.
The plain tree’s inserts shift nothing, at the cost of a height that nobody is guarding. So the tree needs an invariant that stops it from leaning too far, without being expensive to maintain.
Before reading on, try to invent a rule of your own: some small, local check the tree could make after every insert to stop it from growing into one long line, without re-checking the whole tree from scratch each time. What’s the cheapest signal you can think of that a tree has tipped too far?
Ten minutes. This one is hard. It took the field years. So the bar is not a working rule. The standard is one candidate signal and one reason it might be too expensive to keep up to date.
2.5.1 What “balanced” is allowed to mean
Balance conditions
Whatever rule you came up with kept an invariant about shape. The word covering all such invariants is “balanced”. It names at least four different invariants, each a region of allowed shapes in the contracts chapter’s sense. They are not equally strong, and the design question from here on is which of them is worth its price.
The invariants below all try to control the tree’s height: the longest walk from the root down to an empty spot.
Perfectly balanced. Every such walk is exactly the same length. It is the strongest thing you could ask for, and a binary tree can manage it only when \(n\) is one less than a power of two. For any other count, the best available is walks that differ by one. Even that much is out of reach under a stream of inserts. Insert one more key and some walk gets longer. No local repair puts the shape right again without sometimes rebuilding a large part of the tree. Perfect balance is not hopeless everywhere, though. The B-tree later in this chapter keeps every walk the same length, for any \(n\), by letting a node grow wider instead of letting the tree grow taller.
Height-balanced at every node. At every node, the heights of the two sides differ by at most one. This is the AVL tree’s invariant [10], the first one anyone managed to maintain on the spot after every insert. It holds the tree to about \(1.44\log_2 n\) in the worst case, closer to perfect than anything else here. The phrase at every node is essential, and easy to weaken by accident: ask only for the two sides of the root to match, and you have asked for nothing at all, because both sides can still be the long lines that a balanced tree is meant to rule out.
Balanced, loosely. No walk down is more than about twice as long as any other. That’s the balance the red-black tree keeps. The word “balanced” without qualification usually means this one. It asks for no fixed shape, just height held to within a constant factor of \(\log_2 n\), which is all that \(O(\log n)\) ever required.
Weight-balanced. Same idea, counted in keys. At every node, neither side holds more than some fixed fraction of the keys below it [11]. This invariant gives the same kind of height bound. It is the one notion of the four that also tells you something directly about rank and select, since it is already counting.
If you are allowed to stop the world, rotations alone will rebuild any binary search tree into one whose walks down differ in length by at most one, in time proportional to the number of keys. This is the Day–Stout–Warren algorithm [12]. The problem here is staying balanced while the updates keep arriving.
So which one? The invariants after the first all keep height proportional to \(\log_2 n\), which puts them in the same complexity class. Choosing between them is choosing a constant factor. AVL wins that comparison outright, \(1.44\log_2 n\) against about \(2\log_2 n\). A tree that is searched far more often than it is changed is a real case for paying AVL’s price. But what differs between these invariants by much more than a constant is how much code it takes to keep one true, and how many distinct broken shapes a repair has to recognize.
I teach the looser invariant, and that is my preference. A tighter tree that I get wrong is worth less than a slightly taller one I can hold in my head. The looser invariant is also what this book builds on. The left-leaning red-black tree maintains it with three repair moves and one extra bit per link. The B-tree carries the same idea further, letting a node hold more than one key. AVL is not developed here. Its rotations are the same two moves you are about to meet, driven by a stricter test, and Drozdek develops it in full [12].
One more thing, if you have met red-black trees before or expect to meet them elsewhere. The version that this chapter builds is the left-leaning one, not the standard one [5], [13]. The left-leaning version has two extra invariants. The last appendix of this chapter is the translation: what the standard invariants are, why they are the invariants, and the two freedoms that the standard tree keeps (a red link leaning right, and a node with a red link on both sides). Read the next section first. The appendix then reads quickly, because it is the same encoding with those two restrictions lifted.
2.6 Sticky red links
Left-leaning red-black tree (LLRB)
2.6.1 Red links and the five invariants
Give every link one extra bit, red or black. Not the node, the link, the connection running from a node down to whatever hangs on its left or right. That single bit carries an invariant that holds again at the end of every update. It is the invariant idea again, put to a new job. Pay a little on every insert, so every lookup after it stays cheap.
Each link’s color is stored in the node it leads to. The root has no link above it, but still has a color field. That field is black whenever an update is complete.
Picture the colored links on the smallest possible case first. Insert key 20, then insert 10, which goes underneath 20 on its left side. The link joining them is the one that just got colored, red and leaning left.
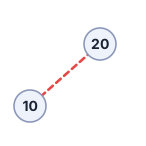
A red link isn’t really a link. It’s glue. Two nodes joined by a red link are one node that happens to hold two keys⬢. Look at the picture again: 10 and 20 are drawn as two nodes, but the red link between them says treat us as one. Black links are the real steps down the tree. Red links are joinery inside a node.
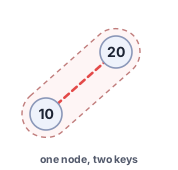
Read that way, the invariants below stop being rules and start being consequences. A node holds one key or two and never three, so no node may have two red links touching it. The two keys in a node always sit the same way round, so a red link always leans left. And “every path crosses the same number of black links” turns into something much plainer than it sounds. Since only black links are real steps down, every leaf sits at exactly the same depth. The tree is perfectly balanced. It just doesn’t look like it, because some of its nodes are drawn as two.
Two different heights are in play from here on. Count only black links and every path is the same length, exactly. That length is the tree’s black height. That equal count is the perfect balance just claimed, and it is a statement about the tree as the glue picture shows it, nodes counted once. Count every link, red ones included, and the paths differ, because a path that passes through several two-key nodes takes an extra step inside each one. The second number is the one that a lookup actually pays. The invariants below exist to keep it from drifting too far from the first.
Invariants 4 and 5 are what bound the second height, the one counting every link. Because red links can never chain, at most every other link on a path down the tree is red. Because the black count is the same everywhere, every path carries the same black backbone underneath. So the longest way down can never be more than about twice the shortest, with a path of all black links in the best case and alternating black and red in the worst case. Height stays bounded without anyone ever having to measure it. Invariant 3, the left lean, plays no part in that bound. It only cuts the number of shapes that a repair has to recognize, which is why the standard red-black tree can drop it and keep the same height.
The left lean also gives the structure its name. This is a red-black tree, specifically the left-leaning variant that Sedgewick introduced, called LLRB for short [1], [14].
2.6.2 Insertion: rotations and color flips
Insertion still starts the same walk as in a binary search tree. Compare left or right, node by node, until you fall off the tree, and put the new key there. The only change is that the new node arrives attached by a red link. That red link can break one of the invariants above. So on the way back up toward the root, node by node, the tree checks itself and applies whichever of three small, local repairs the broken invariant needs:
- rotate left: a red link leans right. Rotate, and the lower node comes up, the upper node drops to its left, and the link leans left instead.
- rotate right: two red links lean left in a row, one chained directly below the other. The node in the middle has a red link coming in from above and another going out below. Rotate, and the middle node comes up with a red link on both its left and right side.
- flip colors: a node has red links on both sides. Flip both to black, and send a single red link up to the node above it.
Read the third one through the glue picture, and it stops looking like a repair. A node with red links on both sides is a node holding three keys, and a node may not hold three. So the middle key moves up into the node above and the outer two stay behind as nodes of their own. That is a split. A much larger structure later in this chapter grows by the same move.
Each repair touches only a node and its immediate neighbors. Apply a few of them at each node on the way back up, set the root’s field black at the end, and every invariant holds again.
Watch it happen on an actual tree. Start empty, and insert five keys in this order: 10, 20, 30, 15, 5. Each key arrives on a red link, and on the way back up each broken shape calls its repair. Inserting 20 leaves a red link leaning right, and rotate left straightens it. Inserting 30 gives 20 a red link on both sides.
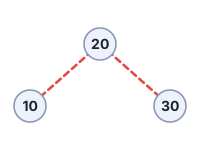
Flip colors turns both of 20’s links black and sets 20’s field red. Since 20 is the root, the update then sets it black again. Inserting 15 puts it on 10’s right, on a red link that leans right again, and rotate left at 10 straightens it once more.
Before reading on, insert 5 yourself. Where does it land, which invariant does it break, and which repair fires first?
It lands on 10’s left, under the red link from 15 to 10. Now two red links lean left in a row. Rotate right fires at 15 and leaves 10 with a red link on both sides, so flip colors fires at once and sends a single red link up to 20.
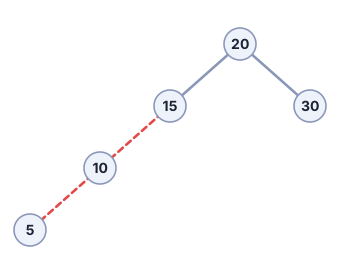
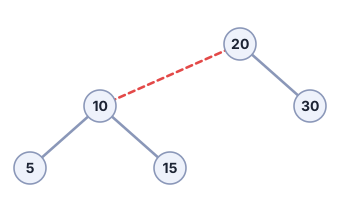
The tree settles with 20 at the top, red 10 on its left carrying black 5 and 15, and black 30 on its right.
Press Next step to insert the five keys one repair at a time. Then type a key of your own, press Insert this key, watch the repair, and keep pressing Next step, saying before each press which repair fires next.
Here are the five repairs as a ledger, one line per key inserted.
| Insert | Repair that fired | What the tree looks like after |
|---|---|---|
| 10 | none | 10 alone |
| 20 | rotate left at 10 | 20, with 10 on a red link to its left |
| 30 | flip colors at 20 | 20, with 10 and 30 both black |
| 15 | rotate left at 10 | 20, with black 15 on the left and red 10 beneath it |
| 5 | rotate right at 15, then flip colors at 10 | 20, with red 10 carrying black 5 and 15, and black 30 |
Three small repairs undo whatever the last insert broke, node by node on the way back up. If that is enough for you, you have the left-leaning red-black tree, and you can skip ahead to the B-tree. What follows is the code behind those repairs, the 2-3 tree this one comes from, and deleting the smallest key, which needs one new idea.
The code is in the companion library, in llrb.py.
Every node except the root has exactly one link coming down into it, so one color field per node is enough. h.red is the color of the link above node h. When the code or prose says “a red node”, it means that the link above it is red.
Red links aren’t the only way to get a guarantee like this. The skip list waiting in this chapter’s frontier map reaches the same bound on average, by keeping no balance invariant at all and flipping coins instead.
2.6.3 Where LLRB actually comes from
2-3 tree
The glue picture stated the invariants, and this section shows why they are forced. The picture has a real structure standing behind it. A 2-3 tree is a search tree whose nodes hold either one key or two, and never more, and whose leaves all sit at the same depth.
A 2-node holds one key and has two children, smaller on one side and larger on the other, an ordinary binary search tree node. A 3-node holds two keys and has three children: smaller than both, between them, larger than both. That third child is the one shape that a 2-3 tree allows and a plain binary node can’t allow.
Keep the nodes ordinary, and the plain tree’s search, min and floor run on the red-black tree unchanged. So how does a 3-node fit inside an ordinary node, which only has room for one key and two children? Split it into two nodes, one holding each key, joined by a link between them. Color that joining link red, marking that these two nodes are secretly one 3-node. Every other link (connecting two separate 2-3 tree nodes) stays black. A 2-node needs no disguise. It’s already a plain node with only black links to its children.
Here is that translation on the tree that the five keys built earlier.
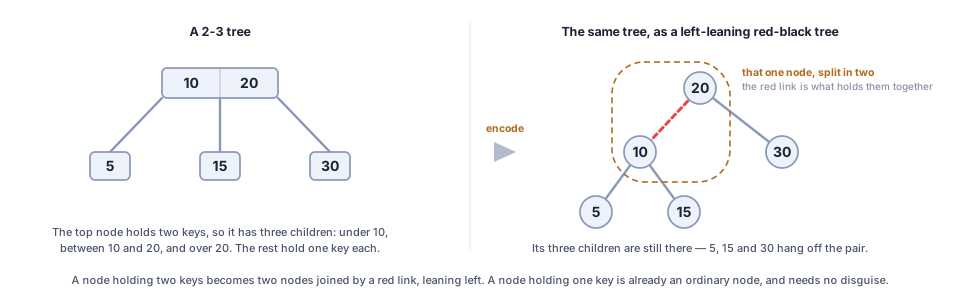
Compared key by key, the two sides hold the same five keys, in the same order, with the same three subtrees hanging underneath.
Which side does the pair lean on? Put the second node down and right of the first and the red link leans right. Put it down and left, and the red link leans left. Either encodes the exact same 3-node just as validly. A 2-3 tree doesn’t care on which side its binary disguise leans. LLRB just picks one side, left, and enforces it everywhere. So any code that walks the tree has one fewer shape to handle.
With the lean fixed, the translation runs both ways with no choices in it. Every 2-3 tree becomes exactly one left-leaning red-black tree, and every left-leaning red-black tree becomes exactly one 2-3 tree. Nothing is lost in either direction and nothing is ever decided along the way, which is what a mathematician would call a one-to-one correspondence. Allow the pair to lean either way, as the standard red-black tree does, and that stops being true. Each two-key node then has two legal drawings, and the same 2-3 tree corresponds to more than one red-black tree.
The correspondence is between trees at rest. Insertion keeps to it step for step: every insert into the left-leaning tree is the 2-3 tree’s insert, drawn in links. Deletion, later in this section, does not, since on its way it passes through shapes that no 2-3 tree has.
With the correspondence in place, LLRB’s invariants can be read off the 2-3 tree instead of argued from scratch.
The red-link invariants follow directly from the encoding. Take the invariant that no node ever has two red links touching it. Suppose a node did, with both red links hanging below it or one chained below the other. Either way, that’s three keys folded into what’s supposed to be a single 2-3 tree node. But such a node holds one key or two, never three. The invariant restates, in links, what a 2-3 tree can contain.
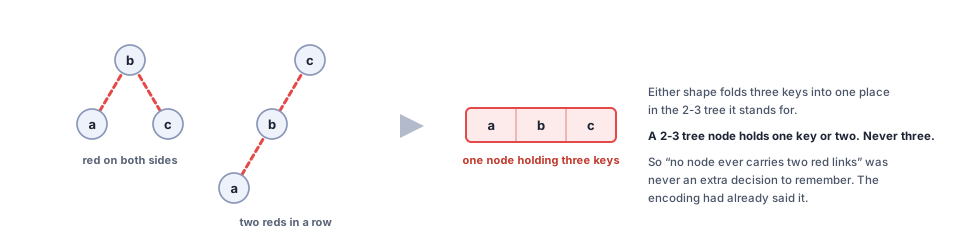
The three repair rules tell one connected story. Insert into a 3-node and the new key attaches somewhere in that pair by a red link. For a moment, that spot in the tree is the encoding of a node with three keys, a shape that no 2-3 tree keeps and only the binary disguise can draw. Which rules fire next, and in what order, depends only on where among the three keys the new one landed.
Write a 2-3 node as its keys in square brackets. Here are the three cases on the 3-node [10 20], drawn as 20 on top with 10 on a red link to its left.
| New key lands as the… | Shape it makes | Repairs, in order |
|---|---|---|
| smallest (5) | two red links leaning left in a row | rotate right, flip colors |
| largest (30) | red links on both sides of 20 | flip colors |
| middle (15) | a red link leaning right, below 10 | rotate left, rotate right, flip colors |
All three cases reach a node with red links on both sides, exactly the shape that the no-two-reds invariant forbids. In a 2-3 tree, a 3-node that has just taken a third key splits and pushes its middle key up. That split, replayed as a color change instead of a physical rearrangement, is flip colors: both links turn black, the node stops pretending to hold three keys, and a single red link carries the pushed-up key to the node above. There the same story can repeat one level higher, if it has to repeat.
2.6.4 Deletion
Deleting a node needs one more trick beyond the three repair rules above. Those rules run on the way back up, fixing the red links that an insertion left behind. But they don’t help once a node already has to disappear. Deletion has to arrange things on the way down, before it gets there.
The walk down maintains the invariant that the node that the walk is about to step into is never a 2-node. Either the link into it is red, or the link to its left child is red. Either way, in the 2-3 picture it is part of a node holding two keys, so it has a key to spare. A node with neither of those red links is holding one key with nothing to spare. Deleting through it would leave a gap in the black count. So Sedgewick’s fix is to make sure the walk never arrives at one, by arranging the spare before stepping down.
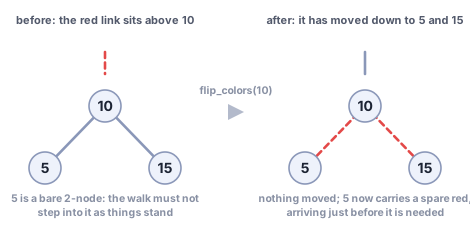
That is the push. Walking down toward the key to delete, push a red link down ahead of the walk whenever the next node would otherwise be a 2-node. The red comes down from the node above. One is borrowed from the sibling next door instead only when that sibling has a spare of its own. move_red_left pushes a spare red link down-and-left before the walk continues left. A walk that turns right needs its counterpart, move_red_right, which the appendix uses. By the time the walk reaches the key being deleted, that node is guaranteed to already be carrying a spare, so removing it can never leave a gap behind. The three ordinary repair rules, run again on the way back up, clean up whatever the push disturbed.
Read move_red_left below as a black box. Hand it a node whose next step is a 2-node, and it hands back one whose next step is not a 2-node. You do not need to hold its body in your head to read delete_min. The line in delete_min that checks for a spare is the invariant above, written out. Both are in the companion library, in llrb.py.
move_red_left, Python.
Here is the walk that uses move_red_left.
flip_colors has a second job, the one that move_red_left uses. On the way up from an insert, flip_colors turns a node red and its two children black, sending a red link upward. When flip_colors runs on a node that is already red with two black children, the very same three flips send a red link downward instead, which is exactly the push this walk needs. That is why flip_colors is written to flip all three colors. One repair serves both directions.
In the trace below, watch where the walk pushes a red link down, and why taking the key out then leaves no gap in the black count. If the invariant already feels inevitable, skip the trace and pick up after its ledger. Nothing later depends on the trace.
Watch it run on the tree that those five keys built, with 20 at the top, 10 on a red link to its left carrying black 5 and 15, and black 30 on the right. Take out the smallest key, 5. At 20 the walk already has a spare, since 10 arrives on a red link. At 10 the next node, 5, is a 2-node, so move_red_left fires and its flip_colors(10) does that second job, pushing the red link above 10 down onto 5 and 15. Nothing moves.
At 5 there is no left child, so the walk returns None and 5 is gone. No key is lost, since in this tree a node with no left child has no right child either. And because 5 was carrying a red link when it went, removing it took no black height from the tree anywhere.
Back up at 10, the link to 15 leans right, so fix_up rotates left. Finally, the root is colored black. The tree ends with 20 at the top, black 15 on its left with red 10 beneath it, and black 30 on the right. It took one color flip on the way down and one rotation on the way back up.
Press Next step to walk this deletion one move at a time. Then press Delete the smallest again, and before each step, say whether move_red_left will fire.
Here it is as a ledger, in the square-bracket notation of the 2-3 tree.
| Step | What happens | Tree afterwards |
|---|---|---|
| start | nothing yet | [10 20] over [5], [15], [30] |
| at 20 | 10 arrives on a red link, so there is a spare: descend | unchanged |
| at 10 | 5 is a 2-node, so move_red_left flips colors at 10 |
[20] over [5 10 15], [30] |
| at 5 | no left child: 5 is removed | [20] over [10 15], [30], with 15 leaning right |
| back at 10 | fix_up rotates left at 10 |
[20] over [10 15], [30] |
The walk ends with the root colored black, but delete_min does not do that itself. Its recursion leans on the precondition that delete_min may only be called on a node that is itself red, or that has a red link on its left. Every recursive step arranges that before descending, which is the job of move_red_left. But the first call has nobody above it to arrange anything, so the caller has to do it by hand. It colors the root red before starting if both of its links are black, and colors it back to black when the walk is finished. That driver is delete_min_from, in llrb.py too.
Deleting any key runs the same walk, turning right as well as left. That walk is in the appendix.
Key idea: a bound on height is not a bound on rotations
Both red-black trees keep the height, and so the work of every operation, proportional to \(\log_2 n\). Only the standard red-black tree also bounds the structural change, to \(O(1)\) rotations, at most two per insert and three per delete. The left-leaning tree runs fix_up at every node on the way back up and can rotate at every level, so its bound is \(O(\log n)\) rotations per operation, not \(O(1)\). On trees of 4,096 random keys it took up to 11 rotations for one insert and up to 15 for one delete, about 5 per delete on average.2 Where each rotation has a cost of its own, that is the reason to choose the standard tree.
2.6.5 What a proof checks, and what it doesn’t
For the red-black tree, the companion library goes beyond tests, to a proof. A proof starts from a definition. Here is how the proof assistant Lean defines a valid left-leaning red-black tree, in the companion library at lean/AlgoDesign/Searching/LLRB/Spec.lean.
def Valid (t : LLRB α) : Prop :=
  Sorted t ∧ RootBlack t ∧ LeftLeaning t ∧ NoRedRed t ∧ BlackHeightOk t
Read it as the chapter’s five invariants joined by “and”, because that is all it is: the keys are in order, the top of the tree is black, red links lean left, no two red links touch, and every downward path crosses the same number of black links. In this notation, ∧ is “and”, α stands for whatever type the keys have, and Prop means “this is a claim, which may be true or false of a given tree”.
A machine has checked that inserting into a tree satisfying those five invariants leaves a tree still satisfying them. The same holds for deletion. The walk that deletes any key, in the appendix, preserves all five, and removes exactly the key you asked for and no other.3 The deletion proof took considerably longer than the insertion proof, for a reason that the walk itself makes plain. It rearranges the tree on the way down, so the node it recurses into is often no longer the one at which it was looking. The proof has not checked the Python printed above. The Python is held to the same behavior by tests, not by proof. And the proof says nothing about whether those five are the right five.
Take a deletion definition that splices out a node on reaching an empty right child. It reads correctly but is one clause short. The definition must also check that the node it has reached holds the key being deleted. Without that check, whenever the key you ask for isn’t there at all, it removes the largest key below it instead, with no error. Lean accepts the definition, and can prove that it always finishes. A proof that it keeps the five invariants still goes through, because that proof says nothing about which key comes out. What catches the missing clause is a proof that does say which key comes out, like the one above, or a property test comparing the definition against a plain list over thousands of random sequences.
A proof assistant checks the properties you thought to state, with complete rigor, and is silent on the ones you did not state. Deciding what to state is still your job.
The library’s Python carries the same five as check_valid(). It returns None when every invariant holds, and otherwise names the first one that fails, numbered as in the box. Build the five-key tree from the trace, repaint one link by hand, and ask again.
from algodesign.searching import LLRB

tree = LLRB([10, 20, 30, 15, 5])
print(tree.check_valid())      # None
tree.root.left.red = False     # repaint the link into 10 black
print(tree.check_valid())      # invariant 5 (black_height_ok)
Back to the tree itself. It can no longer lean into one long line the way the plain tree leaned, so the height guarantee holds. But these operations (comparing, rotating, flipping) all still mean chasing one pointer at a time, node to node, down a single path. The assumption that every pointer costs the same to follow is about to break.
2.7 Frankenstein
B-tree
2.7.1 Blocks and fan-out
Everything so far has assumed that looking at any key costs about the same as looking at any other. Call that the RAM model, the same assumption that the contracts chapter named under “The memory hierarchy”.
Real memory doesn’t hand you one key at a time for free. It hands you whole chunks, whether you asked for a chunk or not: a cache line from RAM, a page, a disk block. Every level of memory works this way. Fetching one such chunk, a block, is the expensive step. Once it has arrived, looking through everything sitting inside it is comparatively free. Call this the I/O model, and call the expensive step itself a fetch. The cost here is how many separate blocks you had to fetch, however many keys you then compare inside them.
If fetching a block is the expensive step, and everything already inside it is nearly free to look through once it’s arrived, what would you change about a node to make each expensive fetch worth more? Before reading on, decide what a node should hold instead of a single key.
Two minutes. One sentence is a complete answer.
Look at your sentence. Does it say how the keys inside one node are arranged, so that the ones that a single fetch brings back are useful together?
The promise rests on invariant 1, the order. The fetch count rests on invariants 3 to 5, which keep every node well filled and every leaf at the same depth.
A tree built one key per node pays a full fetch at every node and uses one key of it. A B-tree fills the node instead, so each fetch buys many cheap comparisons inside the node it brought back. The 2-3 tree behind the red-black one was a small case of the same idea, with up to two keys per node.
You already know this idea, though probably not about keys. You don’t walk to the kitchen five times to bring back five things. You go once and carry an armful, because the walk is what costs and what’s in your arms is nearly free. Anyone who has ever been halfway up the stairs and thought “while I’m going anyway, I’ll take the rest” has had this thought.
So make the node hold an armful. The rest of the tree stays as it was: it still branches, it still compares, it still walks down one path. It just refuses to spend a fetch on one thing. The keys inside a node are kept in sorted order to enable faster search.
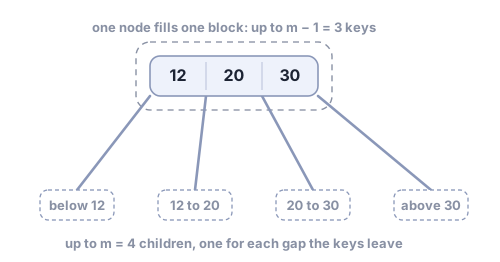
The most children a node may have is the tree’s order, \(m\). A full node holds \(m-1\) keys and, if it is not a leaf, \(m\) children, one for each gap that its keys leave. Figure 2.18 shows one with \(m = 4\).
That makes each node a short sorted array, the sorted row from the start of this chapter, fast to search once it has arrived. And the nodes hang off one another the way single keys hung off one another in the search tree, so the whole thing can grow without anything being shoved along a row. The B-tree is stitched together from two earlier designs. The array gives cheap scanning inside each node, the tree gives cheap growth between nodes, and each covers the other’s weakness.
Put numbers on it. Give the nodes room for a thousand keys, and to be pessimistic, let them sit only half full, about the least that a B-tree ever allows.
| Keys stored | Fetches, with a thousand keys per node | Fetches, one key per node |
|---|---|---|
| 500,000 | 3 | 19 |
| 50,000,000 | 3 | 26 |
| 62,500,000,000 | 4 | 36 |
Fifty million keys, three fetches, against twenty-six separate fetches from twenty-six separate places for a tree that insists on one key per node. Both columns are logarithms (the fixed-fraction rule from the sorted row, still running), but one takes its logarithm in a base of about 500 (a thousand slots, kept half full) and the other takes its logarithm in base 2. The gap between the two columns is the reason the B-tree exists.
From the design 2.3 you would assume it is specific enough to allow only one implementation, but it allows a whole zoo of them, and the textbooks disagree. Invariant 3 of the design 2.3 says how full a node may be. This book makes it exact with one number.
Definition: minimum degree
Minimum degree \(t\): the fewest children that a valid node may have, if it is neither the root nor a leaf. Every node below the root holds at least \(t-1\) keys, its minimum. A node holds at most \(2t-1\) keys, and holding that many it is full, with \(2t\) children if it is not a leaf. The root may hold as little as one key and two children. \(t\) is chosen so that a full node fills one block.
Defining a B-tree by its minimum degree allows only even orders, \(m = 2t\). That is what lets a full node split evenly. Its \(2t-1\) keys are the middle one and \(t-1\) on each side [15]. Two widely used textbooks keep to even orders [1], [5], while others choose the order freely, so a B-tree of order 5 exists there [2], [12]. Pay attention to which kind a source means. This book counts with \(t\), and so works with even orders only, because \(t\) is what shows up in the arithmetic.
The textbooks also differ in how they repair the tree. Only Cormen et al. [5] repair it on the way down. The rest repair it from the bottom up. This book takes the top-down approach for its single pass and its lighter locking under concurrency. The red-black tree already worked in both directions, repairing an insert on the way back up and arranging a deletion on the way down, with a clean-up on the way back. Project 8 builds the bottom-up one, odd orders included.
| Top-down (this book) | Bottom-up | |
|---|---|---|
| When it repairs | before stepping into a node: split it if full, top it up if at the minimum | after changing the leaf: split a node that overfilled, fix one that underflowed |
| Direction | one pass down; deleting a key from an inner node returns once to that node | down to the leaf, then up as far as the repair reaches, at worst to the root |
| What it holds in hand | the current node and the child it is about to enter | the whole path, or a pointer from each node to its parent |
| Unneeded work | splits and top-ups that this operation turns out not to need | none: it repairs only what actually broke |
| Height changes | can gain or lose a level a step earlier than strictly needed | only when a repair reaches the root |
| Orders allowed | even only, \(m = 2t\): a full node must split into two minimum nodes and the key between them | any order, odd ones included |
| Locking | a node already passed is not touched again, so its lock can go at once [16], except an inner node whose key a deletion replaces | the path stays locked until a node is reached that cannot overflow or underflow |
| Sources | [5] | [17]; [12]; [18] |
2.7.2 Search, top-down insertion and node splitting
Take \(t = 2\), with room for up to three keys and up to four children. That is small enough to trace by hand and big enough to show a split. Build one up by inserting 10, 20, 5, 6, 12, 30, and 7, in that order. All but one slide into the node on which they land. The exception is 6. By then the root holds 5, 10 and 20 and is full, so it splits first. After all seven, the root holds 10, its left child holds 5, 6 and 7, and its right child holds 12, 20 and 30.
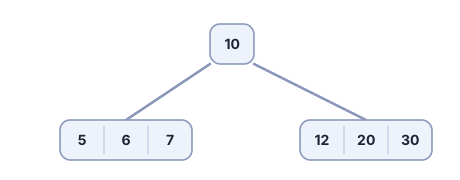
A search for 20 takes two fetches, one for the root and one for the right node. Now insert 17. Its walk heads for the right node, which is full, so the walk splits it before stepping in. The middle key, 20, goes up into the root. The keys 12 and 30 stay behind as two nodes, and 17 then slides in beside 12. That split is the one that the red-black tree’s third repair made, here done with whole blocks of keys. The root now holds 10 and 20, over three nodes holding 5, 6 and 7, then 12 and 17, then 30.
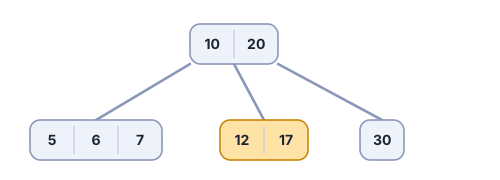
Press Next step to build the tree one move at a time, up to 17. Before each press, say whether the walk meets a full node, and if it meets one, which key goes up.
Notice which direction the key traveled, because the tree’s bound on fetches depends on it. A split sends its middle key up, never down. Pushing down would lengthen one path and leave the others alone. Once two leaves sit at different depths, the argument behind that bound no longer works. Pushing up lengthens every path at once or lengthens none of them. The only way this tree ever gets taller is a split of the root itself, which has no parent into which to push. A brand-new root appears above the old one, and every leaf gets one step deeper together. So all the leaves stay level, and a B-tree grows at the top rather than at the bottom. The plain search tree grows at its leaves, while the 2-3 tree behind the red-black one grows like the B-tree, by a new root at the top.
The code below (Listing 2.9) gives the exact mechanics of a split. The whole BTree class is in the companion library, in btree.py.
On the node you just split, with \(t = 2\) and keys [12, 20, 30]: y.keys[1] is 20, which goes up; y.keys[:1] is [12], which stays; y.keys[2:] is [30], which goes to the new node z.
This structure is also the one toward which this chapter set out. The B-tree [17] is what sits under the indexes of most databases you’ve ever queried (often in a variant called a B+-tree, which keeps all the actual data in the leaves), and under the directories of most modern filesystems. It is the design in this chapter doing the most quiet work in the most places.
2.7.3 B-tree height
Below the root, going down one level multiplies the number of nodes by at least \(t\), so in a tree holding \(n\) keys no leaf sits more than \(\log_t \frac{n+1}{2}\) steps below the root. Count the fewest keys that a tree can hold with a leaf \(d\) steps down. The root holds one key, and one step down there are at least 2 nodes. Each step after that has at least \(t\) times as many nodes, and each node below the root holds at least \(t - 1\) keys:
\[ \begin{aligned} n &\ge 1 + 2(t-1)(1 + t + \dots + t^{d-1}) = 2t^d - 1,\\ \text{so}\quad d &\le \log_t \frac{n+1}{2}. \end{aligned} \tag{2.3}\]
Since \(\log_t n = \log_2 n / \log_2 t\), every doubling of \(t\) knocks another slice off the height. Making a node fatter divides the whole walk down, instead of shaving a constant off it.
Put a real block under it, a 16 KB page holding 16-byte keys and 8-byte child pointers. That leaves room for \(16{,}384 / (16 + 8) \approx 682\) keys per node. A node holds at most \(2t - 1\) keys, so \(t\) is about 340. A trillion keys is then \(\log_{340}(10^{12}/2) \approx 4.62\), so at most four steps below the root, which is five levels, five fetches, worst case, ever. Hold the first two levels in memory, which is what happens anyway once a database keeps the pages it touches most, and a lookup anywhere in a trillion keys costs about three fetches from disk.
Doing more cheap work inside a node to avoid an expensive fetch of the next one pays exactly when reaching a node costs vastly more than comparing keys already in your hand, that is, when \(C_{\text{access}} \gg C_{\text{compare}}\). Wherever that gap is wide enough, a few wide nodes beat many narrow ones, every time.
2.7.4 Top-down deletion
Deleting a key runs the same discipline as insertion, in the same direction. The walk goes down once, with no repair on the way back up. For that, every node that the walk enters must be able to lose a key during the rest of the deletion, directly or through a merge below it, even when this deletion turns out not to take a key from it. Insertion refuses to step into a node that is already full. Deletion refuses to step into one that is already at the minimum. A node at the minimum that lost a key would be underflowing, holding fewer than its minimum. That is the floor of the same invariant 3 whose ceiling made splitting necessary. So top such a node up first, before descending any further. Red-black deletion prepared the same way. Before descending, it made sure the next 2-3 node had a key to spare, borrowing through the parent or merging with a sibling.
Watch both repairs on the tree you just built, the one that the split left behind. As with the 2-3 nodes earlier, write a node as its keys in square brackets. The tree is [10 20] on top, with [5 6 7], [12 17] and [30] hanging under it.
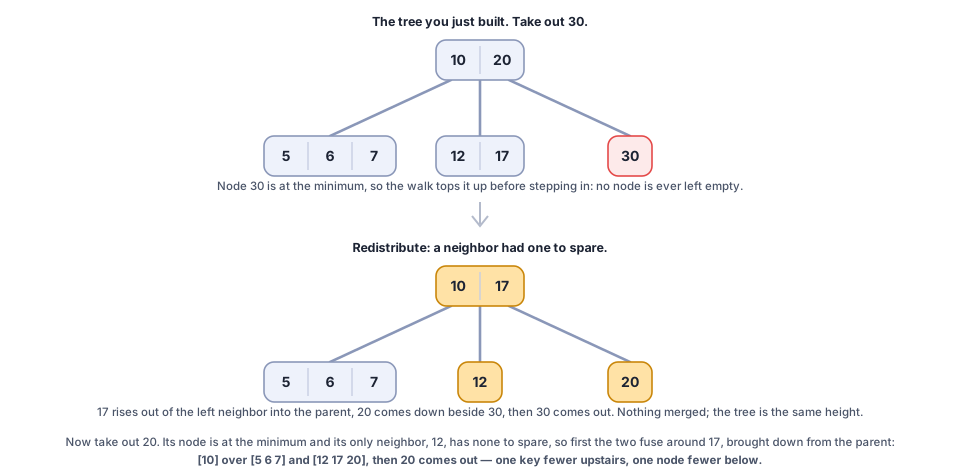
Topping up first tries the cheap option, to redistribute a spare key from a neighboring node that has more than the minimum. The neighbor’s nearest key moves up into the parent, and the parent’s key that separated the two moves down into the thin node. The ordering still holds. When neither neighbor has a key to spare, and only then, it falls back to merging, which fuses the node with a neighbor and pulls the separating key out of the parent to hold them together. The order is fixed, and it decides which keys end up where: borrow from the left neighbor if it can spare one, otherwise borrow from the right neighbor, and only then merge, with the left neighbor when there is one.
Merging can shorten the tree, because pulling a key down out of a parent can leave the parent empty. If the parent is the root and that key was its last, the root is discarded and its one remaining child becomes the new root. That is the only way this tree ever loses a level.
Doing the repair on the way down rather than on the way back up is visible from the outside. A node gets topped up because it sits at the minimum, not because the deletion turned out to need it. So a tree can lose a level on a deletion that would not have left any node below the minimum.
Take out 30 first. Its node is at the minimum, so it is topped up before anything leaves it. The left neighbor [12 17] can spare a key, so 17 goes up into the parent and 20 comes down. Then, and only then, 30 is removed. Take out 20 next, which now sits alone where 30 was. Its node is at the minimum again, and its only neighbor, [12], has nothing to spare, so the two merge around 17, pulled down from the parent, before 20 is removed. Take out 10 last, from the root. A key in an inner node is the separator between two children, so it is replaced by a neighbor in sorted order. The predecessor, the largest key to its left, is 7. The node [5 6 7] can spare it, so 7 moves up. What is left is [7] on top, with [5 6] and [12 17] below.
For a key in an inner node, the predecessor comes up if the left child can spare a key. Otherwise, if the right child can spare a key, the successor, the smallest key to its right, comes up from the right child. If neither can spare a key, the two children merge with the key pulled down between them. The walk then carries on inside the merged node. In a taller tree the walk down to the predecessor or successor tops up every node before stepping into it, exactly as before.
Press Next step to take out 30, 20 and 10 one move at a time. Before each press, say whether the node that the walk is about to enter can lose a key, and if it cannot, which node supplies a spare key.
Here they are as a ledger, with each deletion split into the top-up at the root and the removal below.
| Step | What happens | Tree afterwards |
|---|---|---|
| start | nothing yet | [10 20] over [5 6 7], [12 17], [30] |
| 30, at the root | [30] is at the minimum and [12 17] can spare a key: 17 goes up, 20 comes down | [10 17] over [5 6 7], [12], [20 30] |
| 30, in the leaf | 30 is removed | [10 17] over [5 6 7], [12], [20] |
| 20, at the root | [20] is at the minimum and [12] cannot spare a key: the two merge around 17 | [10] over [5 6 7], [12 17 20] |
| 20, in the leaf | 20 is removed | [10] over [5 6 7], [12 17] |
| 10, at the root | 10 is in the root and [5 6 7] can spare a key: its predecessor 7 takes its place | [7] over [5 6], [12 17] |
2.7.5 The B-tree, part by part
The contracts chapter listed a contract’s parts in the order you work them out, each with its questions. Here they are answered for the B-tree, with this chapter’s own numbers. Answering the same questions for a workload nobody has named yet is how you make a new design.
| part | question | the B-tree’s answer |
|---|---|---|
| goal | What is the workload, and what does it ask for most often? | An ordered collection far larger than memory: lookups and updates, each one a walk to one key, and range scans. |
| floor | Which resource is scarce? | Fetches. Comparing keys inside a block already fetched is nearly free, and fetching the next block is not free. |
| floor | What can no design beat? | A fetched block of \(B\) sorted keys can end a comparison in at most \(2B+1\) ways, equal to one of its keys or in one of the \(B+1\) gaps around them. Telling apart \(n+1\) answers, one per key and one for “not here”, takes at least \(\log_{2B+1}(n+1)\) fetches, by the contracts chapter’s decision tree with \(b = 2B+1\). |
| promise and invariants | What will you keep, stated on the meaning and not only on the rules, and what must remain true? | The tree holds exactly the keys inserted and not since deleted, and every query answers about that set. The invariants that keep it cheap are the five in the design box: keys in strict order; one more child than keys; no node over full, every node but the root at least half full, rounded down (\(t-1\) to \(2t-1\) keys) and never empty; a root that is a leaf or has two children or more; every leaf at the same depth. |
| idea | Which idea keeps that promise cheap? | Work in blocks, so one fetch buys a whole node; slack in the levels below, so an arrival never shoves; grow at the root, so every leaf stays level. |
| cost | What does it cost, and what does it refuse to cover? | \(\Theta(\log_t n)\) fetches per operation, within a constant factor of the floor because \(t\) is about \(B/2\), giving five fetches for a trillion keys at \(t \approx 340\). Nodes sit about 69% full on average and may sit more than half empty. It refuses to make a write cheaper than a walk to the one leaf in which its key lives. |
| assumes | What must hold for the promise and the cost, and what happens when it does not hold? | Writes do not outrun reads: every write pays a walk to its leaf, which is affordable while reads dominate. When writes arrive far faster than reads, that walk on every write becomes the cost that matters, and the tree spends its fetches where the workload least needs them. That is the LSM-tree’s workload. |
The cost row says how full a node is in two ways, by the least that the rules allow and by the average. A non-root node is only required to fill \(t-1\) of its \(2t-1\) key slots, just under half. When keys arrive in random order, the average node of a tree with large nodes settles at \(\ln 2 \approx 69\%\) full [19]. About a third of the space sits empty, on average. That is the ongoing price of never having to reorganize everything at once.
A variant, the B*-tree, buys some of that space back by sharing keys with a neighbor before a full node splits.
Instead of splitting a full node the moment it overflows, first try to shift a few of its keys sideways into a neighboring node that still has room. Split only when the neighbors are full too, and then split two full nodes into three nodes about two-thirds full rather than two half-full ones. That single change lifts the average occupancy from 69% to about \(2\ln(3/2) \approx 81\%\) [20].
The appendix has a layout that fits every block size at once, without knowing any of them.
Every fix so far, ring to tree to red-black tree to B-tree, took the workload as fixed and changed the structure to survive it. What if the next thing to break isn’t the structure at all? What if it’s the workload?
2.8 I’ll pay it back later
Log-structured merge-tree (LSM-tree)
The B-tree fixed fetching. One fetch brings back an armful, so finding a key among fifty million takes at most three fetches instead of twenty-six. All of that stays. What changes is the work itself.
Until now, most of the work was looking things up. Now most of it is new things arriving: a sensor reading, a click, a payment. They turn up all day. Each one has to be stored where a later lookup can find it.
Follow one arrival into the B-tree. Fetch the nodes on the path down to the leaf where its key belongs, add the key, and write the leaf back. The next arrival’s key has nothing to do with the last one’s key, because things arrive in the order in which the world sends them. So its trip ends at a different leaf, with fetches of its own. Now and then a leaf is full, and splitting it rewrites its parent as well.
Every promise still holds, yet the day goes almost entirely into these trips. A lookup needs its trip, since finding the key is the question it asks. A write does not need one. Nobody is waiting for an answer. All that has to end up true is that a later lookup finds the new value. The write never needed to know where the old value sat, and needed to know only that the store ends up knowing a newer one exists. Yet every structure so far changed a key by finding it first and changing it in place.
Suppose you were forbidden to make the trip at the moment something arrives. Things still have to end up findable, and you must still be able to answer “where is the X?” But an arrival itself may only be written down, right where you’re standing, without going anywhere.
Before reading on, design that. Where does an arriving thing go, and how does the proper place ever get updated? The part that costs you later is the lookup. How does it work afterwards, when the answer might be in what you wrote down or in the place it eventually went?
Ten minutes, and write the lookup rule as numbered steps. You’re done when your rule gives a definite answer for a thing you wrote down twice.
Look at your lookup rule. When the same thing was written down twice, which of the two did your rule read first, and where did it stop?
The promise rests on invariant 1 and on reading newer batches before older ones. Invariant 2, and how the levels are sized and merged, only set the cost.
2.8.1 Writing
So stop writing in place. Keep new writes in a small, sorted buffer held entirely in memory, a memtable. Once it fills up, don’t merge it into anything. Write it straight to disk, whole and sorted, and leave it untouched from then on. That is a flush. The file it makes, an SSTable (sorted string table), never gets modified again. A key updated later doesn’t go back and change the old file. It just gets written again, into whatever memtable is currently open, with a newer timestamp riding along. This is a log-structured merge-tree, LSM-tree for short [21]. The two words in its name say how it works. Log-structured: on disk, new files are only ever added, one after another, and none is written into the middle. Merge: the accumulating pile of files gets merged back down later⬢, off the hot path, the short sequence of work that a single write has to wait for before it can be called done.
That shape is what an LSM-tree looks like, the way a red left-leaning link is what the red-black tree looks like and a fat node is what the B-tree looks like.
Turn the chapter’s opening question around. Instead of losing your keys, keep a note of where everything went. Write each arrival on a list, and once the list has three lines on it, make one trip and file the list away as a sealed page. Six things happen.
| What happens | The list afterwards |
|---|---|
| charger goes in the desk drawer | charger: desk drawer |
| passport goes on the top shelf | charger: desk drawer, passport: top shelf |
| scissors go in the kitchen drawer | charger: desk drawer, passport: top shelf, scissors: kitchen drawer, full |
| (one trip: the list is sorted and filed away as a sealed page) | list empty; Page 1 = charger: desk drawer, passport: top shelf, scissors: kitchen drawer |
| charger moves to the bedside table | charger: bedside table |
| scissors are thrown out | charger: bedside table, scissors: gone |
| umbrella goes on the hallway hook | charger: bedside table, scissors: gone, umbrella: hallway hook, full |
| (one trip) | list empty; Page 2 = charger: bedside table, scissors: gone, umbrella: hallway hook |
The list is the memtable, a trip is a flush, and a sealed page is an SSTable, the file that the design box calls a batch.
Two things in that table look wrong at first. Page 1 still says the charger is in the desk drawer. Nobody went back to correct it, and nobody will ever correct it. And the scissors, which were thrown out, are not erased anywhere. Page 2 simply records that they’re gone. Page 1 is sealed, and a sealed page is never changed.
2.8.2 Reading
So the truth about anything is whatever the newest record of it says, and you find that record by checking the list first, then the pages, newest first. Ask four questions and watch how that works out.
| Question | Where you look | Answer |
|---|---|---|
| Where’s the charger? | list (nothing), Page 2 → found | bedside table, though Page 1’s desk drawer is never consulted |
| Where are the scissors? | list (nothing), Page 2 → found, marked gone | nowhere, because the search stops there and never sees the kitchen drawer |
| Where’s the passport? | list, Page 2 (nothing), Page 1 → found | top shelf |
| Where’s the bicycle pump? | list, Page 2, Page 1: nothing, anywhere | nowhere |
An out-of-date entry on an older page does no harm to a lookup, which never reaches it. Look hard at the last row, though. The bicycle pump was never written down at all, and establishing that took reading every page there is. A question with no answer is the expensive one here, and it gets more expensive as pages accumulate.
Writes got cheap, and reading pays for it, differently depending on what’s being asked. Looking up one key is the walk that the table above just did, stopping at the first file that mentions the key. Asking for a range of keys can’t stop early. Any file might hold part of the answer, so a range scan opens all of them at once and runs a multiway merge across them. It keeps one cursor in each file and, again and again, takes the smallest key under any cursor and moves that cursor on, emitting keys in order and keeping only the newest version of each.
Each SSTable splits what it holds into two pieces, a data file holding the key-value pairs written once in sorted order, and an index locating where each key’s neighborhood begins in that file. Because the data file is already sorted, the index doesn’t have to name every key. It can be sparse, recording only the first key of each block. A lookup binary-searches that small list for the key’s floor, which names the block that could contain the key. The lookup then reads and scans exactly that one block. A key below the file’s first key has no floor, and no block holds it. Sparse is what makes the index small enough to keep in memory. Sorted is what makes it able to answer for keys it has never seen, which is what both an absent key and the start of a range scan need. An index that only knew the keys actually present (a hash table, say) could answer point lookups but could not tell you where a range scan should begin.
2.8.3 Deletion
Deleting can’t erase a byte from a file that’s permanent by design, so a delete writes a tombstone, a record meaning “every older version of this key is dead.” A tombstone is data like any other. A read has to honor it exactly the way it honors a value. That is why “where are the scissors?” answered nowhere rather than the kitchen drawer. The search met the tombstone first and stopped, which is all it ever does. For the same reason, a range scan leaves out every key whose newest record is a tombstone.
2.8.4 Bloom filters
That leaves the expensive case on which the trace ended, the key that isn’t anywhere. The standard fix is to put a Bloom filter in front of each file. It is a small bitmap, cheap enough to keep in memory, that answers “is this key definitely not here?” with certainty and “might it be here?” with a small false-positive rate, the share of absent keys it wrongly calls “maybe”. It is the contracts chapter’s small yes-or-no summary. Each key added sets a few of the filter’s bits, at places computed from the key. A lookup consults the filters first and skips almost every file without reading a byte of it. Nothing about the LSM idea requires Bloom filters, but every major engine ships them, because without them reads for absent keys degrade exactly as fast as writes get cheap. Engines tune how many bits each filter gets. The filter is a tunable answer to a specific cost.
Skipping a file is safe only because the filter never says “not here” about a key that the file actually holds. The read rule depends on that. It stops at the first record it finds, newest first, so every file it skips has to lack the key.
Now imagine a filter that could make the opposite mistake. You ask for the charger. Page 2’s filter wrongly says “not here”, so the lookup skips Page 2 and reads Page 1, which still says desk drawer. You get the old answer, and no error. The scissors fare worse. Skip the page holding their tombstone, and the lookup finds the kitchen drawer, as if they had never been thrown out.
So the two possible mistakes are not equal. Saying “maybe” about a missing key costs one wasted read. Saying “not here” about a key that is there returns a wrong answer, and nothing afterwards can tell.
The filter itself has moved on since Bloom. A cuckoo filter can delete a key [22]. A binary fuse filter is smaller and faster for a set that has stopped changing [23]. A ribbon filter lets you trade building time for space [24]. An InfiniFilter keeps working when nobody knew in advance how many keys would come [25]. None of them is free of false positives, and none ever will be free of false positives. When the possible keys vastly outnumber the stored ones, a filter smaller than the keys it summarizes has to say “maybe” about some keys it never saw. How small it can get for a given false-positive rate has a proved lower bound, sharpened in 2026 [26]. The space forces the flaw on every design.
Where to spend the filters’ memory has a derivable answer. The levels near the top are small, so a few extra bits per key there cost little memory and cut false positives sharply. The bottom level holds most of the keys, so every bit per key there is expensive. The optimum gives the small levels more bits per key than the large one [27]. The question after that is whether to keep re-tuning as the popular keys shift. A 2026 analysis finds that the workload enters the optimum only through a logarithm, so a coarse estimate of it loses little [28].
2.8.5 Compaction
Left alone, the pile of files only grows, and every read gets slower with it. Compaction keeps it bounded. Periodically it merges several files into fewer, dropping shadowed versions and spent tombstones along the way. This is where Page 1’s stale claim about the charger finally dies, long after the charger moved, whenever compaction next rewrites those two pages into one and simply declines to copy the older entry forward. Tombstones are what let it do that safely. The scissors’ tombstone is the proof that the kitchen-drawer entry beneath it is dead, and the tombstone itself can be dropped as well only once it is being rewritten together with every older page.
Leveled compaction, RocksDB’s default, organizes the pile as numbered levels. Each level holds many files of about the same size, cut into disjoint key ranges so that together they read as one sorted batch. Each level is allowed to hold about ten times as much total data as the one above it. The top level is the exception, and the one that causes trouble. Fresh flushes land there whole, so its files overlap each other and a read has to consult every one of them. Letting that level pile up is the classic way an LSM system stalls. When a level exceeds its budget, one of its files is merged into the overlapping files of the level below. Data migrates downward through the levels instead of settling into a few enormous files. It is rewritten each time it descends. That migration is why this scheme keeps reads cheap. A read for a single key consults one file per level below the top. The cost is writing the same data several times over on its way down. How many times? The companion library’s LSM-tree, which merges a whole level at a time, was given a million distinct keys in shuffled order at its default shape: a memtable of 1,024 entries, levels ten times apart, the top level merged when it holds four files. Each entry reached the disk about 13 times, once when its memtable was flushed and about twelve more on its way down.
The original LSM-tree paper starts from two components, one in memory and one on disk [21]. With only two, the small memory component is merged into one enormous disk component, over and over. Each merge rewrites far too much of the enormous one per write. A chain of components, each a fixed factor larger than the one above, keeps every merge to a neighbor of comparable size. Systems today arrange that chain in levels or tiers.
2.8.6 Costs
The costs met so far all have names, and the names turn a pile of tricks into one measurable trade. A read that has to consult several files to answer one question is paying read amplification. Data rewritten each time it descends through the levels is paying write amplification. Stale entries and spent tombstones occupying space until compaction gets to them are paying space amplification. The three pull against each other. Compact more aggressively, and read amplification falls while write amplification climbs. Compact less, and space and read costs grow instead.
The claim that every index faces that tension, the B-tree included, is called the RUM conjecture (read, update, memory).
Key idea: the RUM conjecture
An index pays overheads on Reads, on Updates and in Memory. It can make any two of them small only by letting the third grow. The B-tree keeps reads down and pays on updates and in space. The LSM-tree makes updates cheap and pays on reads, buying some of that back with memory spent on filters.
A B-tree takes the read-optimized corner of this RUM triangle. Every key lives in exactly one place, so reads touch exactly one path. The price is that every write must eventually be applied in that one place, which the writer does not get to choose. Real systems soften that by changing only the copy of the page held in memory and letting a background pass file many changes at once. But the obligation does not go away, and a whole page gets rewritten for a change of a few bytes. An LSM-tree takes the opposite corner. Writes never seek. The price is a read that may have to ask several files the same question and reconcile the different answers it gets back.
The LSM-tree is the structure sitting underneath RocksDB, Cassandra, LevelDB, HBase, and BigTable. Every one of them is a variation on memtable, SSTable, and compaction, tuned differently for whichever corner of that RUM triangle its workload needs most.
2.8.7 Write-ahead log
One more piece lets accepted writes be recovered after a crash. Suppose the list lived only in your head. That works right up until somebody interrupts you. Then it’s gone, and the things on it were never put away. You have neither the note nor the filing.
Memory is that list, and it does not survive losing power. A flush is the only moment anything becomes durable. Between flushes there could be a whole memtable of accepted writes with nothing on disk to show for them. So before a write is allowed into the memtable, it’s first appended to a write-ahead log, a file that is only ever written at the end. Appending is about as cheap as writing gets. After a crash, replaying the log rebuilds the memtable exactly as it was. And the part of the log written for one memtable can be discarded only once that memtable is flushed. Cheap is not free, though. Durability means waiting for the device to confirm the write actually landed. The wait does not care how sequential you were. That is why systems confirm many writes with one wait.
2.8.8 Copy-on-write
Copy-on-write is not part of the LSM-tree. It is the B-tree’s own answer to a different problem, crashes and readers that must not wait. The idea is to keep the tree and stop writing over it. The embedded database LMDB keeps a B-tree. Instead of an immutable pile reconciled at read time, LMDB never writes over a page in use. To modify one, it copies that page, and every ancestor above it up to the root. The instant that copy is finished, one root pointer is switched over to it, in a single indivisible step. A crash mid-copy just leaves the old root intact. Like the LSM-tree’s sealed files, copy-on-write lets immutability do the work that locking would otherwise have to do. It just gets there by copying instead of logging.
Three separate properties follow from that one decision to never overwrite a page.
Only the path is copied. Copying a page means its parent must point at the copy, so the parent is copied too, and so is its parent, up to the root. Exactly the nodes on the path from the change to the top are copied, and no others. Every other node of the new version is the old node, reached by the same pointer. In the figure, one update copies 3 nodes and shares the other 10. In a B-tree three or four levels tall, every write copies three or four pages however many billions of keys sit below them. This is path copying.
The old version survives. Nothing reachable from the old root was changed, so the old root still leads to a complete, consistent tree, the one from before the update.
Readers need no lock. This follows from the other two. A reader holding the old root is reading a tree nobody will ever change, so there is nothing from which to protect it.
The price is paid on writes. Every update rewrites a whole path.
Keep the old root and you can read that version for as long as you like. A structure that keeps its past versions readable is called partially persistent. Path copying is how search trees usually get there. LMDB keeps two meta pages, small fixed pages, one recording the current root and the other the previous one. A new tree becomes visible only when its meta page is written. Pages of an older version stay alive while a reader is still using it. Keeping every past version readable is well understood for B-trees. Making every past version updatable as well, so that history can branch, is called full persistence. External-memory search trees that offer it while matching the classic B-tree’s fetch bounds, averaged over a run of updates, have existed since 2023 [29]. LMDB does not offer it. Only the newest version takes updates.
Pages of old versions have to be reclaimed once no reader can still reach them, which is bookkeeping that the update-in-place B-tree never needed.
2.9 ✎ When assumptions change practice
Say you kept a sorted row of timestamps in memory and found things in it by binary search, halving between first and last. Now the row is a log that keeps growing while you read it. You can still ask for the entry at any position, but nobody can tell you how many entries there are right now, and asking past the end just comes back empty. Binary search needs one thing it no longer has. Name it, say which idea in this chapter was built to search a sorted row without it, and say what that idea costs next to plain binary search.
A team is building a store for sensor readings: millions of writes an hour from tens of thousands of sensors, each reading keyed by its sensor and then its time, so writes land all over the key space. Readings are almost never read back, except as one sensor’s readings over a range of dates, and disk is the cheapest thing they have. A colleague proposes a B-tree, “because that’s what databases use.”
Name which assumption behind that proposal this workload breaks. Say for which structure you would argue instead. Then say exactly which of read, update and space you are agreeing to let grow in exchange, since “it’s faster” names none of them. Last, say what would have to change about the workload for your colleague to have been right all along.
2.10 ◆ What these are actually made of big picture
You just met six structures. They are built out of a handful of small ideas, used over and over in different combinations. The contracts chapter called those primitives. Here is every structure in this chapter, opened up.
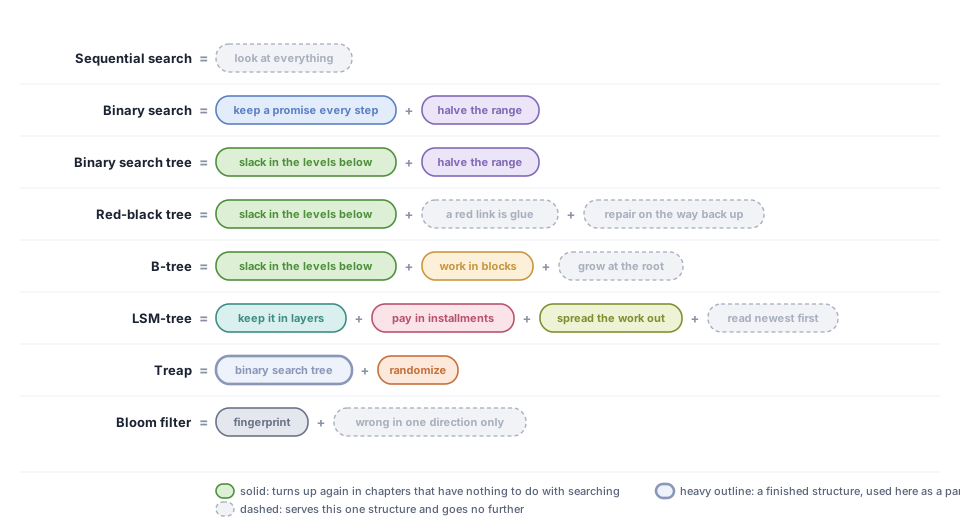
The solid chips repeat, and the dashed ones never repeat. Green, slack in the levels below, shows up in the plain tree and again in the B-tree. Amber, work in blocks, shows up in the red-black tree and again in the B-tree. The B-tree is where the two meet.
Sequential search = look at everything. No setup, no invariants to keep. Every other structure in this chapter is an attempt to avoid doing this.
Binary search = keep an invariant + divide and conquer. The list is kept sorted, an invariant that the structure keeps. That invariant holds again after every change, even if an insert breaks it for a moment on the way. The search runs on a second one, a loop invariant. If the key is anywhere, it lies between the two ends still being searched. The two ends act as bookmarks that always mark exactly what is left to search. Divide and conquer, here halving the range, is how you would guess a number between 1 and 100. You would not start at 1.
What changed: order, kept on purpose, lets one comparison rule out half of what is left.
Binary search tree = the sorted order, kept in the shape instead. Slack in the levels below, because a tree always has room underneath. Writing a name into a sorted paper list pushes everyone below it down a line, while a tree has an empty slot already hanging there. And divide and conquer again, now built into the shape.
What changed: order moved out of the positions and into the shape, so an insert no longer shoves anything.
Left-leaning red-black tree = work in blocks, one or two keys to a node + a red link is glue + repair on the way back up. Work in blocks, with one or two keys to a node; a red link is glue, so two nodes joined by a red link count as a single node holding two keys; and repair on the way back up, three small fixes, each handling one bad shape, applied at every node on the way back from an insert. Nothing is ever rebuilt from scratch.
What changed: the shape now has invariants of its own, so the height stays short in whatever order the keys arrive.
B-tree = the same tree, with the nodes made fat. Slack in the levels below, as in the plain tree; work in blocks again, a page at a time; and grow at the root, the only way for a tree to get taller while keeping every leaf at the same depth. Working in blocks is how a library is shelved into labeled sections, where walking to the shelf is the expensive part while scanning it is nearly free.
The search stayed the same. What changed is the work for which you are being charged. If moving to the next node is as cheap as comparing two keys, you pay for comparisons. If moving to the next node means fetching it from somewhere slower, you pay for the fetch. Every fetch also brings a whole block of neighboring keys along, whether you wanted them or not. A disk works that way, one page at a time. Ordinary memory works that way too, one cache line at a time. Change the price list and a different structure wins, with no new idea needed.
LSM-tree = stop repairing, start stacking. Keep it in layers: express and local trains, a small fast table in memory in front of large slow levels on disk. Pay in installments: never do the big merge when a write arrives, but charge it to the many writes that caused it, the way a monthly subscription spreads one large cost over many days. That is an amortized cost, averaged over a run of writes rather than over inputs. But it says nothing about the one write that happens to trigger the merge. Spread the work out: do the merge itself in small pieces, off the write’s path, so no single write waits for all of it. Production engines run those pieces in the background, alongside the writes. The library’s version does them in turn, which is simpler to follow. Either way the approach works only while merging keeps up. If writes keep arriving faster than the engine can merge them, the unmerged pile grows until new writes have to wait. RocksDB calls this a write stall. Spreading the work out removes the spikes, not the work. Read newest first: always believe the newest copy. Then older copies can stay in place without causing a wrong answer, so nothing has to be overwritten.
What changed again is the price list. This time writes became the expensive direction.
The figure has two more rows. Each is one idea bolted onto something you already have. One is the treap, a binary search tree plus randomization, which the frontier map and the appendix on treaps take further. The other is the Bloom filter.
Bloom filter = fingerprinting + agreeing to be wrong in one direction only. Fingerprinting is how you compare two long documents by their checksums instead of line by line. The filter may say “maybe present” when the key is absent, but it never says “absent” when the key is present. Allowing the first mistake is what makes it tiny, and refusing the second is what makes it safe to skip a file.
Some of these parts can be swapped for another part that does the same job. Figure 2.28 shows a few, each beside the choice this chapter made. Every swap in its first four rows keeps the promise and changes only the cost. The part in the last row cannot be swapped. Believe the oldest copy instead of the newest copy, and a read returns a value that was overwritten long ago.
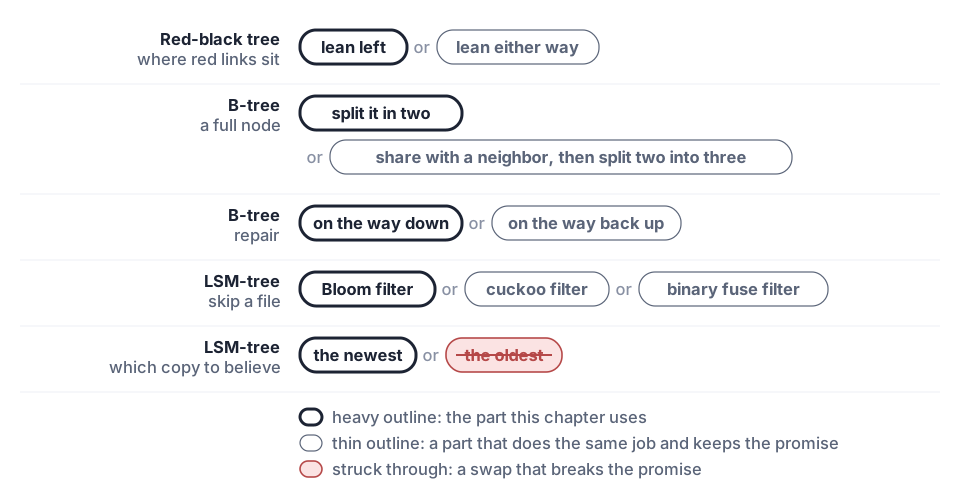
2.10.1 Choosing one, under pressure
This is the table to have in front of you when somebody needs an answer this afternoon. Every structure makes a promise. Two different things can go wrong with it. Break what the promise needs, and the promise is simply false. Break what makes the structure a good choice, and the promise still holds, but you are paying for the wrong thing. In the good-choice column, the last condition in each row is the one that the next structure was built to fix. Each row is a short contract, in the contracts chapter’s sense. The last column gives each contract’s failure mode, which is what you see when what the promise needs is broken. Most rows show you no error at all, just a wrong answer or a slow one.
| structure | the promise needs | it is a good choice when | what keeping it costs | if it breaks |
|---|---|---|---|---|
| Sequential scan | nothing | the collection is tiny, or searched only once | nothing | nothing to break |
| Sorted array | the keys are sorted | comparing keys is cheap, and the collection rarely changes, because every insert shifts the row | shifting the row on every insert | binary search answers “not here” about a key that is there, with no error |
| Binary search tree | at every node, smaller keys on the left and larger ones on the right | comparisons are cheap, and keys arrive in mixed order, because sorted arrival grows one long line | nothing | a search turns the wrong way and misses a key that is there |
| Red-black tree (LLRB) | its five invariants are restored after every insert and delete | the height is worth a small repair on every change, and reaching any node costs about the same as reaching any other | a repair on every insert and delete | out of order, it misses keys that are there; with only a color invariant broken, answers stay right but a path can grow as long as the tree |
| B-tree | the keys are in order, inside every node and across nodes | reaching a node costs far more than comparing the keys inside it, and a write can afford to go straight to the one place where its key lives | fat nodes, each about a third empty | out of order, it misses keys that are there; with only the fullness or the depth broken, answers stay right, but a lookup is no longer bounded by the few fetches that the height allowed |
| LSM-tree | finished files are never edited, and a read believes the newest record it finds | writes arrive faster than reads, a read can afford to look in several places, and there is spare time later to merge files | merging later, and the write amplification it costs | a key that was thrown out comes back with its old value, or an accepted write is gone after a crash, and no error says so |
Almost every row is the right answer for somebody, and none of them is the right answer for everybody. The contracts chapter gave that shape a name. The rows are non-dominated, meaning no other row is at least as good on every cost and better on one.
That table is what I draw at a whiteboard. The one below, with the numbers, is the one I look up.
2.10.2 What each one costs
Worst case throughout, for \(n\) keys. \(h\) is the height of a tree nobody is keeping balanced, which is anywhere between \(\log_2 n\) and \(n\). \(t\) is the B-tree’s minimum degree, defined under “Blocks and fan-out”. In the tree rows, rank and select cost the height only if every child link also carries a count of the keys below it, one more field than the space column lists. In a B-tree those counts sit in the parent’s node, where one fetch reads them all.
| structure | search | insert | delete | min/max, floor/ceiling, rank/select |
extra space per key |
|---|---|---|---|---|---|
| Sequential scan | \(\Theta(n)\) | \(\Theta(1)\) to append, \(\Theta(n)\) to check first | \(\Theta(n)\) | \(\Theta(n)\) | none |
| Sorted array | \(\Theta(\log n)\) | \(\Theta(n)\) | \(\Theta(n)\) | \(\Theta(\log n)\); min/max and select are \(\Theta(1)\) |
none |
| Binary search tree | \(\Theta(h)\) | \(\Theta(h)\) | \(\Theta(h)\) | \(\Theta(h)\) | two links |
| Red-black tree (LLRB) | \(\Theta(\log n)\) | \(\Theta(\log n)\) | \(\Theta(\log n)\) | \(\Theta(\log n)\) | two links, one bit |
| B-tree | \(\Theta(\log_t n)\) fetches | \(\Theta(\log_t n)\) fetches | \(\Theta(\log_t n)\) fetches | \(\Theta(\log_t n)\) fetches | each node can be more than half empty |
Five things to notice in the table.
Every tree row reads the same across. Search, insert, delete and all six ordered questions cost the height, because all of them are the same walk wearing different hats, visiting one node on each level. That is why the trees in this chapter were judged on height and nothing else.
One row is beaten on time. In every time column the red-black tree’s bound is no worse than the plain binary search tree’s bound. In the worst case it is strictly better. The plain tree is here because you have to build one before the repairs make sense. You would not ship one when someone else chooses the arrival order. Still, the plain tree keeps one small edge. It carries no color bit and pays nothing on the way back up.
The ordered questions are the reason to be here at all. On a typical search a hash table beats every row in this table, though it does not beat them in the worst case. What it cannot answer, short of looking at every key, is anything in the fifth column, because throwing the order away is how it got its speed. If you never need that column, use a hash table and skip all of this. Everything here is the price of keeping order.
The sorted array’s split personality is the chapter’s opening lesson, in one cell. select is free because position is rank. That is the same fact that makes insert cost \(\Theta(n)\).
The LSM-tree has no row in this table, because no single formula fits it. A write costs an append to the log, a wait until that log write is confirmed, one in-memory insert, and its share of the compaction that comes later. A read costs more than any formula in \(n\) says. It depends on how many levels you let pile up, how much you compact, and whether a Bloom filter sits in front. You choose those, and they set its cost.
2.10.3 The same nine ideas, over and over
Read down this table.
| primitive | where else it turns up |
|---|---|
| keep an invariant | Dijkstra’s settled set, insertion sort |
| divide and conquer | mergesort, the fast Fourier transform |
| slack in the levels below | AVL trees, skip lists, heaps |
| work in blocks | disk pages, cache lines |
| keep it in layers | skip lists |
| pay in installments | a growable array, union-find |
| spread the work out | a hash table that resizes a little at a time, a real-time queue |
| randomization | quicksort’s pivot, hash tables |
| fingerprinting | checking files match, Rabin–Karp |
A red link is glue, repair on the way back up, grow at the root and read newest first are not among the nine. Each belongs to one structure. They are the dashed chips in the figure.
All nine ideas turn up again outside these six structures, in the places that the table lists.
When a workload arrives that matches nothing in the table, you are not stuck hunting for a name you recognize. You ask what the workload costs, which promise to keep, and which of these ideas delivers that promise. Then you build the thing that does not have a name yet.
2.11 ◆ Where that leaves the keys big picture
Each structure here worked until the world broke one of its assumptions. The next one was built to work without that assumption. The table in “Choosing one, under pressure” is that story, one row per structure.
Apart from the red-black tree beating the plain binary search tree on time, not one of those structures is better than the one before it. Each one suits a different mix of workload and machine and is still the best choice for that mix today. A sorted array is exactly right for data that never changes. A plain binary search tree is fine when the keys arrive shuffled. Fat nodes are wasted wherever reaching a node is as cheap as comparing a key. They win wherever reaching one is the expensive step. On disk they win by a wide margin, and in memory they win one cache line at a time.
So the most useful thing to carry out of here is a habit. Before choosing a structure, ask what this workload actually costs: what’s cheap, what’s expensive, how often things change, and whether anyone will ever need the keys in order. Answer that, and you know which of these structures to choose. Answer it wrong and you’ll have built something beautiful for a problem nobody has.
Almost everything that this chapter named is what the rest of the world calls it too: node, root, leaf, child, parent, subtree, 2-node, 3-node, rotation. Walk into any room where this material is spoken, open any implementation, ask any model, and those words will be waiting, now meaning something.
This chapter coined three words of its own: glue for a red link, an armful for what one block fetch buys, and a spare red link. They stop at its edge. Elsewhere the ideas go by their standard names: a red link inside a 3-node, a block, a borrowed red link.
The keys were never really the point. Knowing what it costs to find them was the point.
2.12 ✎ Hands-on projects practice
Ten projects come first. In each you build something, measure something, or explain something to another person. They have no single right answer, so judge them against the checks each one asks you to build. After them come the self-check problems, numbered exercises that each have an answer you can check. Do some of each. The exercises show what you know, and the projects show what you can do.
Where a project needs code, let an AI write it. The times given assume that the AI writes it. Your job, even when the AI helps, is saying what the code must do, building the check that shows it does what it must do, and judging what comes back.
Project 1 · hard · ~2 hours
Build a balanced tree. Have an AI write a binary search tree’s insert and lookup, then the red-black tree’s insert on top of it, using only the three repair moves (rotate left, rotate right, flip colors). Before you ask, write down what you will check: both trees agree on every lookup over the same random keys, and after every insert the red-black tree keeps its keys in order, keeps its root black, obeys both red-link invariants, and crosses the same number of black links on every path down. Build that check yourself. Then break one repair move on purpose, for instance a flip_colors that forgets to color the node red, and see which part of the check notices.
Project 2 · the binary search tree · ~45 min
Deliver what the tree promised. On your binary search tree, add min, max, floor and ceiling, then a subtree-size field on every node, and rank and select. The AI can write them, but the checks are yours. Check that select(rank(k)) returns k again for every key you inserted, and that rank of a key you never inserted still returns a sensible count. Say what “sensible” means, exactly, before you run anything.
Project 3 · the binary search tree · hard · ~1 hour
Delete it two ways. Have an AI write both deletions from the binary search tree section, copy the key (Hibbard’s) and move the node. Build two copies of the same tree, and in each hold a reference to the successor’s node before you delete the same two-children key. Afterwards, compare the keys and the shape, and see that they agree. Then ask each copy where the node you held has gone. In one it is still in the tree, and in the other it is not in the tree. Say what kind of program would notice the difference.
Project 4 · the binary search tree · hard · ~1 hour
Write the specification first. Before any code exists, write the contract for delete on an ordered dictionary: what it means (which key leaves, and what happens when the key isn’t there), which invariants the tree must still keep afterwards, what it may cost, and what you fix exactly versus what you leave to whoever writes it. Hand only that to an AI and take the code it writes. Then look for a program that meets every line you wrote and is still wrong for you. Project 3 is one place to start. Name the line that your spec was missing, and add it.
Project 5 · binary search tree against red-black tree · ~45 min
Pick the order that hurts. Your service keeps its users’ keys in a plain binary search tree, and the users choose the keys. Play the attacker first. Sorted order is the obvious attack, and the chapter has already shown it. Find one that does not look sorted and hurts just as much, and measure what one lookup costs after a thousand keys arrive that way. Then write the guarantee the service needs as one sentence about cost, say which structure in this chapter delivers it, and say whether a guarantee that holds only on average, over random arrivals, would be enough here. An AI can write the measurement, but the attack and the sentence are yours.
Project 6 · sorted array against tree · ~45 min
Same structures, new workload. Hold the same keys, inserted in random order, in a sorted array and in a binary search tree. Run a workload that is 90 percent inserts of new random keys, and one that is 90 percent lookups, first starting from a thousand keys and then from a million. Say which structure wins each run. If the winner of the insert-heavy run changes as the collection grows, find roughly where it changes, and explain why it happens there. An AI can write the timing code. You decide what it must hold fixed between runs, including how many operations run and how large the collection ends up. Measure it. Do not reason it out.
Project 7 · hard · ~1 hour
Judge something you didn’t write. Take an ordered-collection implementation you had no hand in: a standard library’s sorted map, a database’s index, or whatever a model hands you when you ask for one. Read it for its assumptions, not its correctness: which of this chapter’s structures is it, what does it assume is true about the workload, and what arrival order or access pattern would make it the wrong choice? Write those three down before you look at any documentation or ask an AI, then check. Most of the code you will ever depend on is code you did not write, and this is how you check it against what it promises.
Project 8 · the B-tree · hard · ~3 hours
Repair on the way back up. Change one decision in the B-tree’s design. Instead of splitting full nodes and topping up thin ones on the way down, change the leaf first and repair on the way back up, splitting a node that overfilled and fixing one that underflowed (Table 2.6). Make the order \(m\) the tree’s parameter instead of \(t\). Before you ask an AI to write it, write down what stays the same, the five invariants of the design 2.3. Build the check from them yourself, with its bounds written in \(m\), and run it after every operation on short random sequences, beside a plain set holding the same keys. Then predict, before running anything, which version does more splits and merges and which runs faster. Add counters to a copy of the library’s B-tree. Measure both on a million random keys, at \(t = 2\) and at \(t = 64\), with your version at order \(2t\) and the library’s version at minimum degree \(t\). Last, run order 5, which no minimum degree can describe. Start from [71 84] over [56 60 65 68], [73 75] and [88 92], insert 62, then delete 75, and draw each tree before you run it. Say which bound in your check differs from the library’s check_valid(), and why the chapter’s walk down could not keep an order-5 tree within its bounds.
Project 9 · ~20 min · no notes
Teach it back. Explain to somebody else why a B-tree’s nodes hold many keys while a red-black tree’s binary nodes hold one each. If you can’t name what changed about the cost of reaching a node, the explanation isn’t finished yet.
Project 10 · design · hard · ~3 hours
Design a set for your own workload, with an AI. A service keeps timers. Each timer is a time, kept as an integer key. Timers are set and canceled, and the service keeps asking whether this one is set and which one fires next after a given time. About fifty questions come for every change, there are about 50,000 timers, and memory hands over whole blocks. The chapter’s trees are one answer. Find a better one, and show that it is better.
- Write the problem first. Write the top half of a box: goal, promise, cost, assumptions. Leave the idea and the invariants empty. They are what the search will find.
- Check the promise where a machine holds it. Read
Workbench.Contractin the library’slean/AlgoDesign/Searching/Workbench/Spec.lean, the contract that every candidate owes. Check that each line says what your promise says, and change the contract where it says something else. - Hand the top half to an AI, with the bench’s block memory from
python/algodesign/searching/workbench.py. Ask for the code in one language and for its box. Keep some seeds to yourself. - Judge what comes back. Run
check_promiseon your own seeds, andmeasureit on your workload againstllrb_baselineandbtree_baseline. - Repair, and say why. Each time something is wrong, decide whether it is the code, the box, or the design, and write one line saying which and why.
Hand in the whole final box, the lines from step 5, and the measurements. ★ Prove in Lean that your design meets Workbench.Contract.
Another brief or another AI gives another run. This is one.
Round 1. The brief promised add, cancel and is it set. The AI returned a hash table that took about one fetch per operation, against 4.0 fetches for the B-tree and 15.7 for the LLRB, and every check passed. It could not say which timer fires next, because the brief never asked. Fix the box: the promise gains next larger, and the contract gains NextLargerSpec.
Round 2. The assumptions said the keys spread over 0 to \(10^9\). The AI cut that range into 1,100 equal slices of one block each and computed a key’s block from the key. That gave one fetch per operation, and every hidden check passed. The AI’s own box said what bunched keys would do to that design. Real timers bunch close to the present. With every timer’s key below a million, the same code took 337 fetches per operation, and the B-tree took 4.0. The code kept its promise. The box assumed what is not true. Fix the box: the assumptions now say nothing about how keys spread, and the measure takes the worse of spread and bunched keys.
Round 3. The AI returned a B+-tree kept nearly full. On spread and bunched keys alike, it needed 3.0 fetches per question and 820 blocks, against the B-tree’s 4.0 fetches and 2,361 blocks. Writes pay for that saving. An insert into a full leaf may move keys into its neighbors. In this run, inserts averaged about 12 fetches. At fifty questions per change that trade wins. At one question per change it costs 4.9 fetches per operation against the B-tree’s 4.0. If the workload changes that way, change the design.
Along the way the AI asked whether a slot could hold a Python integer of any size. If it could hold one, many keys would fit in one slot, and the count of fetches would mean nothing. The bench was fixed: a slot holds one 64-bit word. The check you build is part of the design too.4
Here is flip_colors, written the way almost everyone writes it the first time.
flip_colors as first written, Python.
def flip_colors(h):
    h.red = True
    h.left.red = False
    h.right.red = False
Every insert in this chapter still works. Every tree it builds is valid. Run a thousand random insertions and nothing complains, which is why this version gets published.
Answer these in order.
- Before running anything, and without looking back (you met the answer in the red-black deletion section), say which of the two jobs that
flip_colorsdoes in this chapter is the one that this version cannot do, and name the caller that needs it. - Write the smallest input that tells the two versions apart, meaning a key sequence and the operation to run afterwards. Smallest means fewest keys. If yours has more than five, keep cutting.
- Now run it. Was your prediction in (1) right? Write down how confident you were before you ran it, then compare.
If you want a machine to check your answer, run both versions on your input and ask the chapter’s check_valid().
Only after you have your own answer, hand the broken version to an AI and ask it to find the bug. Some will find it. Others will confidently report a different bug that is not the problem here, such as a missing check for an empty child. The four lines show only the insertion case, so whether a model looks past that case is luck. An AI cannot know what it was not shown, and you chose what to show it.
2.13 ✎ Self-check problems practice
Transfer 1 · middling · ~30 min
Which phones are still on the shortlist? A shop’s website lists phones as they arrive, each with a price in euros and a battery life in hours. A phone is on the shortlist unless another phone costs no more, lasts no less, and is better on at least one of the two. Eight phones arrive in this order, each written as (price, battery life): A (300, 20), B (500, 30), C (400, 18), D (450, 33), E (200, 15), F (350, 26), G (600, 32), H (250, 28). No two of them cost the same.
- After all eight have arrived, which phones are on the shortlist? What did the contracts chapter call that set?
- Keep the shortlisted phones in a search tree ordered by price. Read in price order, what do their battery lives do, and why does that stay true? Use it to handle each arrival with
floorandceilingfrom Order queries, without reading the whole list. Which walk says the new phone is beaten, and which walks say whom it knocks out? Run it on the eight arrivals and count the walks. - H knocked out two phones at once. Why does that not make the method slow over a long run, and which of this chapter’s ideas says so?
- E (200, 15), H (250, 28) and D (450, 33). H beats A and F, being cheaper and lasting longer. D beats B and G, and A beats C. The contracts chapter called this set the Pareto frontier, or the non-dominated set.
- In price order the battery lives go strictly up. If a more expensive phone did not last longer, the cheaper one would beat it, and a beaten phone is never kept. So a new phone at price \(p\) with \(b\) hours is beaten exactly when
floor(p), the most expensive kept phone that costs no more, lasts at least \(b\) hours. That phone lasts longest among all the kept phones that cost no more. If the new phone is not beaten, insert it. Then askceilingof a price just above \(p\). While the phone found lasts no longer than \(b\), delete it and ask again. A is kept. B is kept. C is beaten by A. D is kept and knocks out B. E is kept, and F is kept too. G is beaten by D. H is kept and knocks out A and F. That is eightfloorwalks and nineceilingwalks, 17 in all, counting for each kept phone the lastceilingwalk, the one that finds a phone lasting longer or nothing at all. Add six inserts and three deletes. Comparing every phone with every other would instead check 28 pairs. - Every phone is inserted at most once and deleted at most once. So \(n\) arrivals make at most \(n\)
floorwalks, \(n\) inserts, \(n\) deletes and \(2n\)ceilingwalks, each of at most about \(2 \log_2 n\) steps in a tree kept short, like the red-black tree. That is at most \(5n\) walks, about \(10 n \log_2 n\) steps in all, however the knockouts bunch up. Each knockout is paid for by the arrival that inserted the phone, which is the idea pay in installments.
Transfer 2 · middling · ~25 min
Why must a small filter say maybe? A phone blocks calls from three of the 1,000 extension numbers at work, 000 to 999. It keeps a summary of its blocklist in 16 bits, and answers “is this number blocked?” from the summary alone.
- Use the contracts chapter’s count to find the fewest bits that can hold every possible blocklist of three exactly, so that every question gets the right answer. How does that compare with writing the three numbers down?
- Show that the 16-bit summary must answer some question wrongly. If it may never say “not blocked” about a blocked number, which wrong answer is left, and which structure in this chapter makes exactly that choice?
- The phone moves on to blocking ordinary ten-digit phone numbers, \(10^{10}\) of them. Redo part 1. The summary stays 16 bits. What does that say about where such a summary pays?
- 28 bits. There are \(1000 \cdot 999 \cdot 998 / 6 = 166{,}167{,}000\) possible blocklists. If two different lists got the same bits, the phone would answer every question the same way for both, and so answer wrongly about a number on one list and not on the other list. So each list needs its own pattern of bits. With \(m\) bits there are \(2^m\) patterns, and \(2^{27} = 134{,}217{,}728\) is too few, while \(2^{28} = 268{,}435{,}456\) is enough. Writing the three numbers down takes 30 bits, 10 each, since \(2^{10} = 1{,}024\). The plain list is nearly as small as anything exact can be.
- There are \(2^{16} = 65{,}536\) patterns and 166 million lists, so two different lists share a pattern. Take a number on the second list but not on the first. The phone answers the same about it for both. For the second list it may not say “not blocked”, so it says “maybe”. So for the first list it says “maybe” about a number that is not on it. That is the only kind of wrong answer left, a false positive. A Bloom filter is built to make this mistake and never the opposite one, saying “not blocked” about a number that is blocked.
- There are about \(10^{30} / 6\), or \(1.67 \times 10^{29}\), possible lists now. Since \(2^{97}\) is about \(1.58 \times 10^{29}\), that is a little over \(2^{97}\). An exact summary needs at least 98 bits. The plain list takes 102 bits, 34 bits per number, since \(2^{34}\) is about \(1.7 \times 10^{10}\). The exact cost grows with the logarithm of how many numbers are possible, and the 16-bit summary does not grow at all. A summary pays where the possible keys vastly outnumber the stored ones. There, as part 2 shows, it cannot avoid saying “maybe” about some keys it never saw.
Transfer 3 · middling · ~20 min
Split into three. The B-tree in this chapter splits a full node into two half-full ones. The B*-tree changes that one step. Before it splits a full node, it moves a few keys into a neighboring node that still has room. It splits only when the neighbor is full too, and then it turns two full nodes into three.
- Which of the box’s five invariants changes, and to what? Which stay exactly as they were?
- Does the promise change? Say which invariant it rests on.
- What happens to the number of fetches that a lookup needs, and to the work one insert does?
- Invariant 3 changes. Every node but the root is now at least about two-thirds full, not half full. The root may hold up to about a third more keys than an ordinary node, so that when it splits, both halves already meet the two-thirds rule. Invariants 1, 2, 4 and 5 stay.
- No. The promise rests on invariant 1, the order, and moving keys between neighbors keeps it.
- Fuller nodes mean more children per node. So the tallest that the tree can grow is lower, and a lookup needs no more fetches than before in the worst case. The average node goes from about 69% full to about 81%. An insert does more work: it reads a neighbor before splitting, and a split rewrites three nodes instead of two.
Here are thirty-eight exercises. Each shows roughly how long it takes, and everything you need for them is in the chapter so far. You can mark much of it by running the library on the same input: a final state, a search’s answer, or whether a tree is valid, where check_valid() names the first invariant that fails. The steps on the way, such as which repair fired, you check by hand against the chapter. The answers are on a page of their own.
If you only do four, do Exercises 4, 18, 22 and 23.
They are grouped by kind of task, not by structure. To practice one structure, here are the exercises for each section:
- Checking one place at a time: 1
- An orderly key ring: 2, 3, 24
- Escaping the line: 4, 5, 21
- Sticky red links: 6, 7, 8, 9, 14, 15, 16, 17, 18, 19, 20, 22
- Frankenstein: 10, 11, 12, 23
- I’ll pay it back later: 13
2.13.1 Run it and report the state
Exercise 1 · gentle · ~5 min
Build a list that refuses duplicates by inserting 4, 9, 4, 2, 9, 7 one at a time, checking each key against the keys you have accepted so far, from the first, and stopping at a match. What does the list hold at the end, and how many key comparisons did the build cost?
Exercise 2 · gentle · ~5 min
Here is a sorted row of fifteen keys: 2, 5, 8, 11, 14, 17, 20, 23, 26, 29, 32, 35, 38, 41, 44. Binary search it for 14, and write down every key at which the search looks, in order.
Exercise 3 · gentle · ~5 min
Here is a sorted row of fifteen keys: 2, 5, 8, 11, 14, 17, 20, 23, 26, 29, 32, 35, 38, 41, 44. Binary search it for 33, and write down every key at which the search looks, in order.
Exercise 4 · gentle · ~10 min
Insert 60, 30, 80, 20, 45, 70, 90, 40, 50, 42 into an empty binary search tree. How tall is it, counting nodes (a single node has height 1)? What are ceiling(55), rank(43) and select(6), counting from select(0) as the smallest key?
Exercise 5 · middling · ~15 min
From the tree you built in Exercise 4, delete 30 by copying the successor’s key up into the node (Hibbard’s deletion, delete_hibbard in the companion library). Which key now sits where 30 was, and what hangs off it?
Exercise 6 · middling · ~25 min
Insert 75, 51, 79, 9, 36, 72, 40, 71, 70, 66, 4, 69 into an empty left-leaning red-black tree. Which keys have a red link into them?
Exercise 7 · middling · ~15 min
Starting from an empty left-leaning red-black tree, insert D, C, A, B, E, then F. After each insert, name every repair that fires (rotate left, rotate right, flip colors), in order, or say that none fires. Letters compare in alphabetical order.
Exercise 8 · hard · ~20 min
Build the left-leaning red-black tree from 10, 20, 30, 40, 50, 60, then delete the smallest key twice in a row. Each time, say whether move_red_left fired, and at which node, and draw the tree afterwards.
Then: If the second deletion needed no push at all, explain what the first one left behind that made it unnecessary.
Exercise 9 · middling · ~15 min
Chapter 1 listed five things that a left-leaning red-black tree holds true at once, before you had met the tree. Without scrolling back, write all five. Then, for each one, name the repair in this chapter that puts it back when an insert breaks it, or say that an insert never breaks it. Check your list against the box for the left-leaning tree (The design 2.2).
Exercise 10 · middling · ~15 min
Insert 17, 21, 8, 48, 27, 32, 11 into an empty B-tree of minimum degree t = 2, so each node holds at most 3 keys, using the chapter’s top-down insertion. What keys are in the leftmost leaf?
Exercise 11 · hard · ~25 min
Build the B-tree at t = 2, top-down as in the chapter, from 17, 21, 8, 48, 27, 32, 11, 7, then delete 27 and then 48. Draw the tree after each. Each time, say which of the chapter’s moves the deletion used: replacing the key with its predecessor or successor, redistributing a key from a neighbor, or merging two nodes. Then say what decided the move each time: where the key sat, and what its children or neighbors held.
Exercise 12 · middling · ~20 min
Give a B-tree room for three keys per node (minimum degree t = 2) and insert 1 through 20 in order, splitting top-down as the chapter does. How many splits happen, how tall is the tree at the end, and how many nodes does a search for 17 fetch? Then count the same search in the plain binary search tree that the same insertions build, and say the most that any search can fetch in a perfectly balanced binary search tree of 20 keys.
Exercise 13 · middling · ~20 min
Keep the chapter’s list of where things are, allowing yourself three entries before a trip. In this order: the keys go in the hall bowl, the tickets go in the desk drawer, then the keys move to your coat pocket, and the spare charger goes in the car; then the tickets move to your wallet, the spare charger is thrown away, the passport goes on the top shelf, and the umbrella goes by the door. Write out both sealed pages and the list exactly as they end up. Then answer “where are the keys?”, “where is the umbrella?” and “where is the flashlight?”, counting how many pages each question touched.
Then: The keys changed place before the first trip. Does Page 1 hold one entry for them or two, and why is that allowed when a page is never changed? Then say which of the three questions a Bloom filter on each page would have made cheaper, and by how many pages.
2.13.2 Which promise broke
These exercises are about the five invariants of a valid tree: the keys are in order; the top node is black; a red link always leans left; no node has two red links touching it, not one on each side, and not one chained below the other; every path crosses the same number of black links.
First build the reference tree: insert 75, 51, 79, 9, 36, 72, 40, 71, 70, 66, 4, 69 into an empty left-leaning red-black tree. It is valid; check that before you go on.
Each exercise below is a tree that an AI model returned after changing the insert code, claiming the tree still passes its checks. Build the tree and name every invariant it now breaks.
Most are the reference tree with one thing changed. Three give you different keys or a different order; build what they say. Some changes only recolor a link; others move keys or change the tree’s shape.
One of these trees is valid. For that one, “nothing is broken” is the right answer.
Exercise 14 · middling · ~10 min
The model returns the reference tree with this changed: exchange the keys 70 and 72, touching no link and no color.
Exercise 15 · middling · ~5 min
A different tree, built from 20, 10, 30: paint the top node (20) red.
Exercise 16 · middling · ~10 min
On the reference tree, apply rotate_right at the root (71), exactly as the repair code does.
Exercise 17 · middling · ~10 min
A tree of three nodes: a black link into 30, a red link into 20 as 30’s left child, and a red link into 10 as 20’s left child.
Exercise 18 · middling · ~10 min
On the reference tree, repaint the link into 51 from red to black.
Exercise 19 · middling · ~25 min
The same twelve keys, inserted in this order instead: 4, 79, 69, 71, 51, 9, 40, 75, 70, 72, 36, 66.
Exercise 20 · hard · ~15 min
On the reference tree, repaint the link into 69 from black to red.
Then: Count how many promises that one repaint took down, then say whether the count means the promises are badly chosen, or something else.
2.13.3 You supply the input
Exercise 21 · gentle · ~10 min
Make a plain binary search tree on the keys 1 to 8 as tall as it can possibly be. Give the insertion order. Then find a second order that reaches the same height but does not look sorted, and say what all such orders have in common.
Then: How many of the 8! possible orders of the eight keys reach that height? Guess first, then count.
Exercise 22 · middling · ~10 min
Now do the same to the left-leaning red-black tree: find an insertion order of 1 to 8 that makes it 8 tall, or as tall as you can. Predict what will happen before you run anything, and write the prediction down.
Then: State what you found as a sentence about insertion orders rather than about trees.
Exercise 23 · middling · ~25 min
Falsify this (find a case that shows it is false): two people who insert the same fifteen keys into a B-tree at minimum degree t = 2, in different orders, end up with the same tree. Then measure the height of every tree you built while falsifying it.
Then: Of the two things you checked, the tree’s shape and its height, say which of them a caller is entitled to depend on, which of them the caller is not entitled to depend on, and why the second is not a bug.
Exercise 24 · middling · ~10 min
Falsify this: binary search makes a sorted array beat the tree at everything, so the trees were never needed. Your answer has to name an operation and count something, not name a structure.
Then: State the workload under which the claim is actually true.
2.13.4 Which idea do you reach for
Each of these nine exercises describes a situation, most of them new to this chapter, and asks which of the nine ideas above you would use. Each idea is the right answer to exactly one of them.
Exercise 25 · middling · ~5 min
A messaging service keeps, for every conversation, the messages in time order. Reads ask for the newest few. Writes arrive in bursts, far faster than reads, and a message is never edited once sent. Which idea do you reach for first?
- slack in the levels below
- keep it in layers
- work in blocks
- fingerprinting
Then: Name the failure mode you just bought, in this chapter’s terms.
Exercise 26 · gentle · ~5 min
A read-only dataset of 40 million records ships once a month on a disk image and is loaded into memory on arrival. Every query is a lookup by id, or asks for all records whose ids fall between two bounds. Nothing is ever inserted between shipments. Which idea do you reach for first?
- slack in the levels below
- keep it in layers
- divide and conquer
- pay in installments
Then: What single change to this workload would make your answer wrong?
Exercise 27 · middling · ~5 min
A service must answer “have we seen this id before?” for a stream of billions of ids, in memory that holds only a small fraction of them, where a wrong “yes” costs one wasted lookup and a wrong “no” corrupts the records. Which idea do you reach for?
- fingerprinting
- work in blocks
- keep an invariant
- randomization
Then: Errors here have two directions. Say what your choice does to each of them, and why that matches this workload.
Exercise 28 · hard · ~10 min
An index is a plain binary search tree, and its keys are ids chosen by whoever is calling. One caller has worked out that a particular arrival order makes every lookup slow. You cannot change the tree’s code, because it is a library on which you depend. You can change only the order in which keys are handed to it: the index is rebuilt from scratch every night from the full list of ids, and you may reorder that list before passing it on. The ids are opaque tokens: the library can compare them, but your code cannot compare them. Which idea do you reach for?
- slack in the levels below
- divide and conquer
- randomization
- work in blocks
Then: Compare the guarantee you just bought against a balanced tree’s guarantee, in one sentence.
Exercise 29 · middling · ~10 min
A sorted array is the right structure for a read-heavy index, but a few hundred inserts a day do arrive, and each one shoves a large part of the array along, stalling the service for a visible moment. The total work is affordable; it is the spikes that are not affordable. Which idea do you reach for?
- pay in installments
- divide and conquer
- spread the work out
- keep an invariant
Then: Name a workload where this is the wrong trade, and say what about that workload makes it wrong.
Exercise 30 · middling · ~5 min
An in-memory red-black tree holds a hundred million keys. A profiler says lookups spend nearly all their time waiting on memory rather than comparing: almost every node visited is a cache miss, and each miss brings in a whole cache line, typically 64 bytes, of which the node uses a fraction. Nothing moved off the machine. Which idea do you reach for?
- divide and conquer
- work in blocks
- randomization
- keep an invariant
Then: Name the block here, and say why a disk or a network round trip would have led you to the same idea.
Exercise 31 · middling · ~5 min
An in-memory index must support lookup, ordered iteration, and range queries, with reads and writes in about equal numbers. The keys are timestamps from thousands of sensors whose readings arrive late: each sensor’s keys come in increasing order, but a new key can land anywhere in the range already stored. You control the structure entirely. Which idea do you reach for?
- divide and conquer
- keep it in layers
- slack in the levels below
- fingerprinting
Then: Say why each of the three wrong answers fails here.
Exercise 32 · hard · ~10 min
You add a subtree-size field to every node so the tree can answer rank and select. Insert maintains it. A colleague now adds a delete, and a bulk-load path that builds nodes directly. What makes the field safe to read?
- keep an invariant
- pay in installments
- work in blocks
- randomization
Then: This is the same risk that the broken trees in Exercises 14 to 20 showed: a promise that holds only until a new code path touches the nodes. Say why.
Exercise 33 · middling · ~5 min
A nightly batch job appends a hundred million log events to a growable array that doubles its capacity whenever it is full. The job is judged only on when the whole run finishes; nobody waits on any single append. A reviewer objects that some appends copy the entire array. Which idea says the objection does not matter here?
- pay in installments
- spread the work out
- work in blocks
- slack in the levels below
Then: Change one thing about the workload that would make (b) the right answer instead.
2.13.5 The tests pass. What did they miss?
Code that fails its tests is easy to catch. The costly kind passes every test, because nobody wrote a test for the requirement it breaks.
Exercise 34 · hard · ~20 min
A colleague’s key-value store is an LSM-tree: writes go into a memtable, a full memtable is flushed to a sorted file that is never edited again, deletes write tombstones, reads go newest first, and compaction merges files in the background. Three tests guard it, and all three pass: after any random sequence of writes and deletes, every read agrees with a plain dictionary given the same sequence; the same holds after every compaction; and every file on disk is sorted and unchanged once written. In its first week the machine loses power. The store restarts cleanly and every file is intact, but the last few hundred writes that the service had confirmed to its callers are gone. Name the requirement that the tests never stated, and write it as one sentence that a test could check.
Then: Describe the test that would have failed, then say what the store must do to pass it and what that costs on every write.
2.13.6 Fill in the contract
No options this time. The workload below is not one of the chapter’s, and the answer is not a name: it is a short answer to each of the questions that the B-tree answered in “The B-tree, part by part”.
Exercise 35 · hard · ~40 min
A weather network has thousands of stations, and together they send tens of thousands of readings a second, all day. Each reading must be confirmed to its station within ten milliseconds, every time, even in the busiest minute of the year, and a confirmed reading must never be lost, even in a power cut. Reads are rare: a weekly report per station, and now and then a look at one station over one afternoon, and nobody minds if that takes a few seconds. Work out the parts of a contract for this workload, in the order in which the contracts chapter works them out, one or two sentences each, and name the assumptions that these promises need.
Then: This workload makes three separate promises. Name them, name the idea that keeps each one, and say which of the three costs something on every single write.
2.13.7 Fix the code, the box, or the design?
Each item starts from code that an AI wrote from one of the chapter’s design boxes, and something it did that looks wrong. Decide which of three things happened. The code breaks a promise in the box: fix the code. The code keeps the box but misses what you wanted: fix the box. The design keeps its promise, but its assumptions or its cost no longer fit the job: change the design. Say why.
Exercise 36 · middling · ~15 min
An AI writes an LSM-tree from its design box. Its memtable holds two entries, every flush is merged straight into the first level, and each level may hold twice as many as the one above. Its compaction drops every tombstone it meets, in every merge. Write a to f with the values 1 to 6, then delete a and write g. A read of a returns 1. Every batch on disk is sorted and never changed, and every level is within its budget: the store’s validity check passes. Which of the three is it, and why?
Then: Write a test you would keep from the AI that fails on this code, and say why checking the invariants could not catch it.
Exercise 37 · middling · ~15 min
An AI writes a left-leaning red-black tree from its design box, as an index of 100,000 product numbers kept on disk, each node in its own block. Every check of the tree passes, and every lookup is right. But a lookup reads 16 blocks on average and up to 22, and one read from the disk costs far more than all the comparisons. A colleague says the tree must be out of balance. Which of the three is it, and why?
Then: Rewrite the lines of the box that no longer fit the job, and say what you would measure to check the new design.
2.13.8 Derive the standard tree’s insert repair, without being told it
Exercise 38 · hardest in the chapter · ~120 min
It builds on the appendix on the standard red-black tree: read that first.
You already have:
- the 2-3 tree behind LLRB, and why LLRB’s three moves are what they are
- the appendix’s encoding: a black node with its red children is one node of a 2-3-4 tree (black alone = 1 key, +1 red = 2 keys, +2 reds = 3 keys)
- the B-tree section, where you traced splits at minimum degree t = 2
The appendix states the standard tree’s five invariants and stops. It does not give you its repair procedure. Derive it. Then say what the analogy was: which object mapped to which, and which move mapped to which.
Three checks tell you whether you got it right:
- Predict, before running anything: which is more common on random keys, the split (the key lands in a full node) or the absorb (the node has room)? By roughly what ratio? Then measure it.
- Check your procedure against a real one. The companion library ships a standard red-black tree, built to the textbook rules rather than this chapter’s:
algodesign.searching.RBTree, inred_black_standard.py. This is the oracle, the reference against which you check. First, after every insertion, check that your tree holds exactly the keys inserted and keeps the five invariants. Then run its repair over the same keys and compare the trees node by node. A mismatch may be a bug, or a different, also valid, repair procedure for the same rules: say which yours is, and why. Splitting full nodes on the way down, as this chapter’s B-tree does, is one such procedure. The next check is about exactly that. - Now a comparison that does not come out equal. Build the same keys as a B-tree at t = 2, and group the library’s
RBTreeinto its 2-3-4 nodes. Both are 2-3-4 trees on the same keys. They are often different 2-3-4 trees, though they never differ on eight keys or fewer. Find the smallest key sequence where they differ, say what is still true of both, and explain the difference. It comes down to one line in the two procedures.
Then two questions:
- How many distinct routes reach this derivation? Find as many as you can, say what each one takes as given, and show they agree.
- Harder. Every structure in this family keeps the same headline promise: the height stays within a constant factor of log₂ n, so search, insert and delete are all logarithmic. How many different sets of rules keep it? Not: how many ways to derive one set. How many sets are there, and what separates them?
Stretch: Now try deletion the same way. Fair warning: this one is harder and the analogy is looser. Say where it stops being an analogy.
Put this somewhere you’ll see it in about a week, and when you do, answer from memory first, with no scrolling back and no AI. Getting it wrong and then looking is the point. Looking first is not the point.
Name the six structures in order, and for each of the first five, name the assumption that broke and forced the next structure.
Draw the four-key tree that a sorted arrival builds, and say what a lookup in it costs.
What are the two red-link invariants, and what does each of the three repairs fix?
A node holds a thousand keys instead of one. Which cost went down, which went up, and why does the trade pay off only sometimes?
Something is written down but not yet filed, and the power goes out. What is lost, and what makes sure nothing is lost?
A sign-up page checks “is this username taken?” with a Bloom filter in front of the user database, and says taken whenever the filter says “maybe”. Every test passes. What did the design assume, what one requirement would you add, and what test would have caught it?
NoteAnswer to question 6: the username filterIt assumed “maybe” means “yes”, so some free names are refused. The requirement: a name is reported taken only if the database holds it. The test: try names you know are free, and count how many come back taken.
Pick one of the chapter’s design boxes and write it from memory. Say what it promises, what its idea and invariants are, and on what its cost depends. If it assumes anything, say what you would see if that assumption broke. Then open the box and compare.
Without opening the figure, write each of the six structures as the ideas of which it is made. Then compare with Figure 2.27.
NoteAnswer to question 8: the mapCompare with Figure 2.27. A different split counts if you can say which idea does which job in the structure. The figure is one way to draw it.
Whichever of those you couldn’t reconstruct is the one to reread, and only that one. If you got all eight, come back again in a month instead.
2.14 ★ Frontier map advanced
What follows is optional, a short tour of a few ideas sitting just past the edge of this chapter. Skip it now if you’d rather move on, and come back to it later.
2.14.1 What order costs, proved
Predecessor lower bound
The chapter has one lower bound already. A search by comparisons needs about \(\log_2 n\) of them, because each answers yes or no. Hashing steps around that bound by not comparing at all. For “is this key present” it wins outright. A hash table built for a fixed set of keys can answer in a constant number of steps in the worst case, using space proportional to the keys [30]. So the fair question is whether that escape works for the ordered questions too. Can some cleverer arrangement of machine words answer “what is the largest key at or below this one” in constant time, if it is allowed to compute on the keys’ bits instead of comparing them?
Not in general, and this time the answer is a theorem. Suppose a model counts only reads of memory and lets every other computation be free. In that model, the number of reads that predecessor search needs is known to within constant factors for every combination of key count, key length and space [31]. It is constant only at the extremes, with keys so short that a table with one slot per possible key fits in the space, or with machine words long enough to hold many keys at once. Everywhere between, with space not much larger than the keys, it grows with the number of keys, their length, or both, depending on how much space there is. The van Emde Boas tree comes close to the bound for some of those combinations, taking about \(\log_2 w\) steps for \(w\)-bit keys by searching over the bits of the key. Membership is constant. Predecessor, between those extremes, is not constant and cannot be constant. That is the precise price of the order that this chapter has been paying to keep.
The bound holds unconditionally. No unproved conjecture is holding it up. Many “we cannot do better” statements in this subject hold only if some widely believed conjecture is true. The same kind of reasoning about memory reads is still producing new unconditional bounds for problems whose data keeps changing [32]. When someone says an algorithm cannot be improved, the first question is which of the two kinds of claim they are making.
Signature: someone claims constant-time ordered queries, the next key or a range, on arbitrary keys. Reach for this bound to ask what they are assuming: keys so short a table covers them all, machine words long enough to hold many keys, or far more space than the keys themselves.
2.14.2 The best possible tree, when you know what gets asked for
Optimal binary search tree
Every tree in this chapter treats its keys as equally likely to be wanted. Real workloads don’t want them equally. Given \(n\) keys and a known access frequency for each one, there is a provably best static tree, the one minimizing total frequency-weighted search cost. It is the actual optimum for a known query pattern, though not necessarily the shortest tree.
A greedy rule won’t find it. Compression codes, where a similar-looking tree problem is solved greedily, get away with it because there every item hangs at a leaf. So the tree is free to put the frequent ones nearest the top in any arrangement it likes. A search tree can’t do that. Its keys sit at every level, and the ordering property fixes which key may go where.
Finding the best tree needs dynamic programming, which takes \(O(n^3)\) time to try every possible root for every contiguous range of keys. It drops to \(O(n^2)\) because of something that Knuth noticed. Add a key on the right of a range and the best root never moves left. Add one on the left and it never moves right. So each range’s best root lies between the best roots of its two slightly shorter neighbors. The search only tries the keys between those two roots, instead of scanning the whole range again [33], [34]. Yao later traced that monotonicity to a more general condition on the costs, the quadrangle inequality, which speeds up a whole family of dynamic programs the same way [35].
Signature: a workload where a small, known set of keys takes most of the traffic. Reach for it when those frequencies stay stable. It gives up change of every kind. It is built once, for that pattern.
2.14.3 Cost trade-offs and the RUM conjecture
The RUM conjecture
A good trade-off doesn’t try to make all the costs equal. It spends more of whichever resource is cheap to save a larger amount of whichever resource is expensive. The B-tree is the clearest example already in this chapter. It spends comparisons without counting inside the nodes it fetches, to avoid paying for one more access. The RUM conjecture from the LSM-tree section says such trades are forced. No index is known that keeps reads, updates and memory all small at once, but it is still a conjecture, not a theorem [36].
The same shape shows up earlier in the chapter too. The red-black tree spends a little extra comparing and rotating on inserts to avoid the far larger cost of a lookup walking down a degenerate, sequential-search-shaped tree. Sortedness itself is a trade. The sorted array spends a shifting cost on insertion to buy a cheap halving cost on every search after it.
2.14.4 Self-adjusting and learned structures
Splay tree, treap, skip list, learned index
Everything built so far is one of two kinds, static or dynamically maintained. Three more kinds lie past them. Self-adjusting. A splay tree [37] reshapes itself on every access, even a lookup that changes nothing. It walks the node just reached up toward the top, using the same rotate left and rotate right already familiar from the red-black tree. The splay tree’s inventors conjectured that over any long run of accesses a splay tree is within a constant factor of the best binary search tree that knew the whole run in advance and could rearrange itself for it [37]. That conjecture is still open. For decades the best anyone could prove for an adapting tree was a different design, the tango tree, which comes within a factor of \(O(\log \log n)\) of that best tree [38]. In July 2026 splay trees were shown to be within a factor of about \(\log_2 \log_2 n\) as well, up to smaller terms [39].
Randomized. A treap [40] and a skip list [41] get their balance from randomization instead of bookkeeping. The treap gives every key a random priority and keeps the tree a heap on those priorities as well as a search tree on the keys. The skip list stacks sorted chains in layers, each holding a random half of the chain below. Both keep the balanced tree’s bound in expectation [42]. The skip list is also far easier to share between threads than a tree that rearranges itself. The randomization chapter gives the skip list its full treatment.
Learned. A learned index gives up walking node to node at all. It guesses from the keys where a query key sits in a sorted array, then searches outward from the guess [43], and beats binary search only while its guesses land within about \(\sqrt{n}\) positions [44]. That was the proposal, made for keys that sit still and are only read. With keys changing, the newer learned indexes won most settings on one thread and slowed down once many threads shared them [45]. And whoever chooses the keys can poison the model, making one index up to 120 times larger [46] and slowing another’s lookups [47].
The appendix works each of the four through.
Who chooses your keys, and does your structure keep its bound when they are chosen against you?
2.14.5 Trees that can prove what they hold
Merkle tree
So far you have always been the one holding the structure. Suppose you are not. Suppose the index lives on somebody else’s machine, you ask it for one key, and it hands back an answer. How would you know it was not simply made up?
An authenticated, or Merkle, tree answers that by having each node store a cryptographic hash of the nodes beneath it. The single hash at the top is then a fingerprint of the entire contents. Change one key anywhere and every hash on the path up to the top changes with it. To convince you that some key really is in there, the server sends only the key, plus the handful of sibling hashes along the path from that key to the top, about \(\log_2 n\) of them. You recompute your way upward and check that you land on the fingerprint you already had.
That is the fingerprint primitive from the Bloom filter, put to a different job. There it made the filter small. Here it delivers trust. The trade is the same shape, a small thing standing in for a large one, on terms you can state exactly. Verify, rather than trust is what makes these trees the backbone of version control, of certificate transparency logs, and of the best-known distributed ledgers [48].
Signature: the data sits on a machine you do not trust, and every answer has to come with evidence you can check against a small fingerprint you keep yourself.
2.14.6 Search without a map
Navigable small-world graphs
Look at how a skip list searches, which the appendix walks through. The search only ever knows the links leaving the key on which it stands. It takes whichever link gets it closest to the target without overshooting. There is no global picture and no plan, only one greedy step at a time. The levels make it likely that a step exists which cuts the remaining distance by about half.
Now take away the levels and keep only the greedy walk. A collection of points, each linked to a few others, and a search that moves, at every step, to whichever neighbor is closest to the target. When does that work?
The obvious answer is “when short paths exist,” and it is wrong. Link each point to a handful of others picked uniformly at random, and short paths exist between everything. A random graph like that has paths of about \(\log_2 n\) links between any two points. Greedy search cannot find them. From where it stands, a link to a random point is almost always a link to somewhere far away. None of those far links knows anything about the neighborhood of the target, so the last stretch has to be walked step by step. Short paths existing and short paths being findable are different properties.
Kleinberg found exactly what the second one needs [49]. Put the points on a grid, link each to its grid neighbors, and give each point one extra long link, landing at distance \(d\) with probability proportional to \(d^{-r}\). On a two-dimensional grid, greedy search finds short paths when \(r = 2\). For every other exponent it needs a number of steps that grows as a power of \(n\). The good exponent is unique, and it equals the grid’s dimension. At that value, every scale of distance gets about the same share of long links. So wherever the search stands, its long link has about a one-in-\(\log_2 n\) chance of leading roughly halfway to the target. That is the skip list’s idea again, arrived at from the other side, though the walk takes about \((\log_2 n)^2\) steps, a factor of \(\log_2 n\) more.
The figure draws link lengths on a line of 64. The table below measures greedy search on a ring, the same one dimension with no end where a search could fall off. There the good exponent is 1, the ring’s dimension. Each point has one long link, and each entry averages 300 greedy searches between random pairs.
Multiply the points by 256 and the uniform ring’s searches get about 16 times longer, while the \(r = 2\) ring’s searches get 141 times longer. On the ring whose exponent matches its dimension, they get about 4 times longer.
The same construction keeps being found independently. Chord is a lookup scheme for machines on a network [50]. It places machines at identifiers on a ring and gives each machine links to the machines responsible for the identifiers \(1, 2, 4, 8, \ldots\) ahead of its own. That is exactly one link at every scale. Embeddings are lists of numbers standing for texts or images, where nearby lists mean similar things. HNSW, the index behind much of today’s search over embeddings, stacks graphs of points in the way a skip list stacks its chains, and its authors describe it by that analogy [51]. The metric skip list is one of the standard structures for exact nearest-neighbor search [52].
The full picture has three parts. Links alone buy short paths. The right links buy paths that a greedy search can find. And being findable costs space. The sparsest graph on which greedy search always reaches its target can need on the order of \(n\sqrt{n}\) edges in the worst case, which is one reason deployed indexes aim only at being almost navigable [53]. What that costs is measurable too. Several popular indexes have hard inputs [54]. On them, a query was measured to take a number of steps linear in the size of the data before it reached any of its true nearest neighbors. Where the data has few effective dimensions, the guarantees are much better [55]. That assumption belongs in the contract of any index built this way.
Signature: nearest-neighbor search over points with many dimensions, where there is no order to halve. Reach for it when a near answer is acceptable and the data has few effective dimensions. The geometry chapter builds one of these indexes from the ground up.
2.14.7 Taken further: removing the last lock
Bw-tree
Copy-on-write, from the LSM-tree section, frees the readers, and leaves one writer at a time rebuilding a path. The Bw-tree goes the rest of the way [56]. A node is not rewritten on each update, not even as a copy. An update is appended as a small record describing the change, chained in front of the node. Nodes are reached through a table of addresses, which each writer updates with a single atomic compare-and-swap. That is one hardware instruction that replaces a value only if it still holds what the writer last saw, so many writers can proceed at once without anyone holding a lock. Old records are freed only once no thread can still be looking at them. Read the original paper beside the report of a second team that built one from the published description and recorded how much the description had left out, and on how much tuning its speed depended [57].
Signature: many threads writing the same ordered index at once, where a lock on the hot path is the bottleneck. Reach for it with the second team’s measurements in hand.
2.14.8 Could the whole chain choose itself?
Every design in this chapter got chosen by hand: look at the problem, look at the workload, look at the hardware’s limits, then pick a representation and an algorithm to match. Could that whole chain run itself one day, choosing its own structure the way this chapter chose one, step by step, without a person first walking through what each candidate takes for granted? Pieces of this already exist: a query optimizer picking a plan for a stated workload, autotuning that searches over implementations for a given machine, a learned index inferring its own guess straight from the data. But as of 2026 no single mature system runs the process end to end, from a raw problem statement through a workload and a machine’s limits to a chosen structure, on its own.
The useful question, one you can still answer years from now, is what would such a system have to show you before you believed its choice? This chapter has already given you the form of the answer, in its lists of what each structure takes for granted. Three things, and no fewer:
- the assumption it made about your workload: not its accuracy on someone else’s benchmark, but what it took to be true of yours, stated plainly enough that you can check it;
- what breaks that assumption: the input, the access pattern, the hardware change that would make its answer wrong, named by the system before you meet one in production;
- what it costs when that happens: whether it degrades gently or falls off a cliff.
A system that gives you all three is one you can argue with, and so one to which you can delegate. A system that gives you a structure and a confidence score has told you nothing you can check, however good the structure turns out to be. Those three things are the same test you have put to yourself for every structure in this chapter. The test does not get weaker when the chooser stops being a person.
Algorithms are not solutions in isolation. They are solutions under assumptions, and that stays true no matter who or what picked them.
2.15 ★ Appendix: deleting any key from the red-black tree advanced
The main text took out only the smallest key. This appendix takes out any key. The code, with its tests, is in the companion library, in llrb.py.
A walk that may turn right needs the counterpart of move_red_left. It is shorter, because a left-leaning tree keeps its spare red links on the left. Read it as a black box too. Hand it a node whose next step to the right is a 2-node, and it hands back one whose next step is not a 2-node.
move_red_right, Python.
Deleting an arbitrary key is the same idea, run in both directions. Walk toward the target, calling move_red_left or move_red_right depending on which way the walk turns. Once the target node is reached, splice it out exactly the way a plain binary search tree would splice it out. Copy the successor up if the target has two children, and remove the target directly if it does not have two children. That last step is safe because the walk down has already guaranteed this node is never a 2-node.
Watch the walk take out 20, the key at the top of the tree that those same five keys built. The node that leaves is lower down.
At the top. The walk compares first. 20 is not smaller than 20, so this is the here-or-right branch. That branch opens with one rule. If this node has a red link on its left, rotate right. In a left-leaning tree the right side never has a red link of its own. So before the walk might turn right, it brings one over from the left. Node 20 has a red link on its left, so the tree tips. 10 comes up to the top, and 20 slides down to the right, arriving on a red link. Nothing has been deleted yet. The target has simply been moved somewhere safer to work, somewhere it already has the spare that deletion needs.
At 10, now on top. The walk is standing on 10, and 20 is larger, so it turns right. Is the next node a 2-node? No. It has just arrived there on a red link, so it already carries a spare, and move_red_right has nothing to do. The walk steps down.
At 20, one level down. This is the key to delete, and it has nodes on both sides. A node with two children cannot simply be spliced out, because one hole cannot hold two subtrees. So it is not removed at all. Its key is replaced by its successor, the smallest key on its right, which is 30. But the walk has to be able to step down that side first, and both 30 and 30’s left side are black. move_red_right fires. flip_colors turns 20 black and turns 15 and 30 red, and the right side now carries a spare.
The substitution. Copy 30’s key into this node, then run the delete_min walk on the right side, the same walk as before, on a side that now has what it needs. This is where the earlier walk proves its use, and where its name becomes misleading. Here the walk is removing the successor from the place it used to live. The successor is the leftmost node of the right subtree, the minimum of that side, so it has no left child and its removal is the easy case. The two-children problem is never met twice. The right side is only the one node, holding a red link when it goes, so removing it takes no black height away anywhere. What’s left here is a node holding 30, with 15 hanging red on its left.
Back up. fix_up looks for the three broken shapes and finds none. The top node is already black. Done. Four keys (10 at the top, 5 on its left, 30 on its right with 15 red beneath it), every invariant intact.
Both repairs came before any deleting. The rotation moved the spare key to the side toward which the walk was heading, and flip_colors, inside move_red_right, put one on the side that the successor was about to leave. Their only job was to put the target somewhere it could be deleted safely. That is what “arrange it on the way down” means in practice.
It is also where the match with the 2-3 tree stops. The walk down borrows ahead of time, the way the B-tree’s deletion tops up a node before stepping into it. On the way it passes through shapes that no 2-3 tree has: a red link on each side of a node, a red link leaning right. The tree it leaves is always valid, so it always reads as some 2-3 tree, but not always the one that a 2-3 tree’s own deletion would give. Build the 2-3 tree [24 35] over [9], [31] and [38 39], and take out 31. The 2-3 tree borrows from its neighbor: 38 rises, 35 comes down, and the result is [24 38] over [9], [35] and [39]. The left-leaning tree merges instead and ends as [35] over [9 24] and [38 39]. Same keys, same height, both valid, different trees.
One detail in there contradicts something settled earlier in this chapter. The plain tree’s deletion section chose moving the node over copying the key out of it, so that outside code holding the successor’s node still refers to a node in the tree. This tree copies the key on purpose. The trade comes out the other way here, because a node holds something that a plain tree’s node didn’t hold. It holds a color, and that color is a claim about the path on which it sits. Copy a key and every color stays exactly where it was and every claim still holds. Move a node and it has to take over the color of the node it replaces, because the color belongs to the place. That is one more thing to get right whenever the successor fills a gap. The guarantee chosen earlier is real, but here this structure does without it.
Step through the deletion traced above, one move at a time, then delete keys of your own and say which of move_red_left and move_red_right will fire before each step.
2.16 ★ Appendix: cache-oblivious variant advanced
Cache-oblivious layout (van Emde Boas)
The B-tree in the main text fits its node to the block, but the memory hierarchy in the contracts chapter has several levels. Each level moves data in blocks of a different size: a cache line of a few dozen bytes, a page of a few kilobytes, and a flash block that is much larger. A node sized for one of them is the wrong size for the others. Which one is it supposed to fit?
Surprisingly, you do not have to choose. Take a balanced binary search tree that no longer changes, and lay it out in memory by one recursive rule. Cut the tree at half its height. Store the top half first, laid out by the same rule. Then store each subtree hanging below the cut, one after another, each laid out by the same rule. Whatever the block size turns out to be, at some depth of that recursion the pieces are about the size of a block, and each is stored contiguously. So a search fetches at most a few times as many blocks as a tree tuned to that size would fetch, though the layout never knew the size. This is the van Emde Boas layout. A structure that gets its fetch bound this way, with no block size anywhere in its code, is called cache-oblivious [58].
A tree of about a million keys was laid out five ways. Each search was charged one fetch per distinct block it touched, and each entry averages 2,000 random searches (block sizes are counted in nodes).
| layout | blocks of 16 | blocks of 256 | blocks of 4,096 |
|---|---|---|---|
| level by level, no tuning | 16.9 | 13.0 | 9.0 |
| tuned to 16 | 5.0 | 4.1 | 3.1 |
| tuned to 256 | 10.9 | 3.0 | 2.9 |
| tuned to 4,096 | 13.9 | 6.0 | 2.0 |
| van Emde Boas | 7.6 | 3.8 | 2.1 |
Each tuned layout wins at the size for which it was tuned. The one tuned for big blocks is almost as bad as no tuning at all when the blocks turn out small. The recursive layout never wins a column and is never far behind the winner in any of them. Its appeal is portability. A structure tuned to the one level that actually dominates a given machine can do better there. Reach for the recursive layout when the code has to run well on machines you will never see.
2.17 ★ Appendix: splay trees, treaps, skip lists and learned indexes advanced
The frontier map named these four structures. This appendix shows how each one works.
2.17.1 Splay tree
Three named moves do the walking. Which one fires is decided by where the node sits relative to its parent and grandparent, and by nothing else:
- zig: the parent is the root. One rotation, and the walk is over.
- zig-zig: node and parent lean the same way. Two rotations, which fold the whole chain upward together.
- zig-zag: node and parent lean opposite ways. Two rotations, which straighten the kink before lifting.
The zig-zig move is what makes splaying work. A naive “rotate it up until it reaches the top” would also put the node at the top, but the long chain that the node climbed would stay almost as long as it was. Rotating the upper pair first folds that chain in half on the way past, which is why a splay tree gets faster over a run of accesses and a naive lift does not get faster.
Keys reached often end up close to the top on their own, and keys rarely touched drift down. There’s no colored link and no rule to check or repair. The shape adjusts itself purely from which keys get used.
2.17.2 Treap and skip list
That self-adjusting trick carries three costs. The next idea is a direct answer to them [42]. Restructuring the whole path to the top happens on every access, even a plain lookup that found what it wanted and changed nothing. A single one of those restructurings can still take as many rotations as the tree is deep. And the guarantee that makes splay trees famous is an amortized one. It says that a long run of operations is cheap on average, and says nothing about the operation you are waiting on right now, which may be a request with a deadline.
A treap is a binary search tree plus randomization. It answers that critique with a different trade. Give each key, alongside its place in the order, a second number picked at random when it’s inserted, its priority. Keep the tree simultaneously a binary search tree on keys and a heap on priorities, the larger priority always sitting above its children [40]. For any fixed set of key–priority pairs, with no two keys and no two priorities equal, there’s exactly one tree shape satisfying both invariants at once. So a new key goes in as an ordinary node and rotates upward only while its priority beats its parent’s priority. It ends up wherever that one shape puts it. The shape comes out as if the keys had arrived shuffled, in whatever order they came. Because the priorities are random rather than chosen, an expected constant number of rotations, at most two on average, settles an insert or delete, and the tree stays within a constant factor of balanced with one priority repair and no color cases [42]. It is the red-black tree’s balance kept by chance instead of bookkeeping, and so kept on average over the coin flips, for every arrival order. Any one tree it builds can still be unlucky.
A skip list uses the same coin on a different shape [41]. Drop the tree entirely and keep an ordinary sorted chain of keys, then, above it, a second chain holding a random half of them, and above that a chain holding a random half of those, and so on up. Searching starts on the sparsest chain at the top and walks forward until the next key overshoots, then drops one level and walks forward again. So each level cuts the remaining stretch about in half, the same halving the tree does, laid out sideways. Nothing in a skip list is rotated, recolored or repaired. A new key flips coins to decide how many levels it appears on, and that is the entire balancing discipline. The result is within a constant factor of \(\log_2 n\) with high probability. The structure is also far easier to make safe for many threads at once than any tree that rearranges itself, which is why skip lists turn up inside databases and in-memory stores.
2.17.3 Learned index
On the keys already present, train a function that estimates where any query key should sit in a sorted array [43]. Probe that guessed spot directly, and if it’s wrong, don’t fall back to a blind halving search. Step outward from the guess, doubling the stride each time, then finish with an ordinary binary search once the true position is bracketed between two probes. A guess that’s off by \(\eta\) positions costs about \(2\log_2 \eta\) probes to recover [44]. The guess replaces the walk through explicit structure. A wrong guess costs extra probes, but the steps outward and the binary search after them still find the right position.
Put real numbers on that. Half a million keys, sorted. Plain binary search finds any one of them in at most 19 probes. Now let the model guess, and suppose it lands within 400 positions of the truth. Step out 1, 2, 4, and on up to 512 positions to bracket the answer, about 10 probes, then binary-search the bracket, about 8 more. Call it 18 probes, against binary search’s 19. All that machinery, to save a single probe.
Push the guess to within 10 positions and it costs about 8 probes, a clear win. Let the guess miss by 2,000 positions and the search costs about 22 probes, which is worse than the plain halving search it replaced. In general, \(2\log_2 \eta\) beats \(\log_2 n\) exactly when \(\eta < \sqrt{n}\). For half a million keys that is a few hundred positions. A learned index is a bet that the data’s shape is regular enough to predict a position to within the square root of the collection’s size. The correction step is what makes losing that bet survivable.
Keys that arrive and leave while the index is being read are harder. One broad measurement put updatable learned indexes against each other and against ordinary trees, on ten real datasets. It ran them under changing key distributions and many threads at once, and judged them on speed, on memory, and on robustness [45]. On one thread the newer learned indexes won in over 80% of the settings tried. With many threads, some of the design choices that made them fast were at odds with keeping them safe to share, and they got slower. The study’s title asks whether they are ready, which is a question to ask of any structure that is fast on the benchmark with which it was introduced.
Robustness belongs on that list. A learned index models the distribution of the keys, so whoever controls the keys controls the structure. Any index that fits a model to its keys offers this lever, because it is the mechanism working as designed, turned against you. Insert keys chosen to be awkward for the model, and the model has to spend more of itself describing them. Poisoning 10% of the keys fed to one well-regarded learned index made it up to 120 times larger [46]. On another, which adapts its model as keys arrive, a stream of adversarial inserts slowed lookups by up to 2.8 times, while poisoning the keys it was first built from did little [47]. The balanced trees in this chapter keep their bound for every sequence of keys, so there is no lever of that kind on them. Written as a contract, the learned index’s assumption field says what the numbers above only implied, that the keys follow a shape that the model can learn and that nobody is choosing them against you.
Signatures, one each. A splay tree: a few keys take most of the traffic, nobody knows in advance which, and an occasional slow operation is acceptable. A treap or a skip list: the balanced tree’s bound, in expectation, with the least code, when nobody choosing the keys can see your coin flips, and the skip list especially when many threads share the structure. A learned index: keys that change rarely and follow a shape that a model can learn to within about the square root of the collection’s size, chosen by nobody working against you.
2.18 ★ Appendix: how the standard red-black tree relates to the left-leaning advanced
Outside this chapter you will usually meet a different red-black tree, the standard, either-leaning one [5], [13], of which LLRB is a deliberate simplification.
2.18.1 The five invariants
The main chapter colored links. The standard presentation colors nodes. These are the same information written two ways. Every node except the root has exactly one link coming down into it, so “this node is red” and “the link into this node is red” say the same thing. The link view made LLRB’s left-leaning invariant easy to state, since a lean is a property of a link. The five invariants below are traditionally written in the node view, so this appendix uses it.
Standard red-black trees are stated directly, as five invariants that a tree must keep true after every operation:
- Every node is colored red or black.
- The root is black.
- Every empty spot where a node could hang, but does not hang, counts as black.
- A red node’s children are both black.
- Every path from the root down to an empty spot crosses the same number of black nodes.
Compare this to LLRB’s invariants. Invariant 5 here is LLRB’s black-balance invariant, unchanged. Invariant 4 is LLRB’s “no two reds touching,” but only half of it. It forbids a red hanging directly below another red, and says nothing about a black node with a red on each side. And LLRB’s own extra invariant, “a red link always leans left,” is missing entirely. So the standard tree loosens two invariants. The shape that invariant 4 leaves open is the exact shape that LLRB gives up, a black node with a red child on both sides. It stands for three keys folded into one local piece of structure, sometimes called a 4-node, which a node holding only one key could not otherwise represent.
Draw that last paragraph and the five invariants stop being five things to memorize. The main chapter showed a 2-3 tree, whose nodes hold one key or two, becoming a left-leaning red-black tree. A 2-3-4 tree is the same idea with one more size allowed. A node may hold one key, two, or three. Translate each of those three sizes into plain nodes and red links and you get the entire vocabulary of the standard tree.
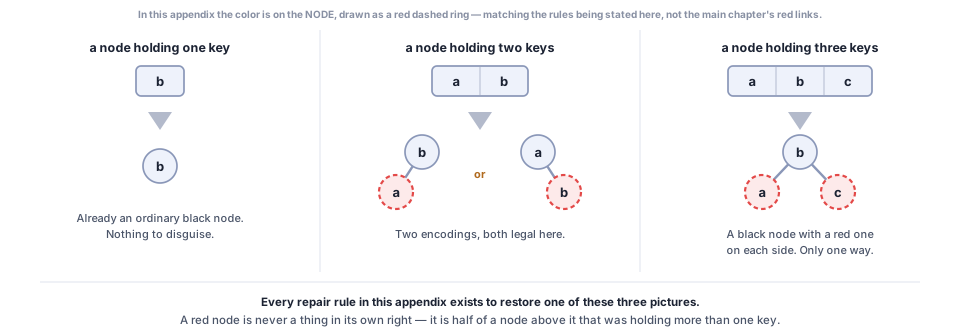
Read the invariants off that picture. A red node is never a node in its own right. It is part of the black node directly above it, which is invariant 4. A red whose parent is also red has no black node directly above it to which it could belong. Counting black nodes down a path counts the 2-3-4 nodes on that path, and a 2-3-4 tree keeps all its leaves at one depth, which is invariant 5, for free. The root is black because the top of a 2-3-4 tree is a whole node, which is invariant 2.
And the last two columns are the difference between this tree and LLRB, in one image. A two-key node has two legal drawings here, red on the left or red on the right, and the standard tree accepts both. LLRB forbids one of them. A three-key node is legal here, and LLRB never keeps one. The two trees share the same idea, with a different amount of freedom. Every extra case in the standard tree’s code is the price of that freedom.
2.18.2 What the extra freedom costs
The two trees part company on real input. Insert 10, 20, 30, 15 into each, in that order. LLRB rotates at 10 and finishes with 15 on a black link holding 10 as its red left child. The standard tree finishes the other way round, with 10 black and 15 as its red right child. That right-leaning red link is the very shape that LLRB’s extra invariant exists to forbid.
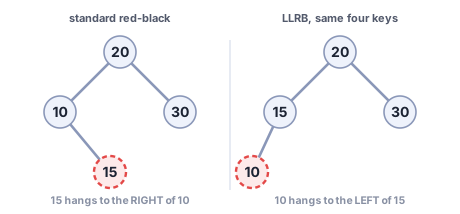
What the freedom buys is the one place where the standard tree is strictly ahead. Recoloring on either tree can climb all the way to the root, but the standard tree bounds the number of rotations per update. A single insert into the standard tree never needs more than two, and a single delete never needs more than three [5]. LLRB has no such constant bound. If what you need is a hard bound on structural work per operation, and not merely on height, that is the reason to reach for the standard tree.
What the freedom costs is case-handling, and a good deal of it. Every extra shape that the invariants permit is another situation that a repair has to recognize and another branch to get right. LLRB pays the other way, with more rotations and fewer cases and the same height bound.
The operations themselves are not developed here. They are in the standard references in full [2], [5], [12], and they will read as variations on moves you already have, which is the point of having derived this one from the same encoding.
You can test that claim. The last of the self-check problems (Section 2.13.8) asks you to derive the standard tree’s insert repair yourself, from how LLRB mirrors a 2-3 tree and how the standard tree mirrors a 2-3-4 tree.
In Lean,
deleteHibbard_eq_delete, inlean/AlgoDesign/Searching/BST/Delete.lean, proves that the two deletions are the same function; the Lean tree holds values and has no pointers. The test (python/tests/searching/test_variant_shapes.pyin the companion library) builds every distinct tree that up to five insertions of the keys 0 to 5 produce, 598 trees, deletes each of the keys 0 to 6 from each one, 4,186 deletions, and finds the same shape both ways every time.↩︎Three trees of 4,096 distinct random keys drawn from 0 to 40,959, seed 1, each built by inserting in random order and then half its keys deleted in another random order.↩︎
In the companion library’s
lean/AlgoDesign/Searching/LLRB/Delete.lean:valid_deleteTopproves that deletion preservesValid,mem_deleteTop_iffthat exactly the requested key leaves, anddeleteTopSpecbundles the two.↩︎The rounds and numbers come from one run, and each round was written by an AI given only that round’s brief. The briefs, the candidates and the script that judges them are in
scripts/design_run/in the book’s repository.↩︎